Field notes on Frontier Investigation Agents
Introducing Resolve
Resolve joins signal intelligence and AI investigation with a Memory layer, so 13K raw events become 40 actionable clusters and investigation starts on its own. This post walks one 3 a.m. cluster from suppression to a confirmed root cause, with every remediation gated by Auto Mode.
AgenticOps Needs Its Own Platform: Why a Coding Tool Can't Safely Connect to Production
Coding tools are built to turn intent into a diff, not to hold production credentials for a team. Using 2025 to 2026 incident data, this post maps six failure modes of laptop-credential access and walks one production change end to end through scoped credentials, a sandbox, Auto Mode and an audit log.
Meet Your Custom Agent
Generic AI doesn't know your stack, your playbook or your team. A Custom Agent does: name it, teach it, plug in only the tools you allow, and your whole team @mentions the same AI teammate in Slack, with every write going through Auto Mode.
CloudThinker Cyber vs AWS Security Agent on OWASP Juice Shop: 65% More Findings at 94% Lower Cost
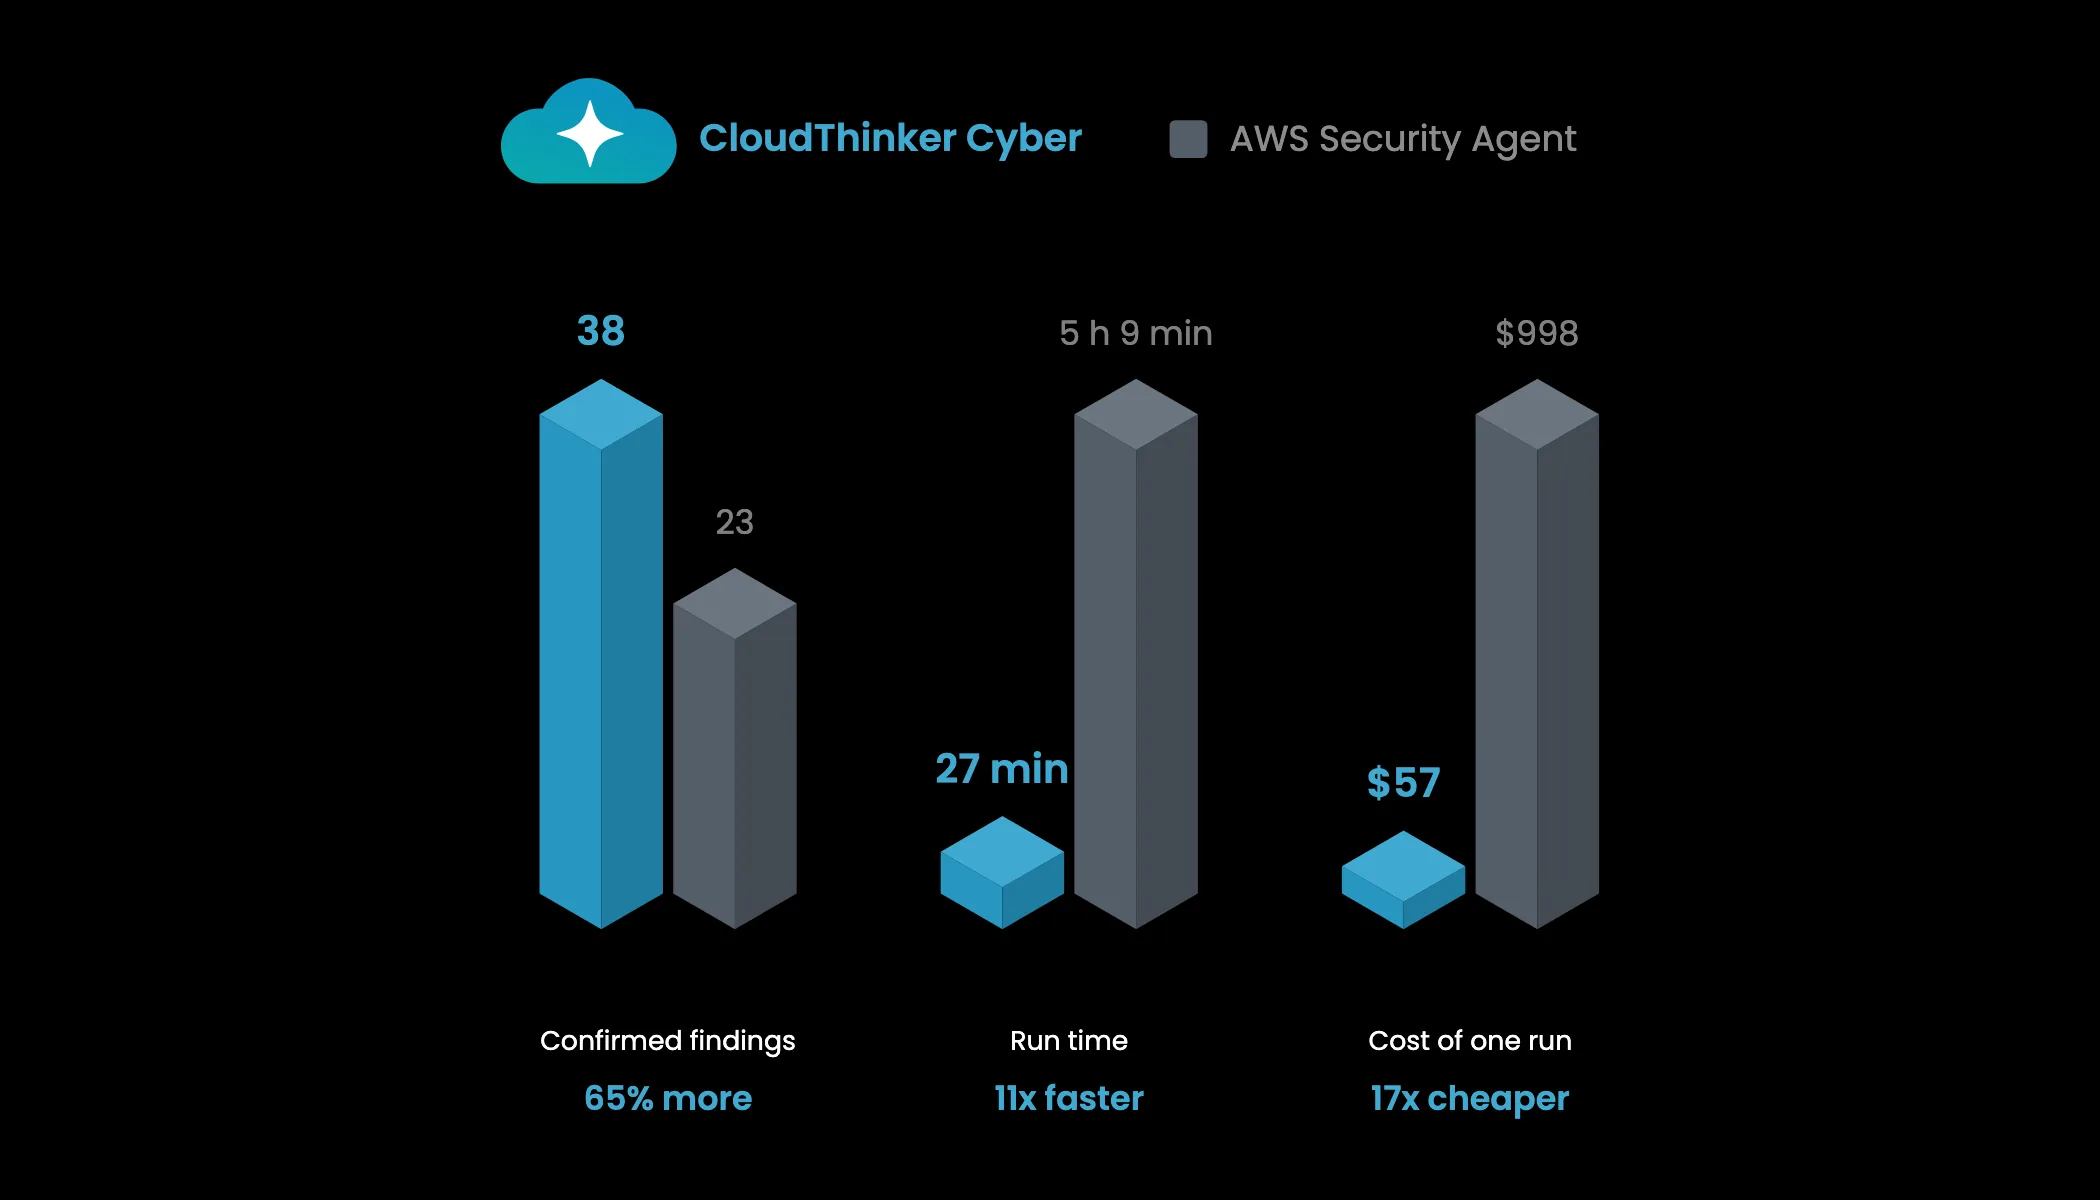
CloudThinker Cyber, our Frontier Security Agent, against AWS Security Agent in a black-box pentest benchmark on OWASP Juice Shop, one run each. CloudThinker Cyber confirmed 38 vulnerabilities in 27 minutes for about $57. AWS Security Agent reported 23 in 5 hours 9 minutes for about $998 at its $50 per task-hour list price.
Product
CloudThinker Cyber vs AWS Security Agent on OWASP Juice Shop: 65% More Findings at 94% Lower Cost
CloudThinker Cyber, our Frontier Security Agent, against AWS Security Agent in a black-box pentest benchmark on OWASP Juice Shop, one run each. CloudThinker Cyber confirmed 38 vulnerabilities in 27 minutes for about $57. AWS Security Agent reported 23 in 5 hours 9 minutes for about $998 at its $50 per task-hour list price.
Product
CloudThinker × Wazuh: From Alerts to Investigation
Connect Wazuh evidence across on-prem and AWS to build a case your SOC can review. Follow a practical workflow for targeted queries, clear data boundaries, and approved response.
Solutions
Your Best Engineers Should Be Building the Future
Every hour spent rebuilding an incident timeline is an hour your product roadmap never gets back. See how leaders can use CloudThinker to turn operational expertise into AI-driven execution, with lessons from Amela and F88 and a practical path from the first pilot to organization-wide adoption.
How To
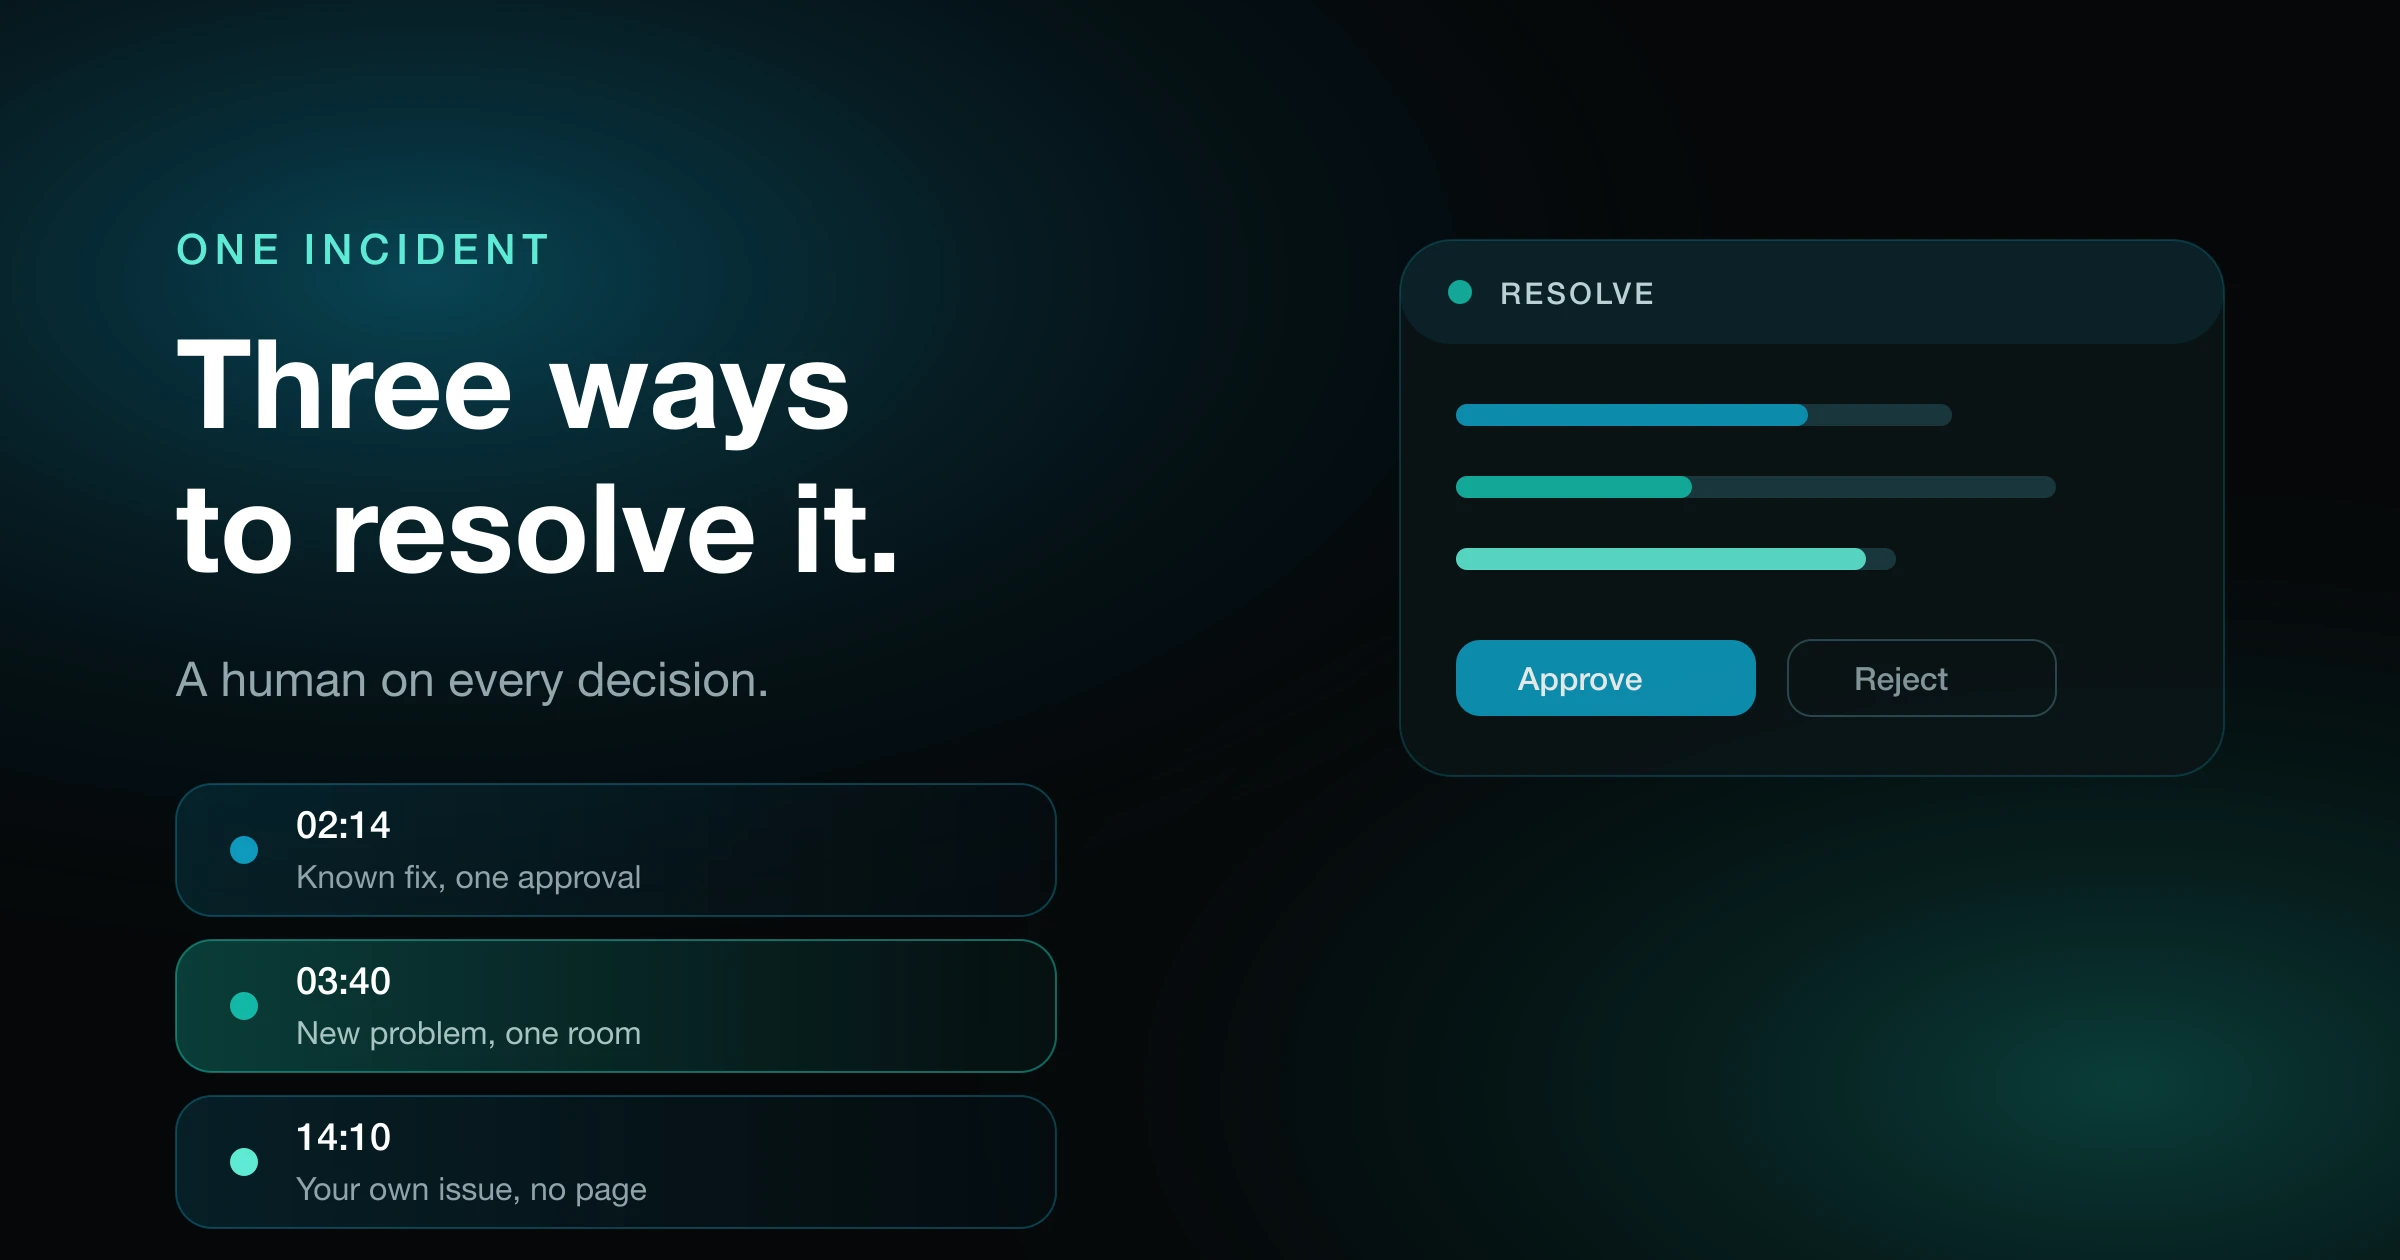
How to Use CloudThinker for Incidents: Three Ways, One Night
Three ways CloudThinker handles incidents in one night: a known fix approved from a phone, an incident room for something new, and a chat question that never becomes a page. Each comes with the exact settings to configure it.

Product
Your On-Call Has Not Met Astra Yet
We held the Resolve harness fixed and swapped seven models across 21 live SREGym Kubernetes faults. GPT-6 Astra closed every gradable fault at $3.53 per resolution, and the post explains why a single leaderboard row, or token price, is the wrong way to pick an incident model.
Solutions
The DevSecOps Review Prescription Guide: How to Review Thousands of Merge Requests a Month
A reference architecture for automated code and security review with production context: where review triggers, how one runtime runs two reviewers, and what lands back in the merge request. Walks one cross-tenant bug from MR to fix PR, with pricing at $0.12 per MR and the FPT Cloud and Diaflow reference deployments.
How To
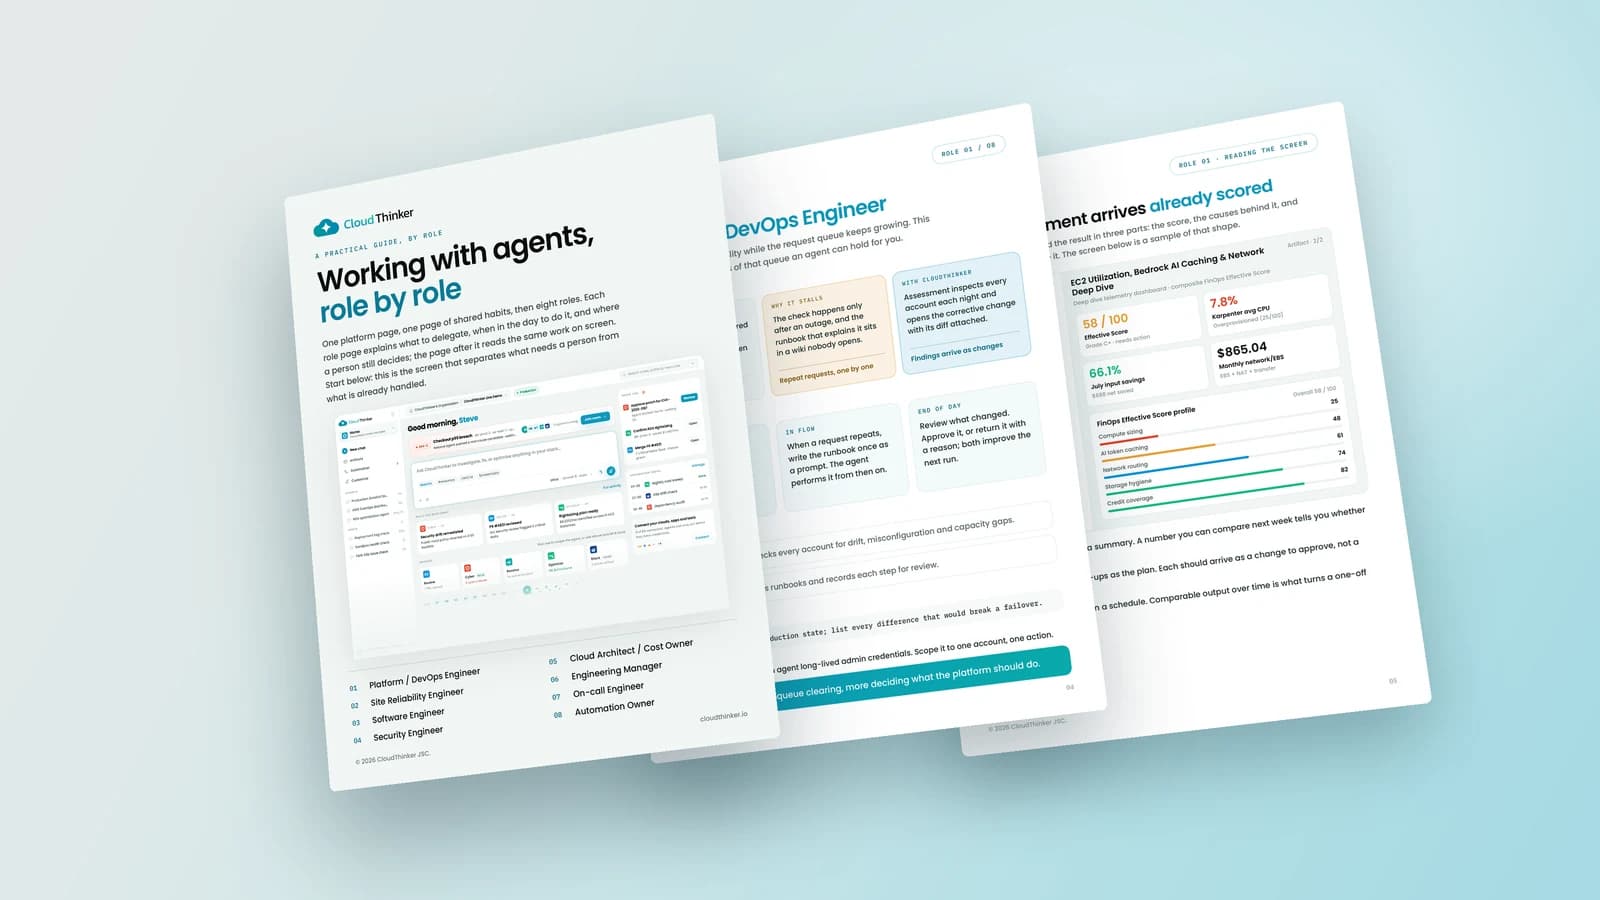
Working with Agents, Role by Role: A New Practical Guide
Most agent material is written for buyers. This free 19-page guide is for the eight roles who have to use agents on Monday morning, with a chapter shape per role, three shared habits, waiting time as the real metric, and a read-only first, Auto Mode rollout pace.
Market Insights
Unifying Your Production Operations Stack with CloudThinker
One AI assistant per tool repeats the old silos: partitioned context, credential sprawl, ungoverned automation and duplicated spend. This post walks one incident where shared memory rules out a cost change in seconds, sets out the security model that makes consolidation safe, and covers F88 and Diaflow results and a staged adoption path.
Market Insights
The 10 Best AI SRE Tools in 2026, Compared
A field guide to the ten AI SRE tools teams evaluate most in 2026, from CloudThinker and Resolve AI to Cleric, Traversal, Datadog Bits AI, incident.io, PagerDuty, Rootly, NeuBird and Metoro. It compares them on how far they close the loop, whether they verify the fix, and scope, and ends with a five-step way to run a fair evaluation on your own incidents.
Product
Ship daily. Pentest each deploy. Introducing CloudThinker AppSec
CloudThinker AppSec tests every deploy, proves each finding with a safe read-only exploit, and opens the fix as a merge request. The post walks one cross-tenant BOLA finding from discovery to proof, patch and retest.
Product
CloudThinker × Rollbar: From Error Detected to Issue Resolved in 3 Steps
Rollbar makes detection fast. The time goes in step two, when an engineer rebuilds context across five tools. This overview follows a reactivated pool-timeout Item that turns out to be a database problem caused by another team's job, and shows how CloudThinker investigates, picks the safest remediation and verifies the fix through Auto Mode.
Market Insights
From DevOps Engineer to Forward Deployed Engineer: the Career Path AgenticOps Just Created
AI agents are absorbing the execution half of DevOps while Forward Deployed Engineer postings grow 5,230%. This post argues they're the same shift, and maps the move for on-call engineers: encode runbooks as skills, run them through Auto Mode, and report outcomes.
Case Study
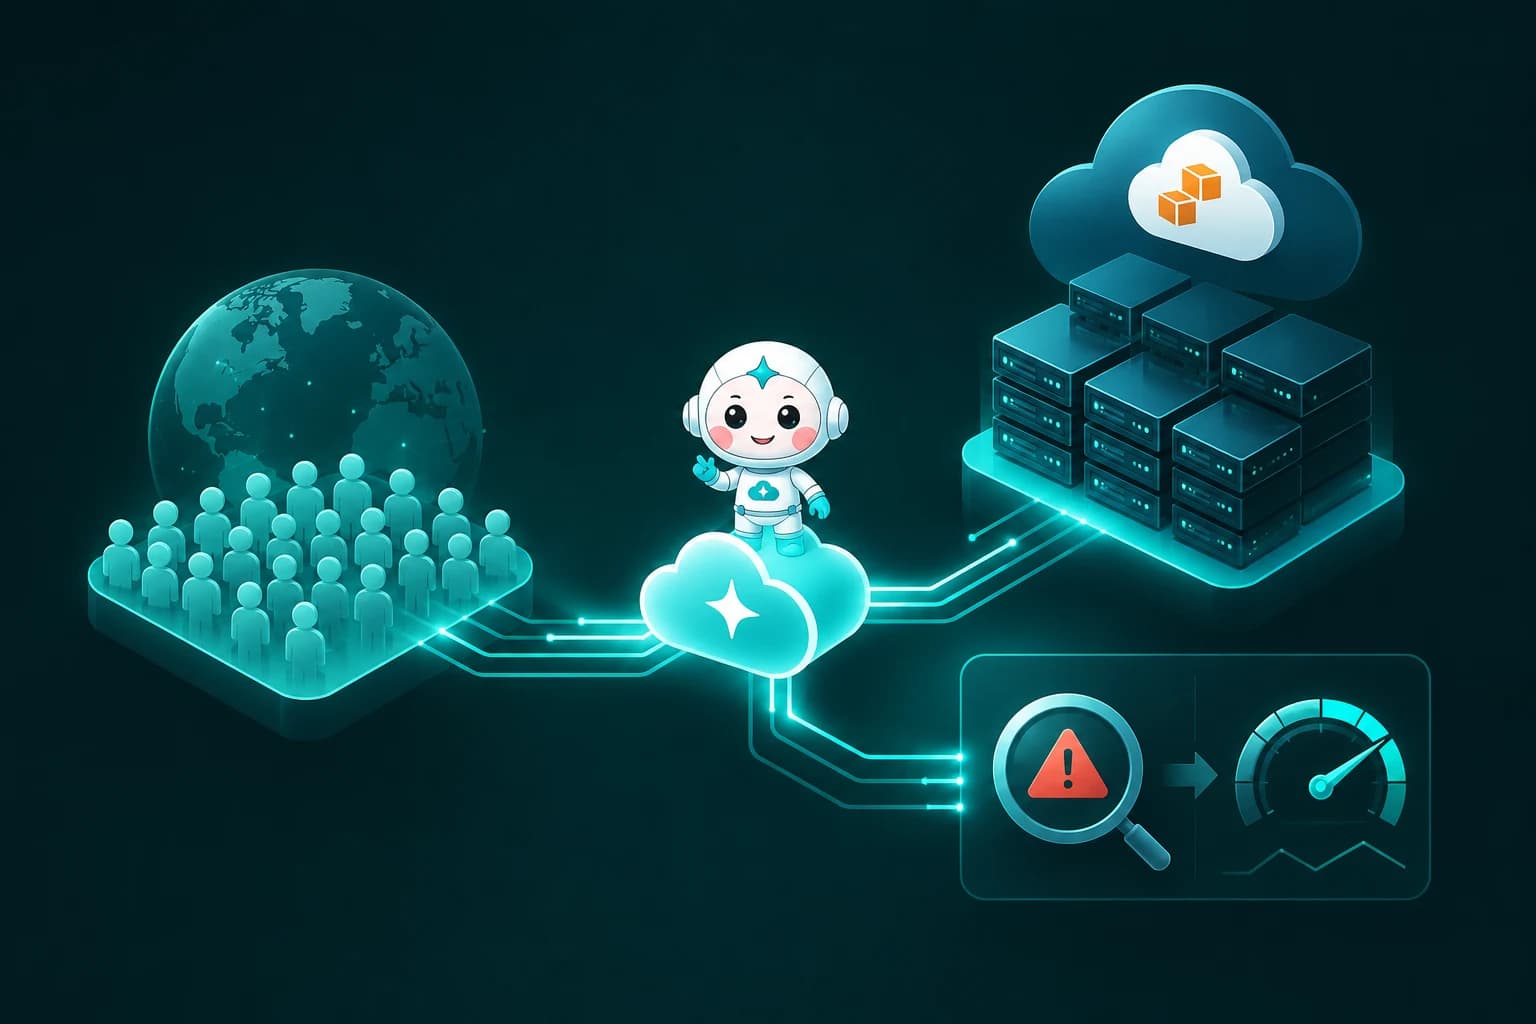
How Amela Turned AWS Incidents from Hours into Minutes with CloudThinker
Amela runs a high-traffic AWS application where a peak-time symptom could start in the code, the database, the network or an AWS limit. A Well-Architected review hardened the foundation, Resolve cut incident MTTR from hours to minutes with root cause and a validated fix in under 30 minutes, and moved detection ahead of impact.
Case Study
AI-DLC at HBLab: Faster Delivery and 24/7 Cloud Operations with CloudThinker
AI-assisted coding made HBLab write code faster, and the bottleneck moved downstream to review, QC and 24/7 operations across many customer environments. HBLab applied CloudThinker at three points in its AI-DLC (review, operate, report) and saved thousands of hours while keeping a human approval gate on production.
Case Study
How an Australian Telematics Provider Automates Day-to-Day Operations with CloudThinker
An Australian telematics provider runs Azure, its application platform and a flespi-fronted device fleet with a small team. This case study covers why per-layer tools and review habits break down under those conditions, and how CloudThinker now handles code review with Review, cost with Optimize, and a daily three-layer health check, with a person approving every production change.
Case Study
Inside the FPT Cloud Evaluation: How CloudThinker Review Held the First Quality Gate
Over five weeks, FPT Cloud evaluated CloudThinker Review on production merge requests. The team supplied context (requirement specs from code and Jira, plus curated rules) instead of tuning the model, which took the reviewer from a low baseline to ~97% precision with full backend logic coverage. 68.6% of all verified defects were caught at the merge request, before human review or QC.
Product
2:47 A.M. in Someone Else's Production: Inside CloudThinker's On-call AgenticOps Team
What one 2:47 a.m. page looks like when an agentic engine investigates and a human SRE approves from her phone. How CloudThinker's on-call team is wired, how a fix earns Auto, the nights the agent was wrong, and the actions it can never take.
Product
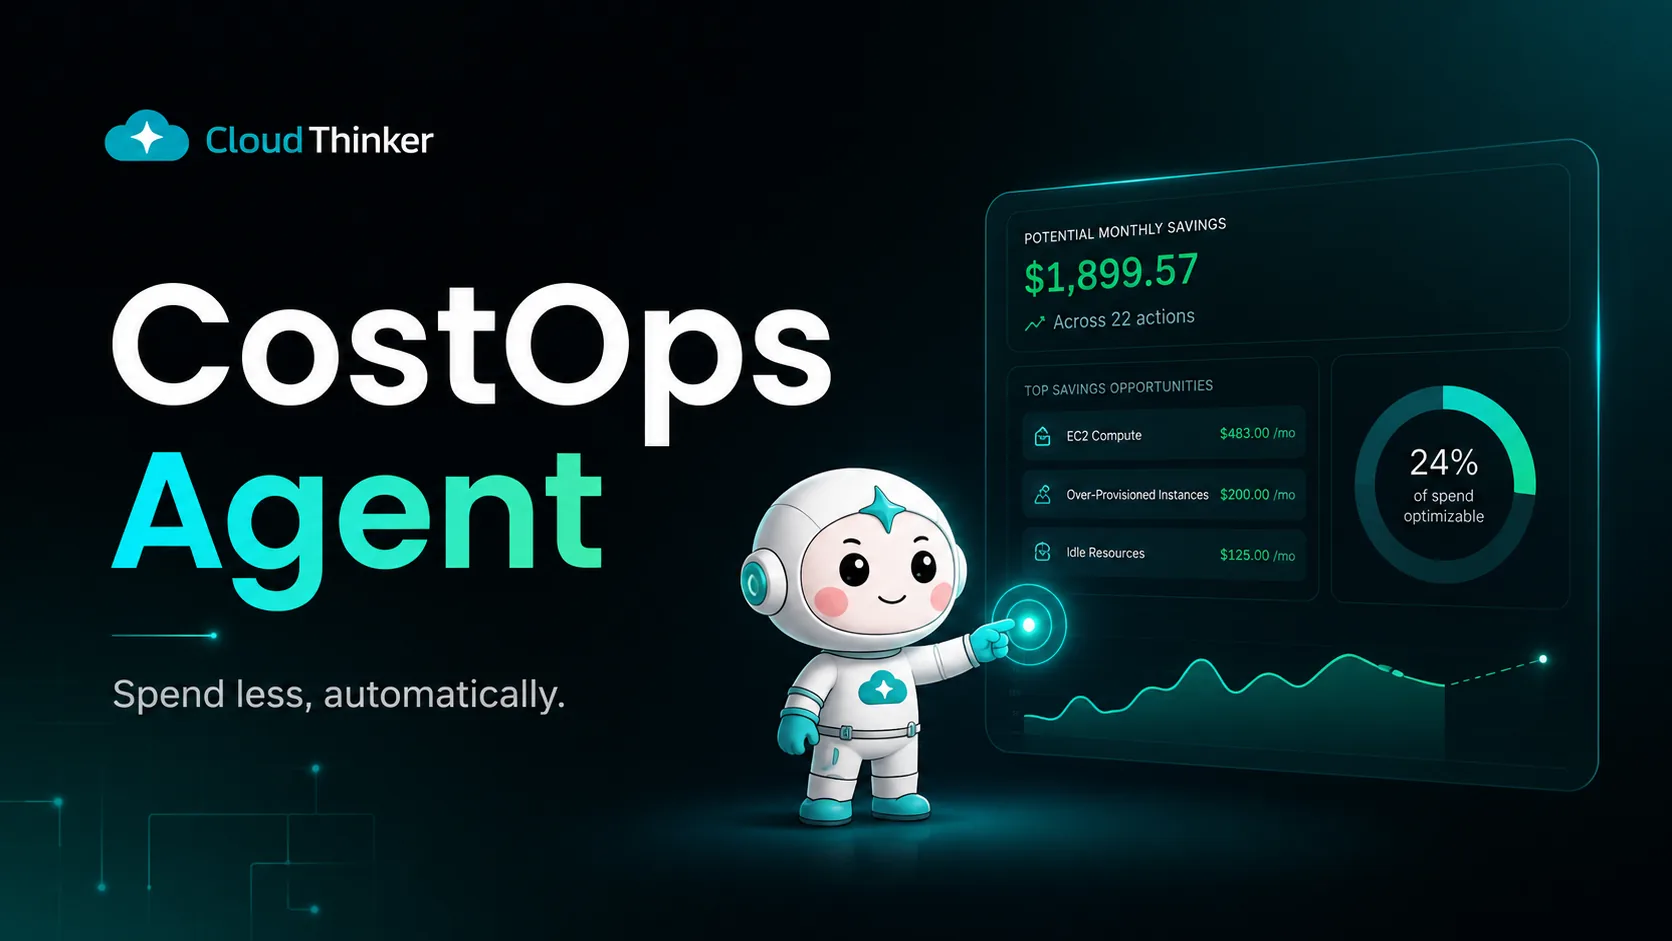
Introducing CloudThinker Optimize: From Cost Anomaly to Landed Fix, on a Daily Loop
CloudThinker Optimize runs a daily loop on AWS and GCP: it detects the anomaly the same day, isolates the cost driver, traces the commit that caused it, and opens the fix as a Merge Request behind Auto Mode. It reads from the cost tools you already run instead of replacing them.
Product
Introducing Resolve
Resolve joins signal intelligence and AI investigation with a Memory layer, so 13K raw events become 40 actionable clusters and investigation starts on its own. This post walks one 3 a.m. cluster from suppression to a confirmed root cause, with every remediation gated by Auto Mode.
Product
Your Zabbix Sees the Problem. Who Closes It?
Zabbix is great at noticing. Closing the problem is still a person clicking through the frontend. Why flapping triggers, stale dependency maps and fixed actions keep the queue growing, and how CloudThinker reads Zabbix over its API to triage, correlate with recent changes, act with approval and verify each problem stays closed.
Product
CloudThinker × Terraform: Day-2 Operations for the Full IaC Lifecycle
Terraform plans only run when someone opens an MR, so drift from autoscalers and console hot-patches builds up unseen. This post walks a real drift run (Aurora ACU ceiling, EFS throughput and archive, EKS desired_size), shows how CloudThinker reads state, live API and telemetry before deciding who owns each field, and ends with one reviewed reconciliation MR.
Product
Resolve over AWS PrivateLink: Monitoring Your Infrastructure Without a Public Endpoint
How CloudThinker Resolve reaches EKS, Prometheus, Redis, Postgres and Kafka inside a customer VPC over AWS PrivateLink, with no public endpoint. Covers AllowedPrincipals, read-only RBAC, one shared NLB, the AWS CLI setup and how to revoke access on your own.
Product
Meet Your Custom Agent
Generic AI doesn't know your stack, your playbook or your team. A Custom Agent does: name it, teach it, plug in only the tools you allow, and your whole team @mentions the same AI teammate in Slack, with every write going through Auto Mode.
Product
CloudThinker × Rollbar: Day-2 Operations for the Full Error Lifecycle
Rollbar captures errors well. The hours after capture are where programs stall: regressions buried under third-party noise, deploy context in another tab, and Items nobody comes back to resolve. This post walks one Item from deploy correlation to N+1 root cause, sandbox repro, draft MR and a verified resolve, with every write gated by Auto Mode.
Market Insights
AgenticOps Needs Its Own Platform: Why a Coding Tool Can't Safely Connect to Production
Coding tools are built to turn intent into a diff, not to hold production credentials for a team. Using 2025 to 2026 incident data, this post maps six failure modes of laptop-credential access and walks one production change end to end through scoped credentials, a sandbox, Auto Mode and an audit log.
Market Insights
Data Sovereignty for Agentic AI in Vietnam and ASEAN BFSI: A Field Guide
For banks and insurers in Vietnam and ASEAN, residency covers only one of the five surfaces an AI agent touches: storage, inference, memory, telemetry and egress. This field guide follows one customer question through the agent loop, maps the regulatory floor, and sets out five architecture patterns and a ten-question checklist that hold up at audit.
Market Insights
Build vs Buy: The 24-Month TCO of an Agentic Operations Platform
A weekend prototype is not a platform: the gap is thirteen runtime primitives nobody demos. This post compares the 24-month TCO of building an agentic operations platform against buying CloudThinker, names the four cases where building is right, and lays out the hybrid path of buying the platform, building Skills and running BYOC.
Product
New CloudThinker Security Agent runs continuous agentic penetration testing from commit to deployment
SAST, legacy DAST and twice-a-year pentests each miss AI-speed code for a structural reason. The CloudThinker Security Agent pentests every merge: it maps the authenticated surface, chains findings, proves each one with a read-only exploit, and routes the patch to the developer who wrote the code, in about 15 minutes.
How To
Eager Tool Calling: How We Cut Agent Latency by 50% on Long Tool Chains
Parallel tool calling overlaps tools with each other but still waits for the model to finish streaming. Eager tool calling fires each tool the moment its block is sealed, overlapping execution with generation: about 50% faster median task completion in production, with a reproducible open-source benchmark.
Product
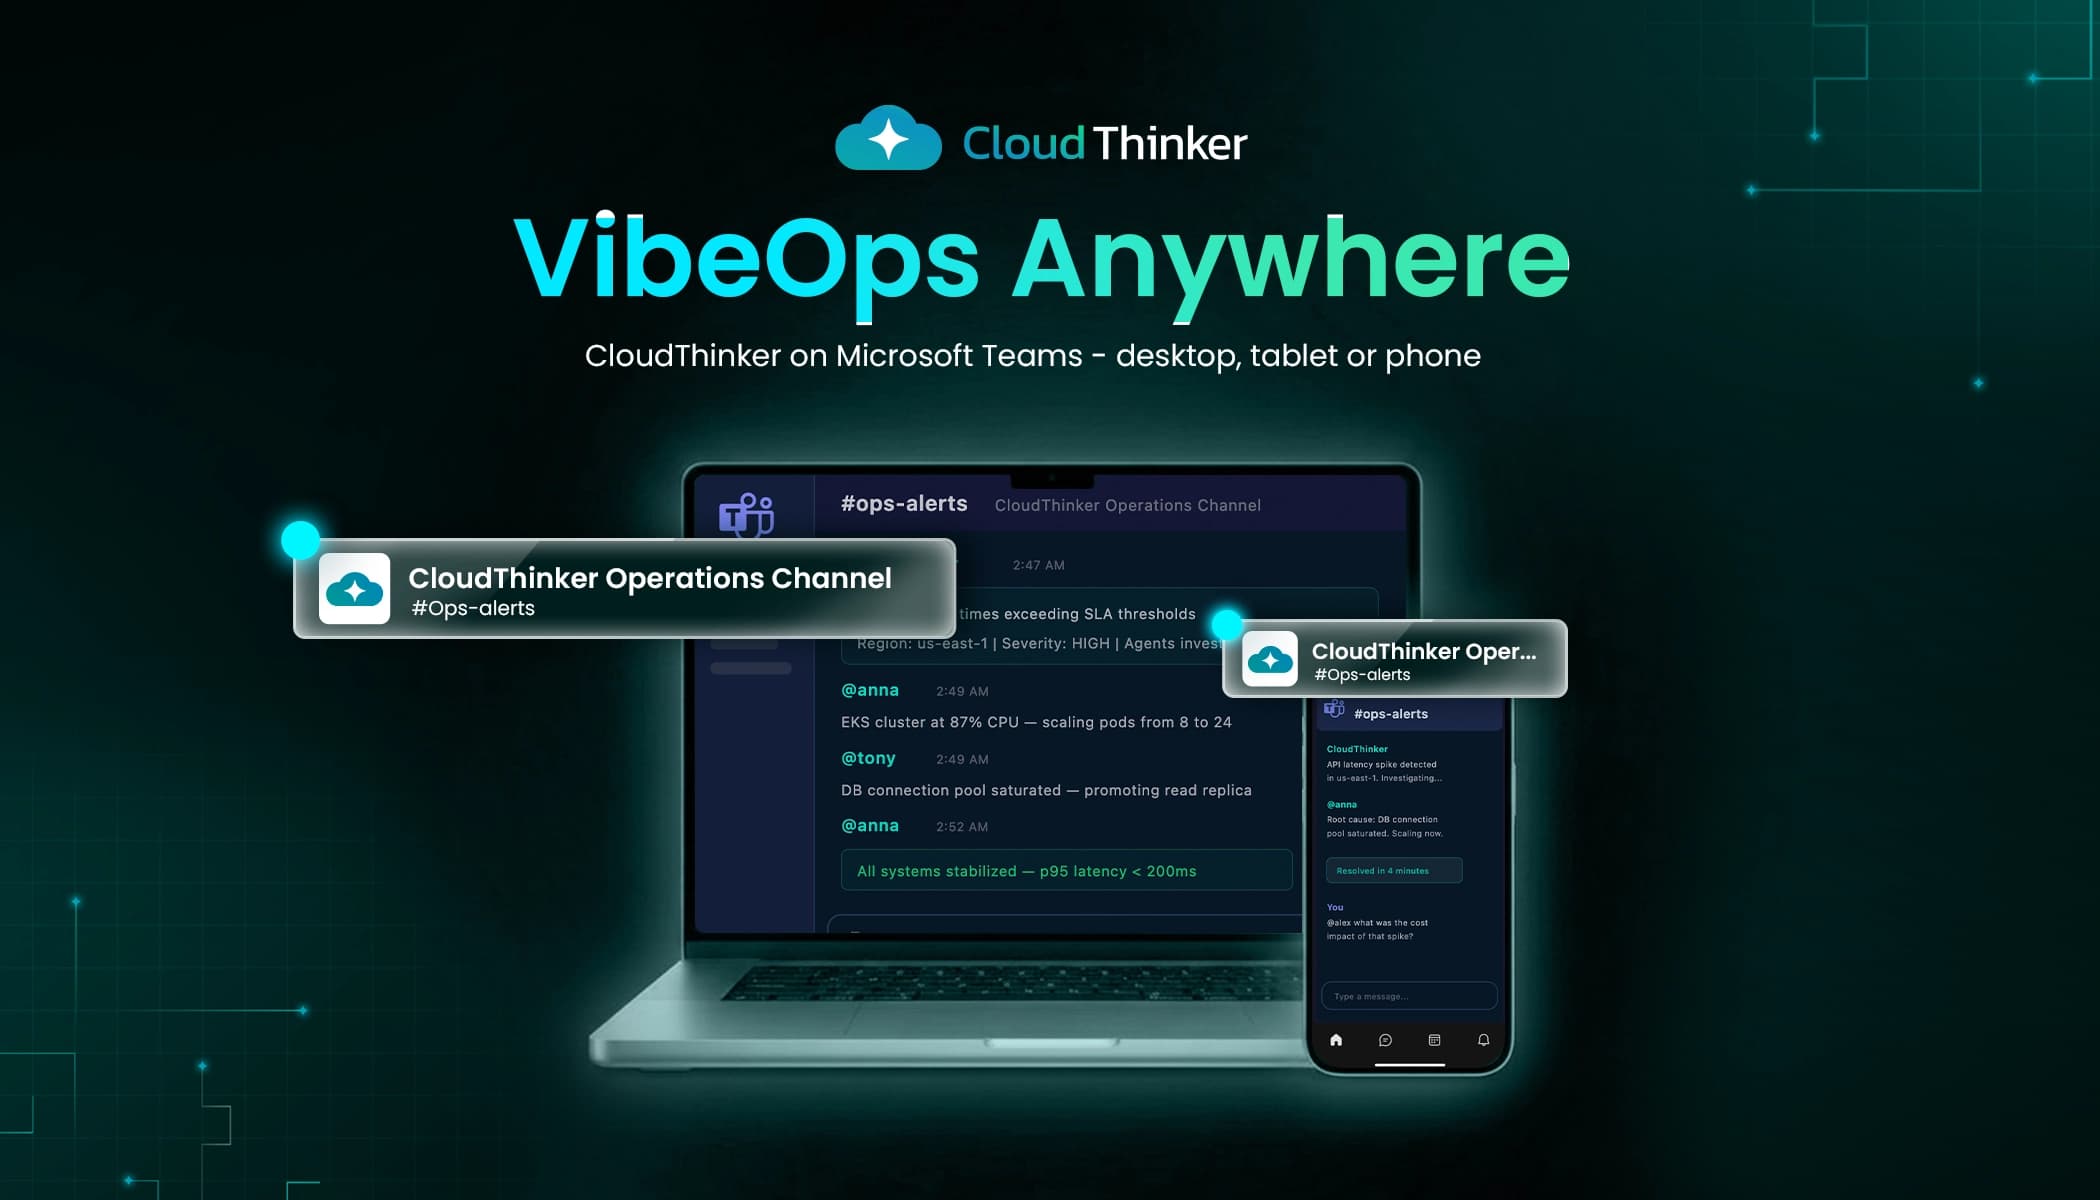
VibeOps Anywhere: CloudThinker Now on Microsoft Teams
Most Teams channels carry the alert while the investigation happens somewhere else. CloudThinker on Microsoft Teams investigates in the thread, routes notifications per channel, and waits for approval from your phone before it changes anything.
Product
Introducing CloudThinker Review for Azure DevOps
Branch policies count approvals and green builds, but they can't read code. CloudThinker Review, ranked #1 on independent benchmarks, now reviews Azure DevOps pull requests: a scoped PAT, one service hook per trigger, and ranked findings posted as PR threads.
Product
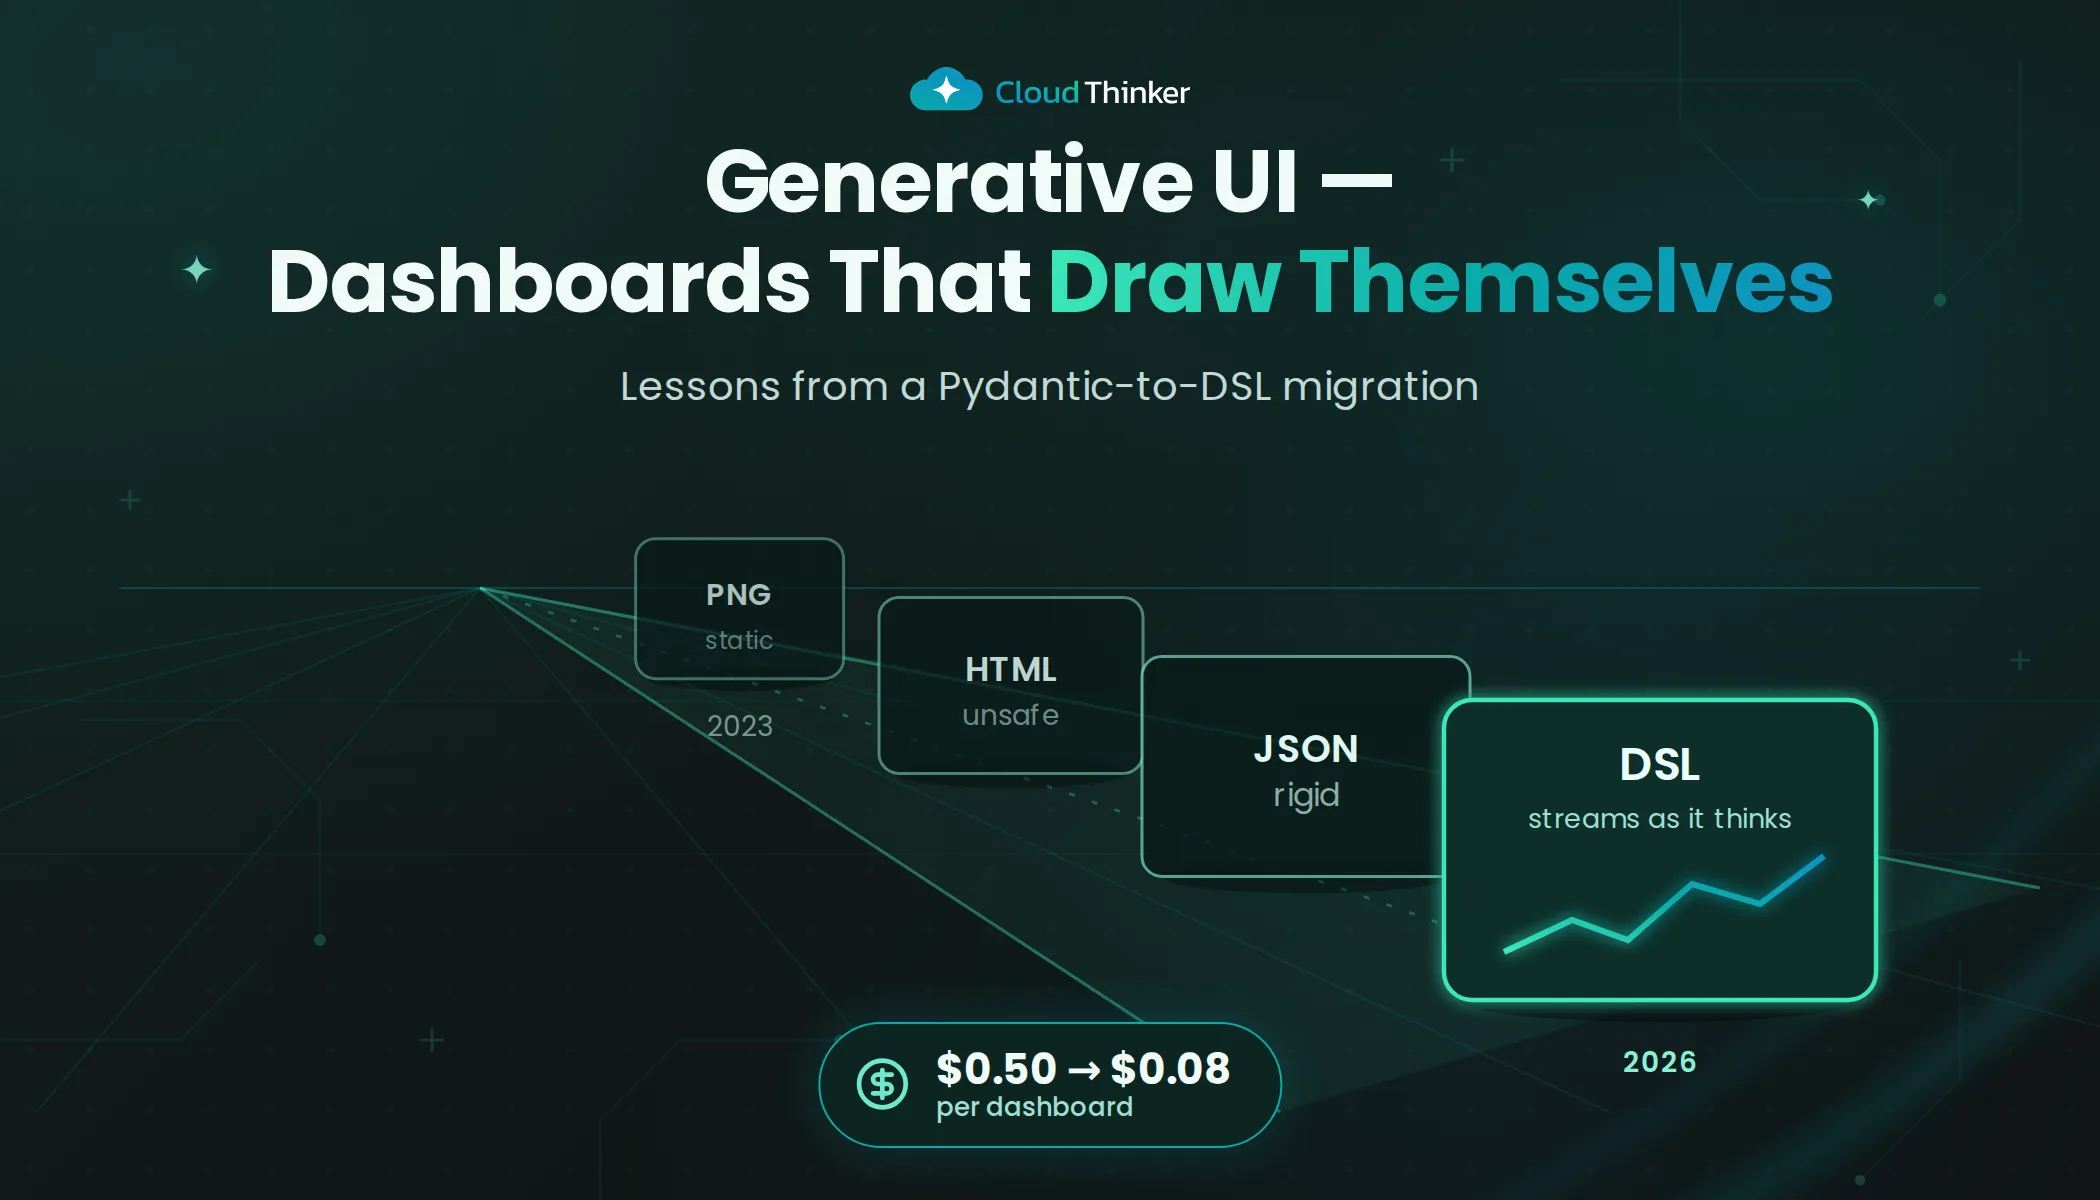
Generative UI in Production: Lessons from a Pydantic-to-DSL Migration
How CloudThinker's agent dashboards went from 30-40 seconds and ~$0.50 per report to under 10 seconds and ~$0.08: why matplotlib and raw HTML were dead ends, why constrained-decoding JSON couldn't stream, and how a line-oriented DSL fixed both.
How To
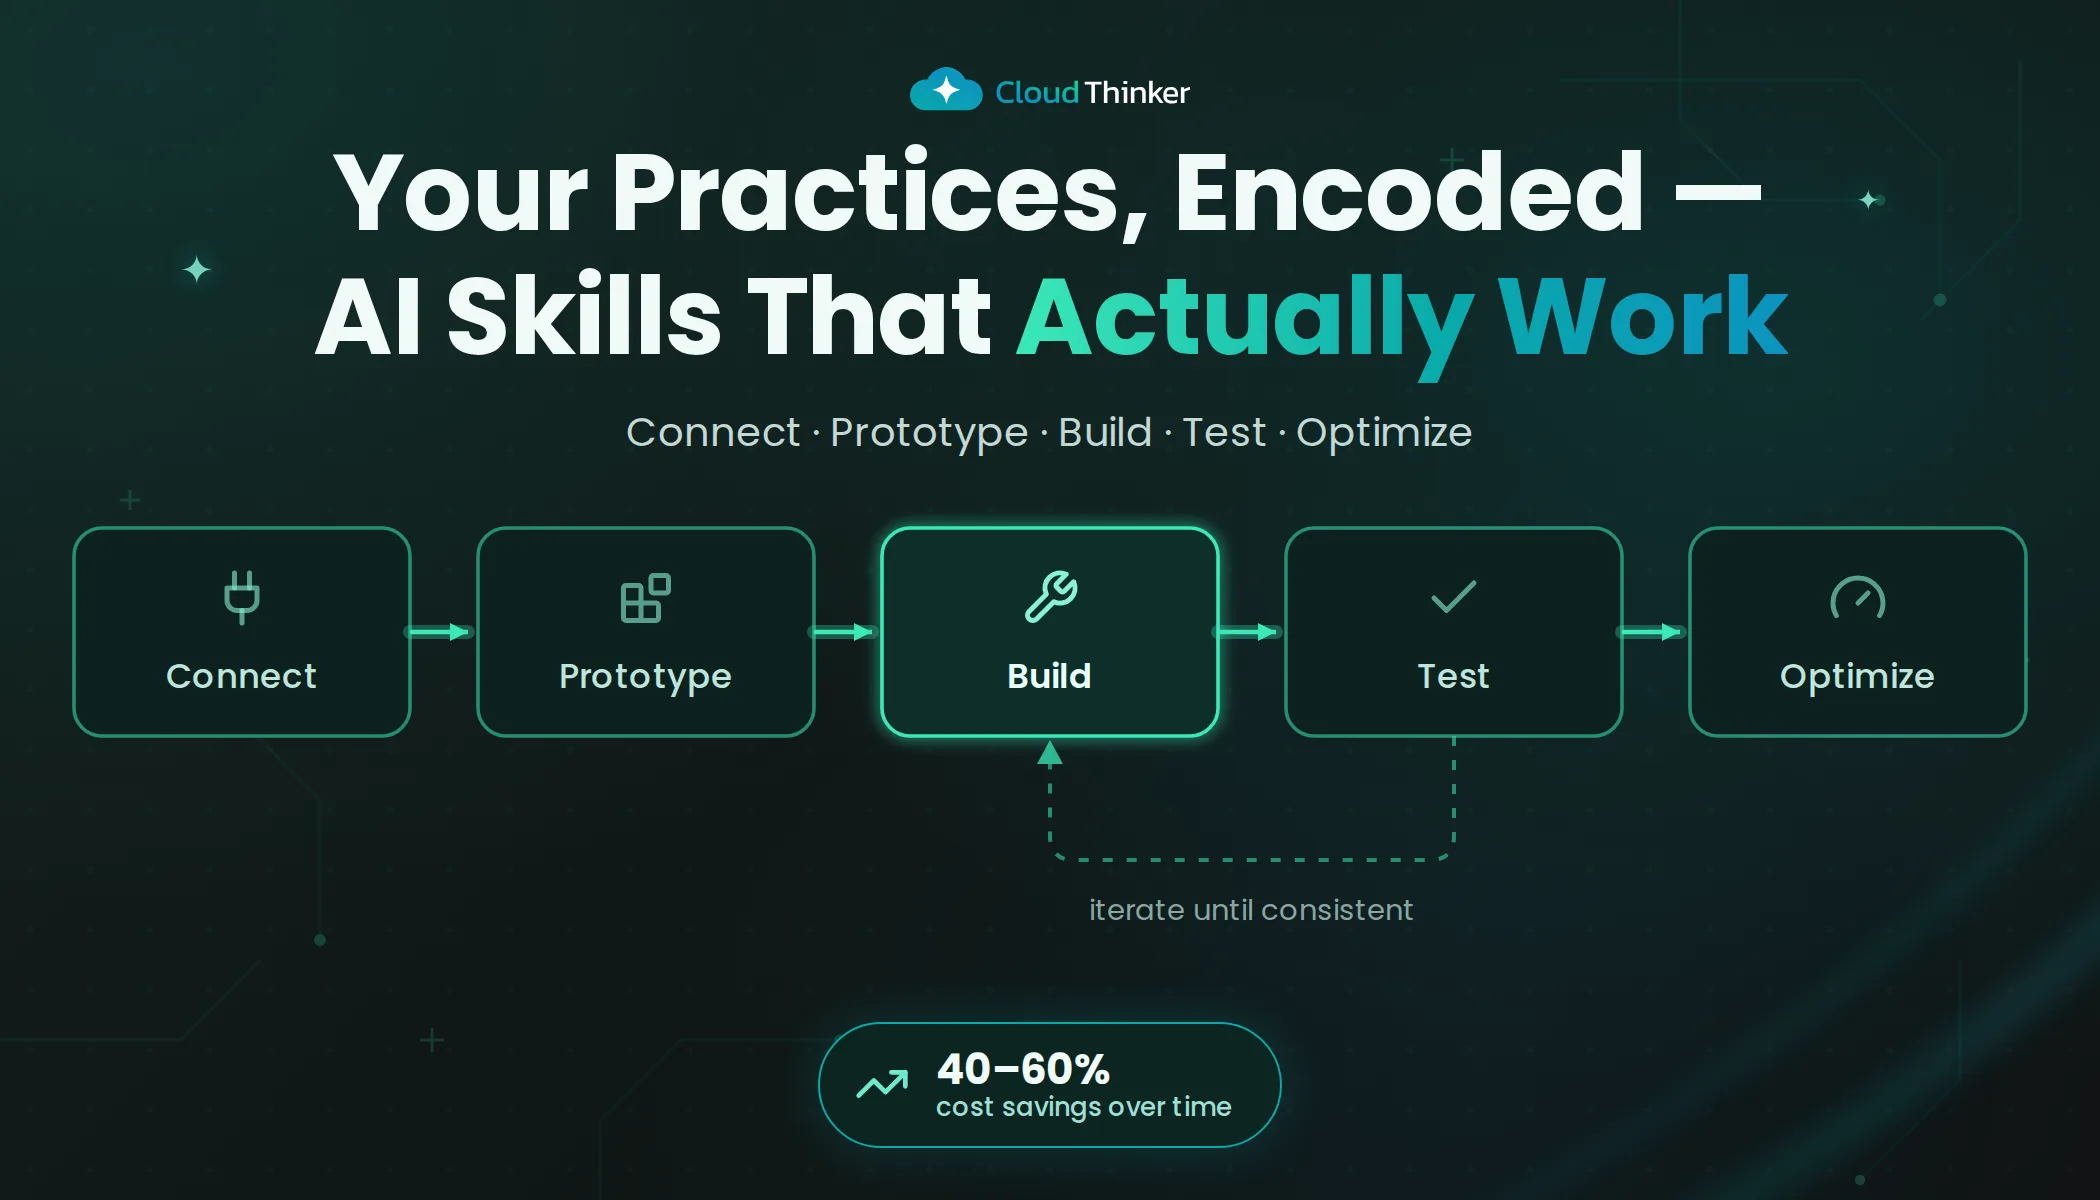
Best Practices: How to Build AI Skills That Actually Work for Your Business
Cloned public skills break on your tools, your credential scopes and your missing context. This guide shows the build loop that works (connect, run it once in chat, tune, extract, replay), walks a Monday AWS cost review skill end to end, and covers Auto Mode and building on Ultra while running on Light.
How To
Choose the Right Model, Optimize Your AI Costs
Running every task on one model tier either burns credits or fails the hard analyses. This post explains CloudThinker's Light, Pro and Ultra tiers, the break-even math behind building a skill with Ultra and running it on Light, and a 1,000-task routing example that saves 28 to 42% against all-Pro.
Product
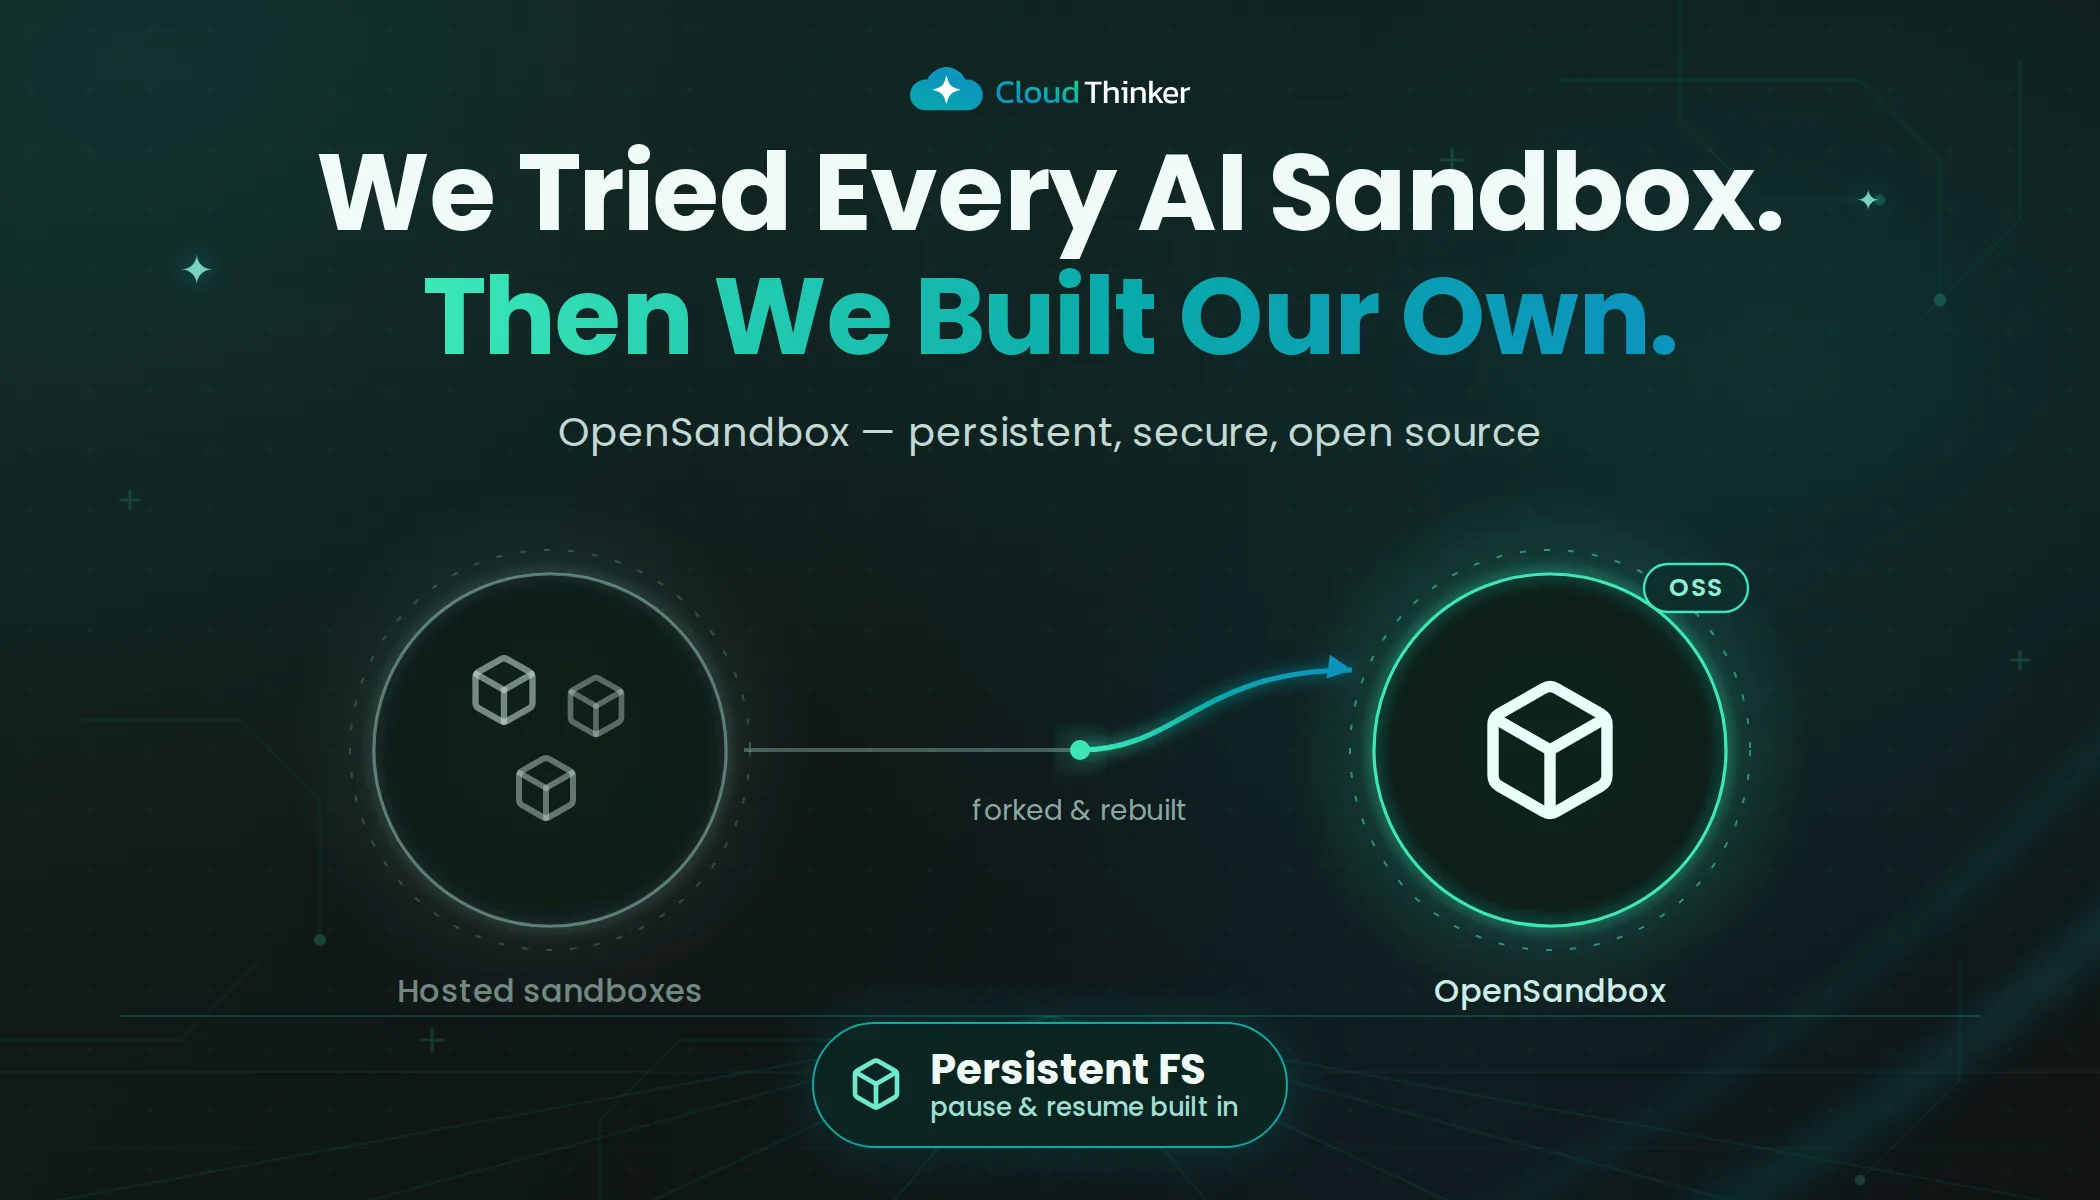
We Tried Every AI Sandbox. Then We Built Our Own.
Hosted sandboxes couldn't reach our private APIs, self-hosted VMs couldn't pause, and the best open-source option lacked a production layer. We built persistence, tiered pause/resume, network filtering and hardening on Alibaba's OpenSandbox, and open-sourced it as OpenSandbox on EKS.
Product
CloudThinker's SuperPower Security Agent for Cloud
Scanners like Checkov, Prowler and Trivy each see one layer and hand a list to a human. CloudThinker's security agent runs 20 security skills together, joins their findings through a knowledge graph, and works a GuardDuty credential-exfiltration finding from CloudTrail forensics to approved containment.
Product
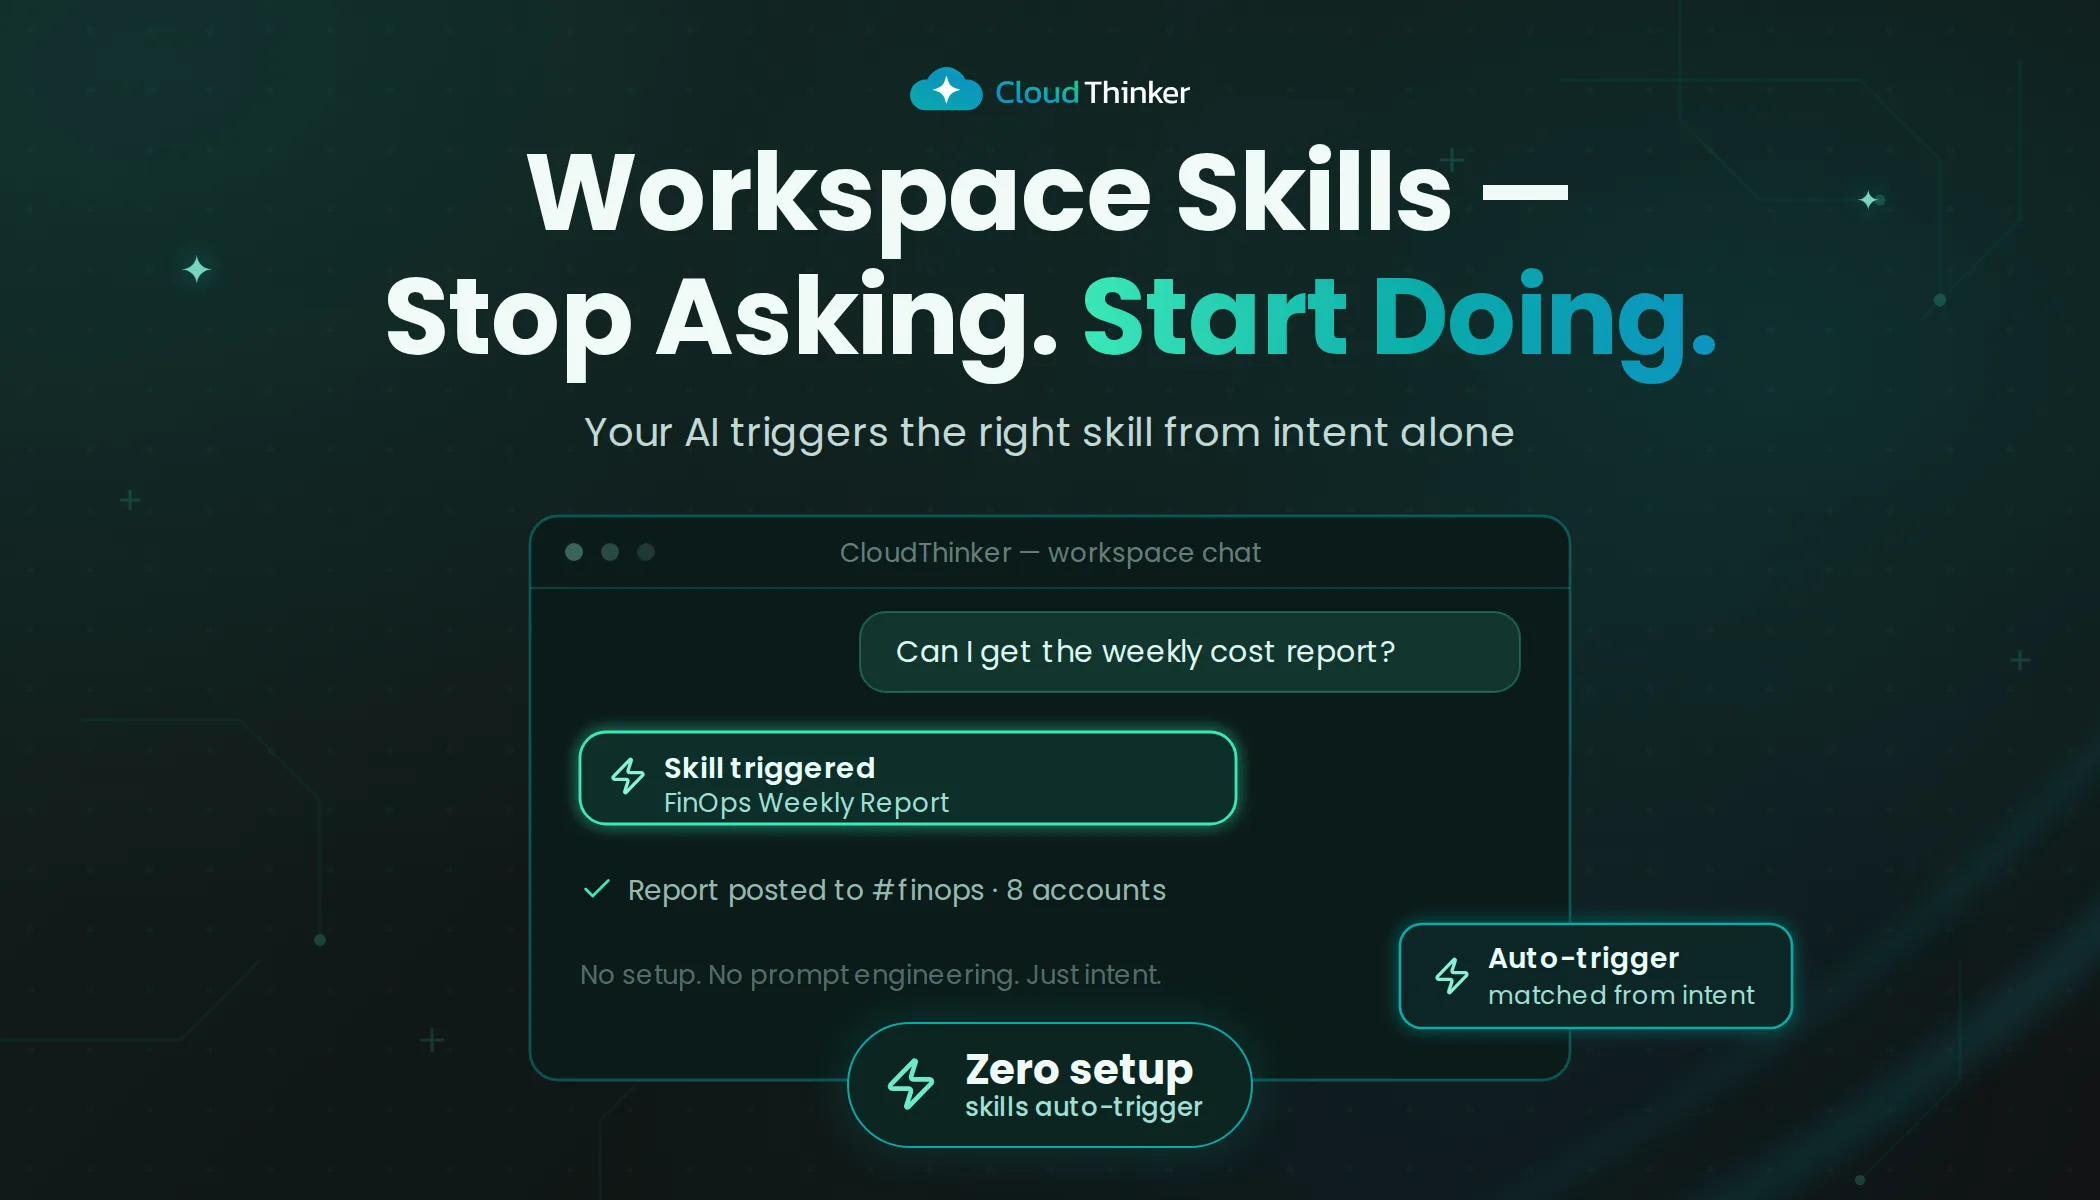
Mastering Workspace Skills: The Key to a Truly Autonomous AI Operator
Prompt libraries and wikis rely on someone remembering them. Workspace Skills encode the procedure once and the AI matches it from the description on every message. This post covers how matching works, both ways to build a skill, a full worked example, and three rules for skills that actually get used.
Product
Agent Memory Meets Graph: Introducing MemGraph, Long-Term Memory for AI Cloud Agents
A flat vector store can't tell which memories are related, outdated or proven. MemGraph stores operational knowledge as a typed graph, curates every new memory through an extract, search, evolve and connect pipeline, and ranks results with hybrid search plus reinforcement. This deep dive covers all five memory types, seven edge types and the four storage backends.
Product
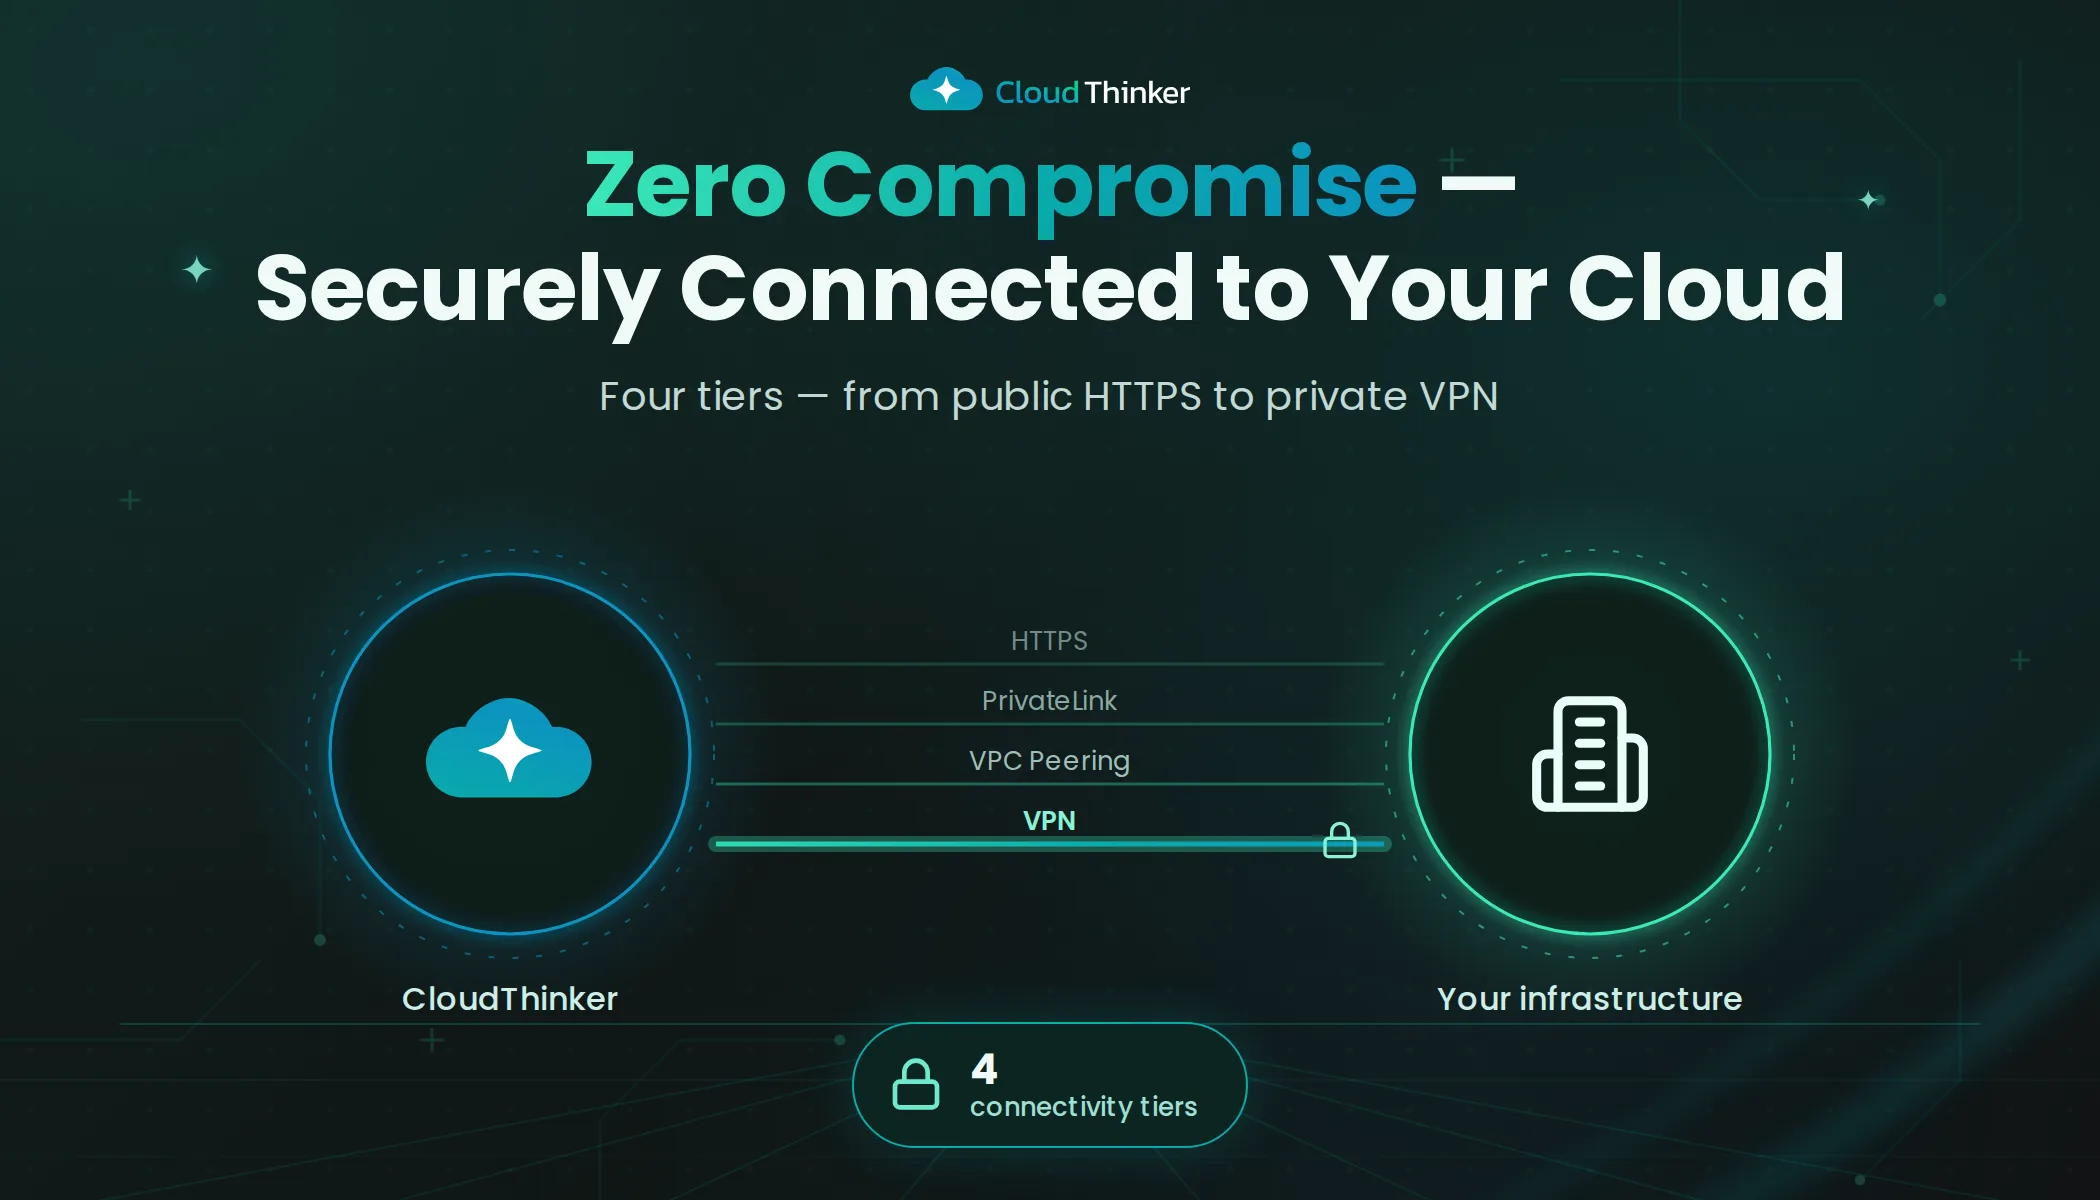
CloudThinker Connections: How We Securely Connect to Your Infrastructure
Your databases live in private subnets and your clusters sit behind firewalls. CloudThinker Connections reaches them on your terms: four network tiers from public HTTPS to PrivateLink and site-to-site VPN, read-only scoped credentials injected per operation, and an immutable audit trail.
Product
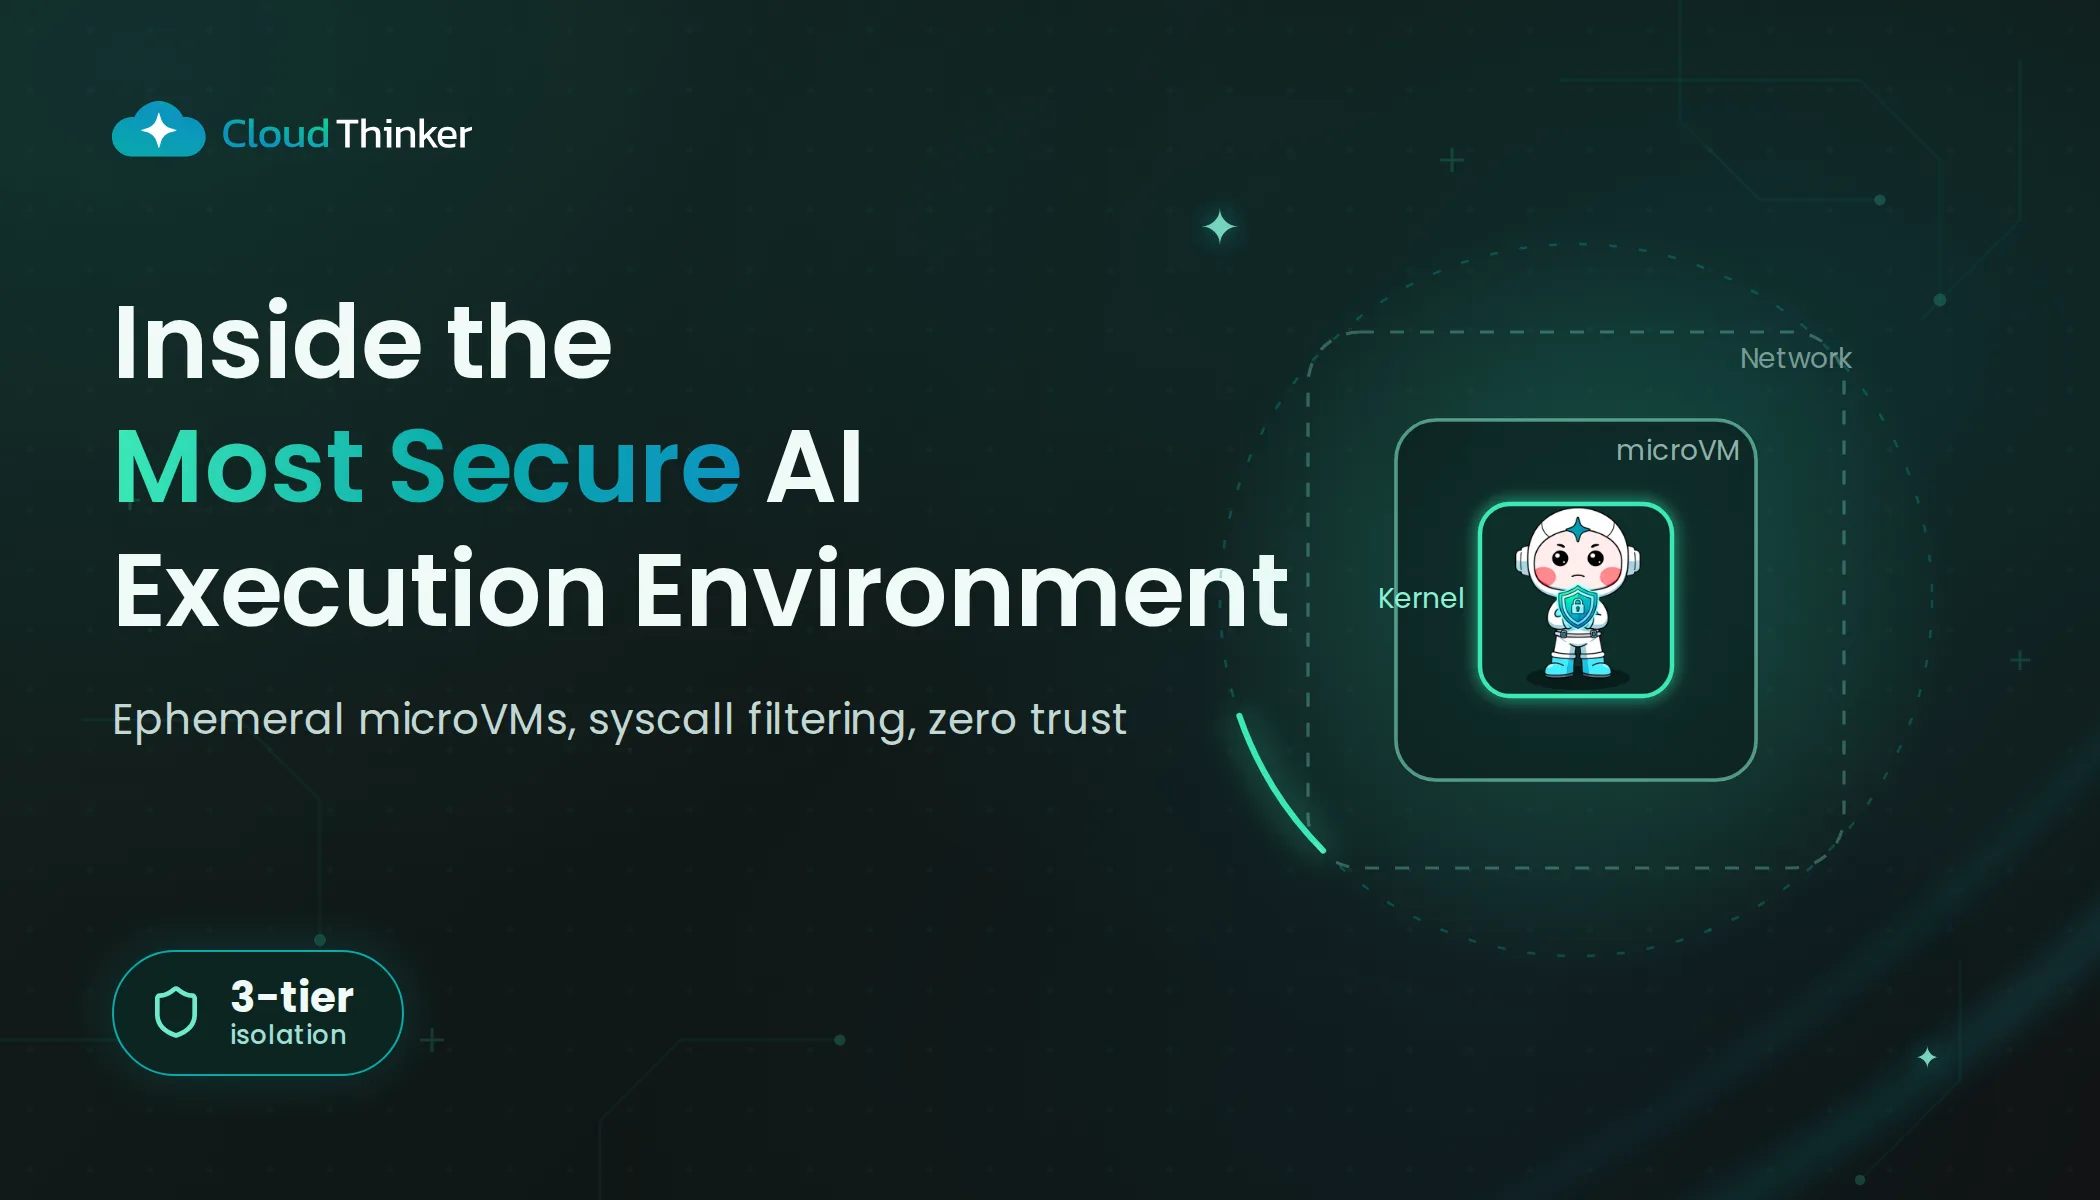
Inside CloudThinker's Sandbox: How We Built a Secure Execution Environment for AI Agents
How CloudThinker's sandbox keeps agent execution safe: three-tier isolation, an isolated sandbox per agent, allowlist syscall filtering, short-lived scoped credentials, independent Guard-In and Guard-Out, and optional PrivateLink or VPN connectivity.
Product
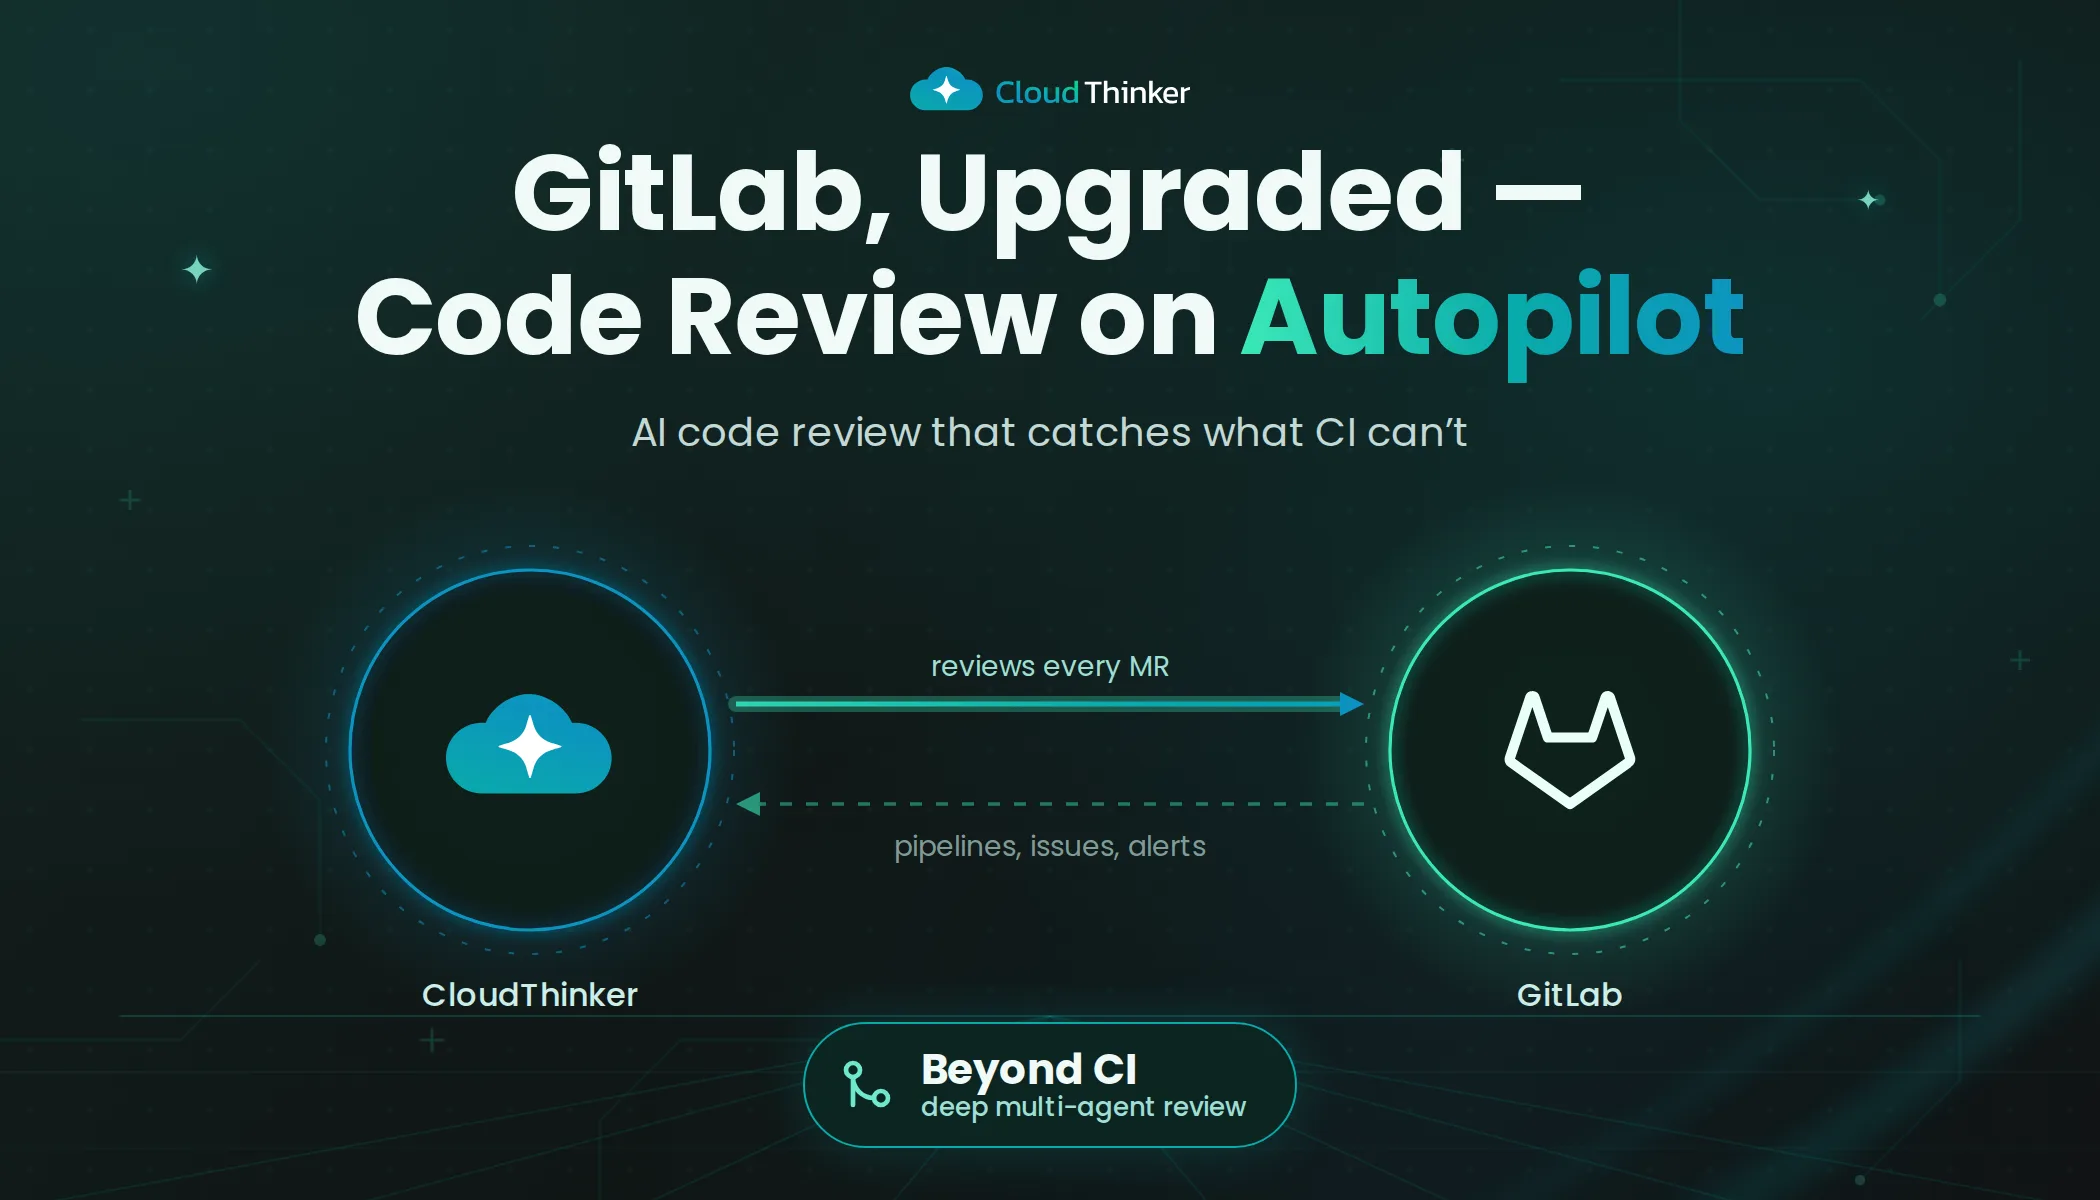
CloudThinker Makes GitLab Become Autonomous
GitLab runs pipelines and waits for humans. CloudThinker adds context-aware merge request review, pipeline root cause analysis and a closed loop from incidents back to the MR that caused them, with every state change gated by Auto Mode.
Product
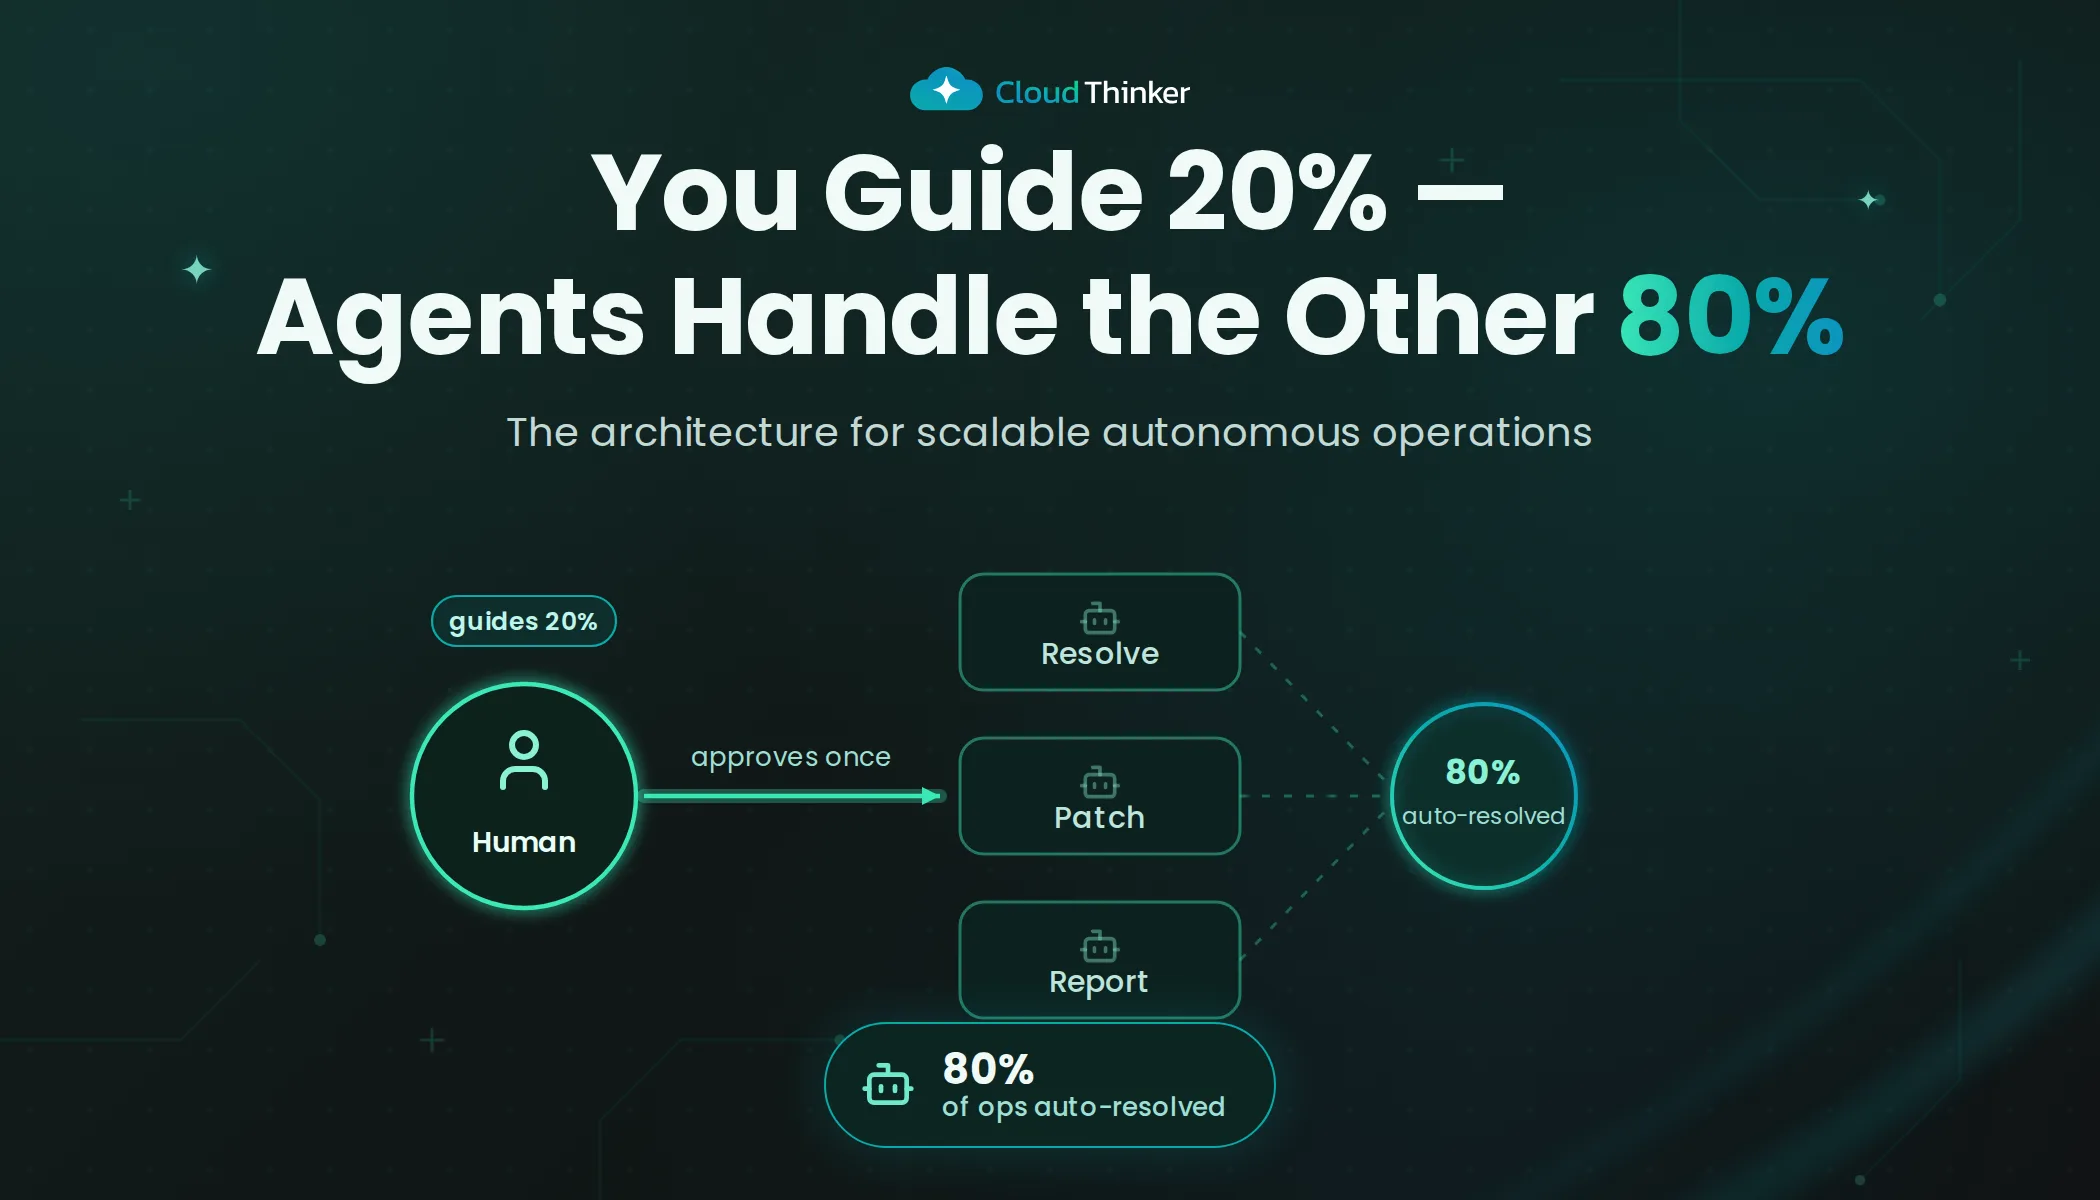
Human Expert Guidance Meets Agentic AI: The Architecture for Scalable Autonomous Operations
How to turn one senior engineer's fix into an organization-wide capability: skills developed in workspaces, tested in sandboxes, shared through governance, and run through Auto Mode, with the 80/20 split as the target.
Market Insights
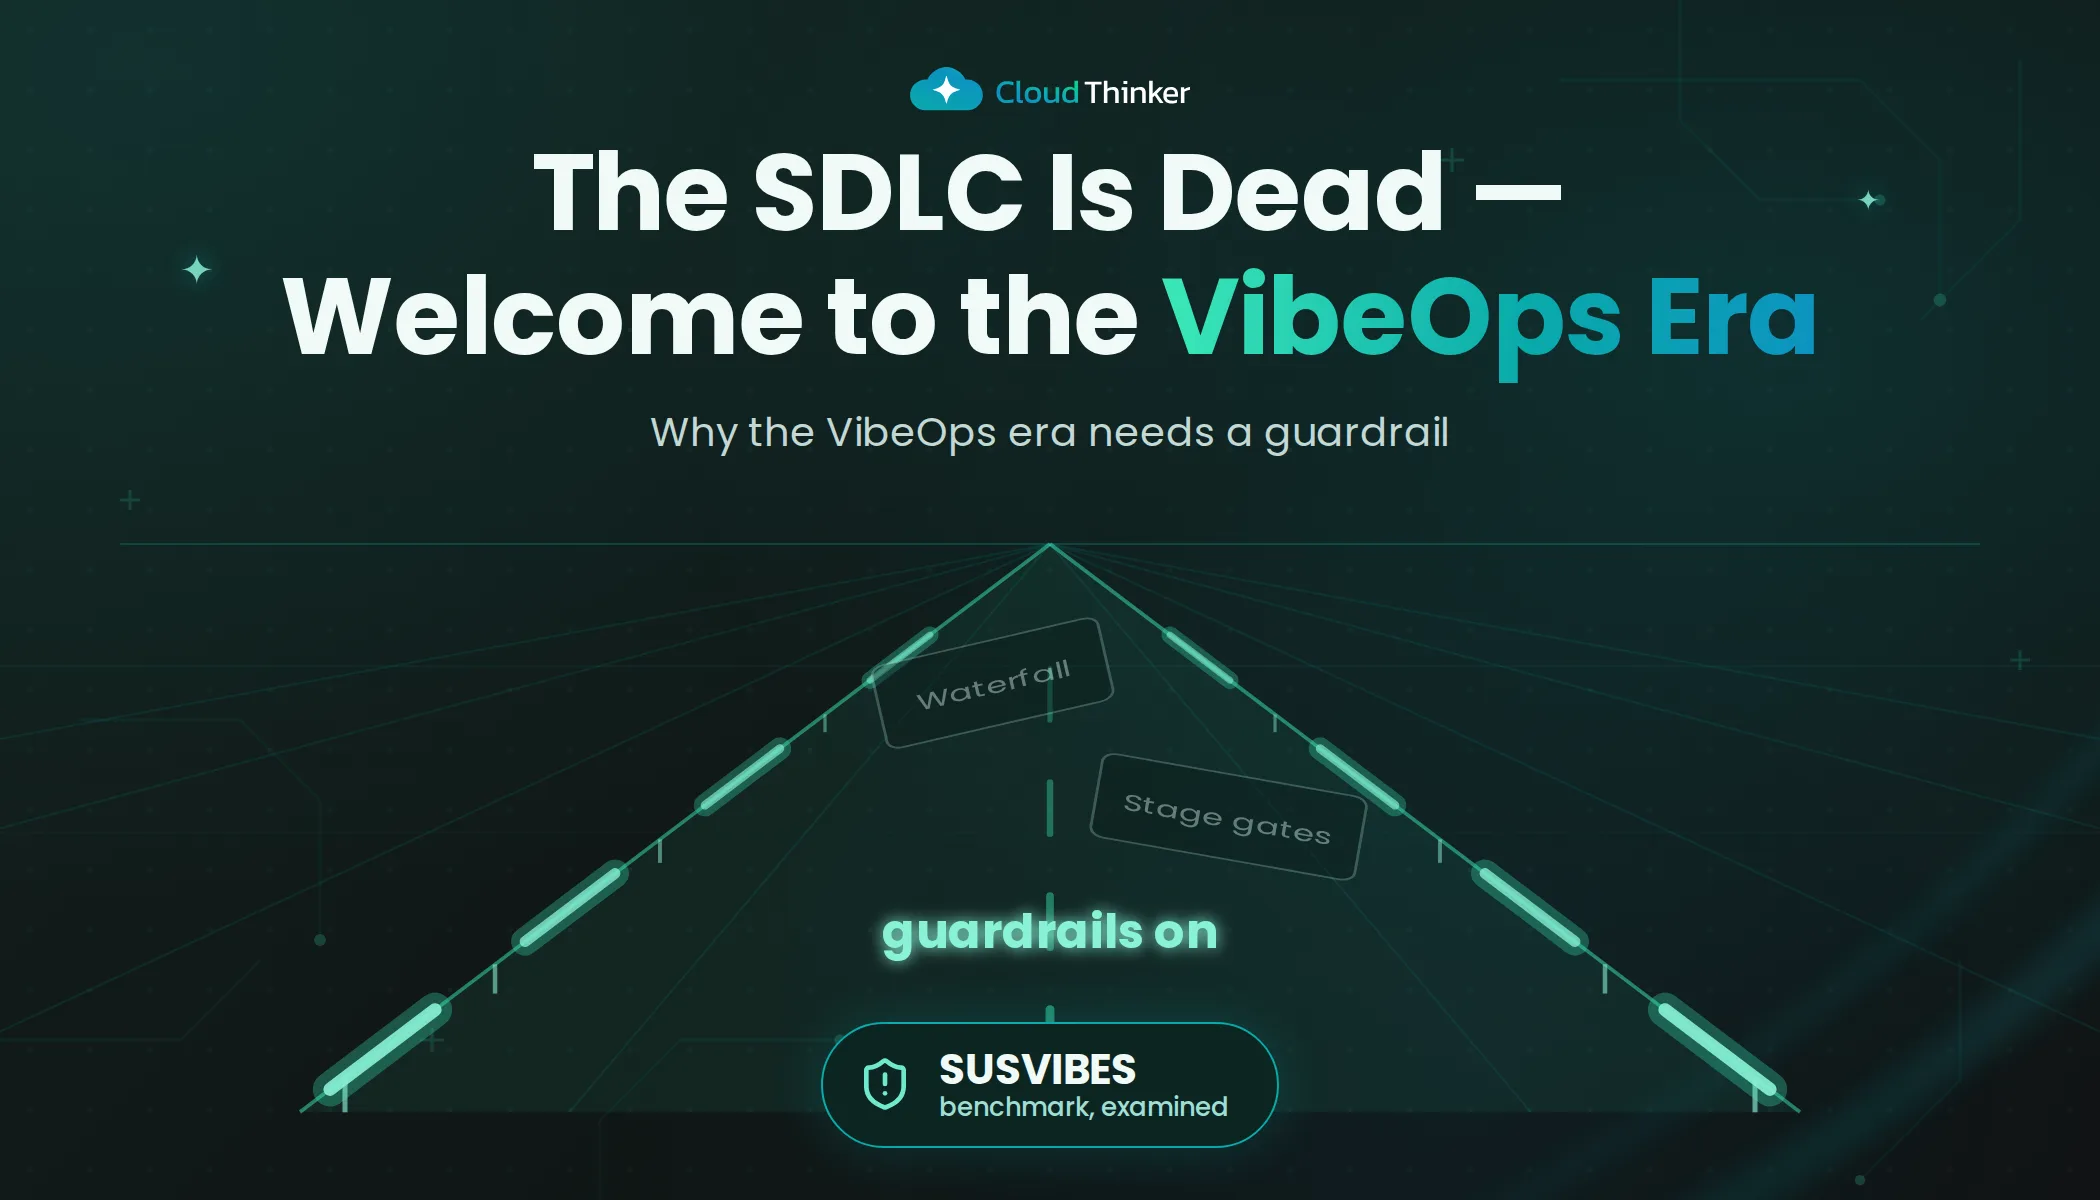
The Death of the Traditional SDLC: Why the VibeOps Era Needs a Guardrail
AI-generated code broke the human-paced assumptions behind the traditional SDLC, and the SUSVIBES data shows working code is rarely secure code. This post lays out the three crises of the VibeOps era and how CloudThinker's closed loop turns each production incident into a code review rule.
Market Insights
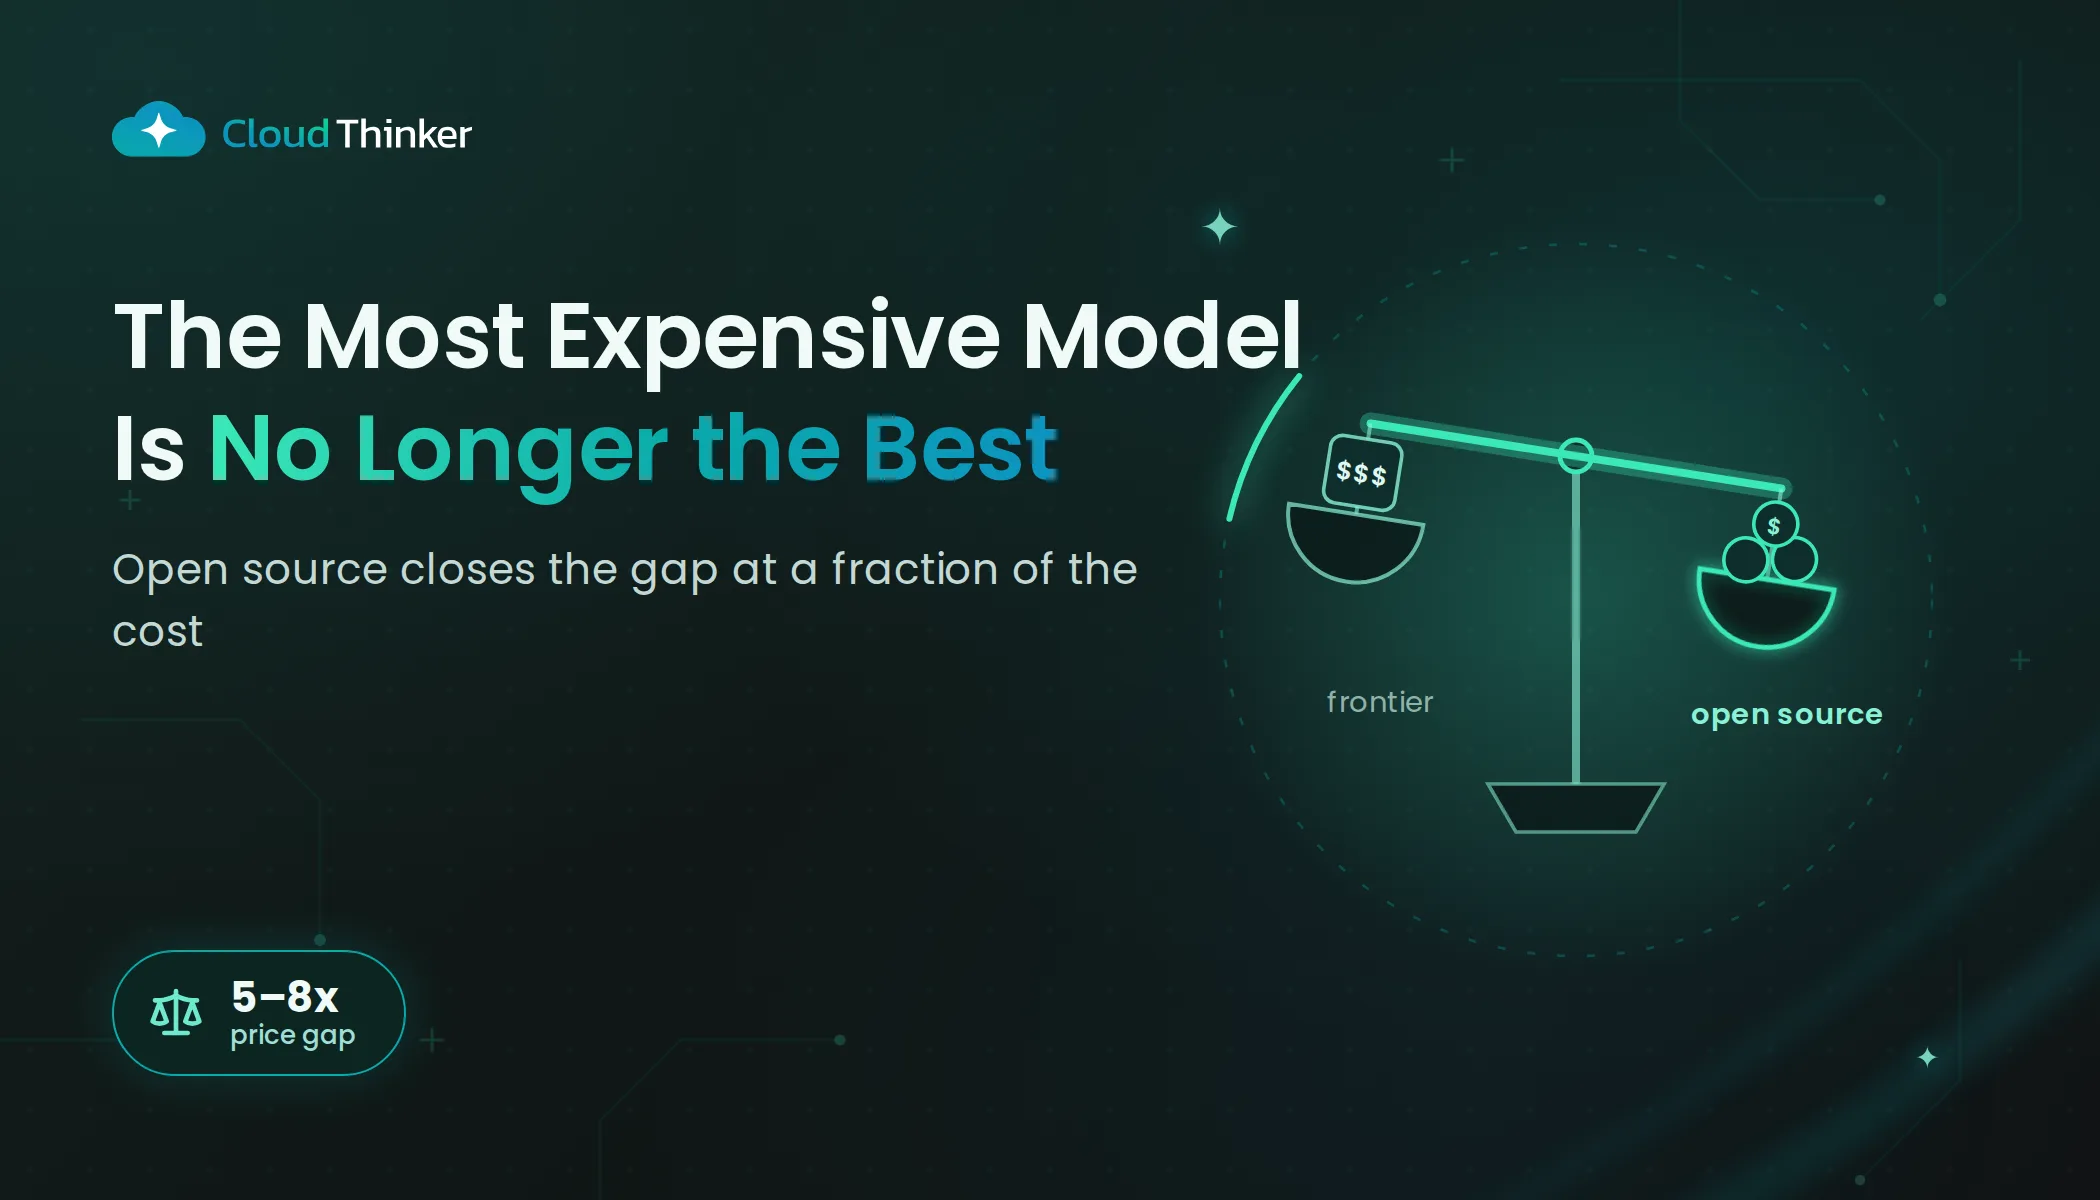
The Most Expensive Model Is No Longer the Best Choice
In February 2026, three frontier models landed within 1.6 points on SWE-bench at a 5x to 8x price gap. This post breaks down the five factors that now decide outcomes, prices AIOps, CLI and code workloads model by model, and shows why routing across tiers beats paying for the top model.
Event
CloudThinker and TechValley forge strategic alliance: Synergizing AI innovation with digital infrastructure
On February 9, 2026, TechValley and CloudThinker signed an MOU that pairs TechValley's infrastructure relationships in Vietnam and Korea with CloudThinker's AI-driven FinOps and AIOps. The agreement covers six areas, from exclusive distribution to large-enterprise adoption.
Product
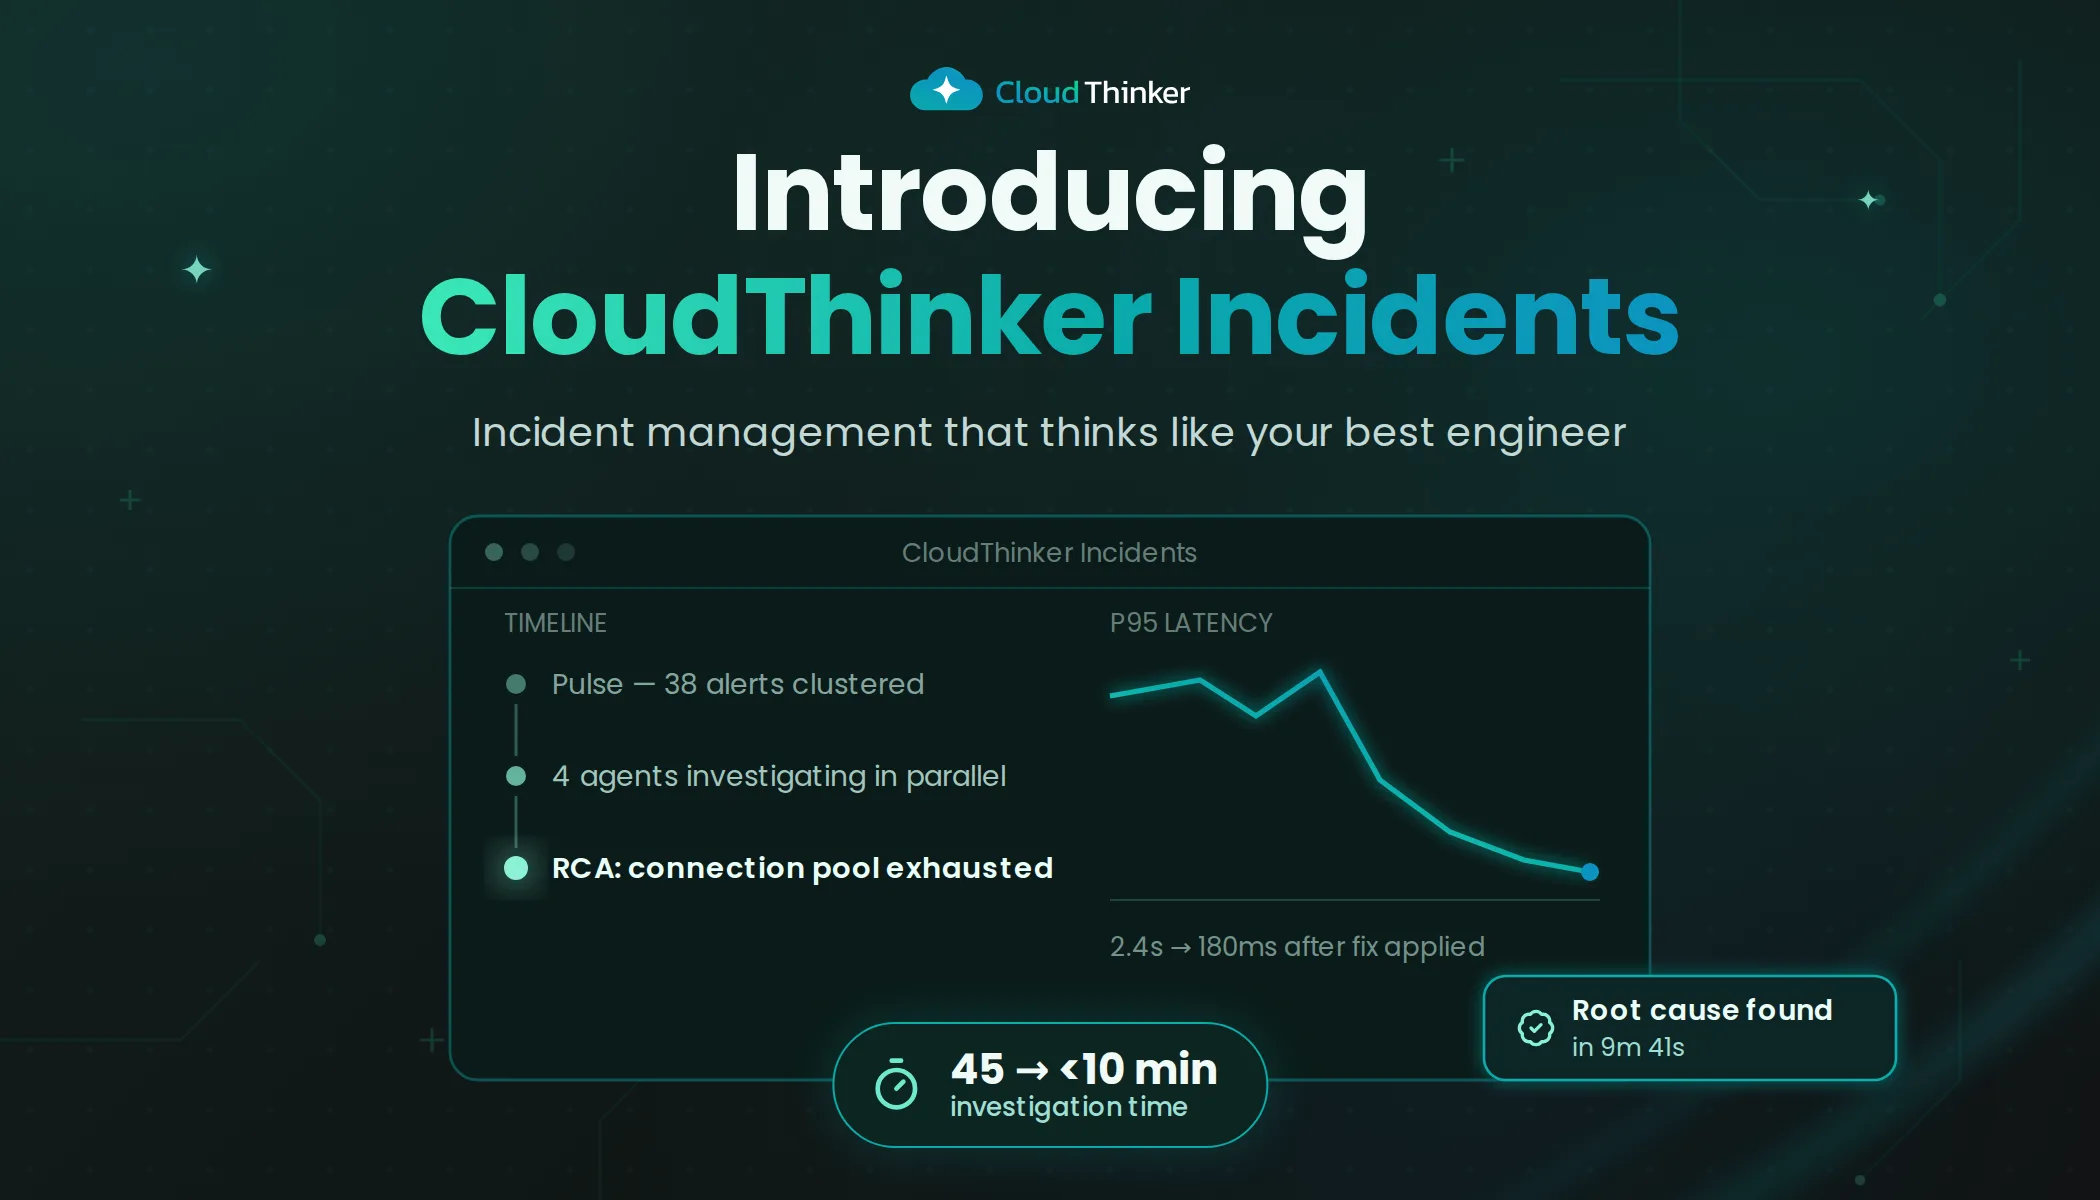
Introducing CloudThinker Incidents
CloudThinker Incidents investigates alerts the way a senior on-call would: it gathers evidence, tests hypotheses, scores its confidence and maps the blast radius across your topology. You validate the conclusion and decide the fix.
Product
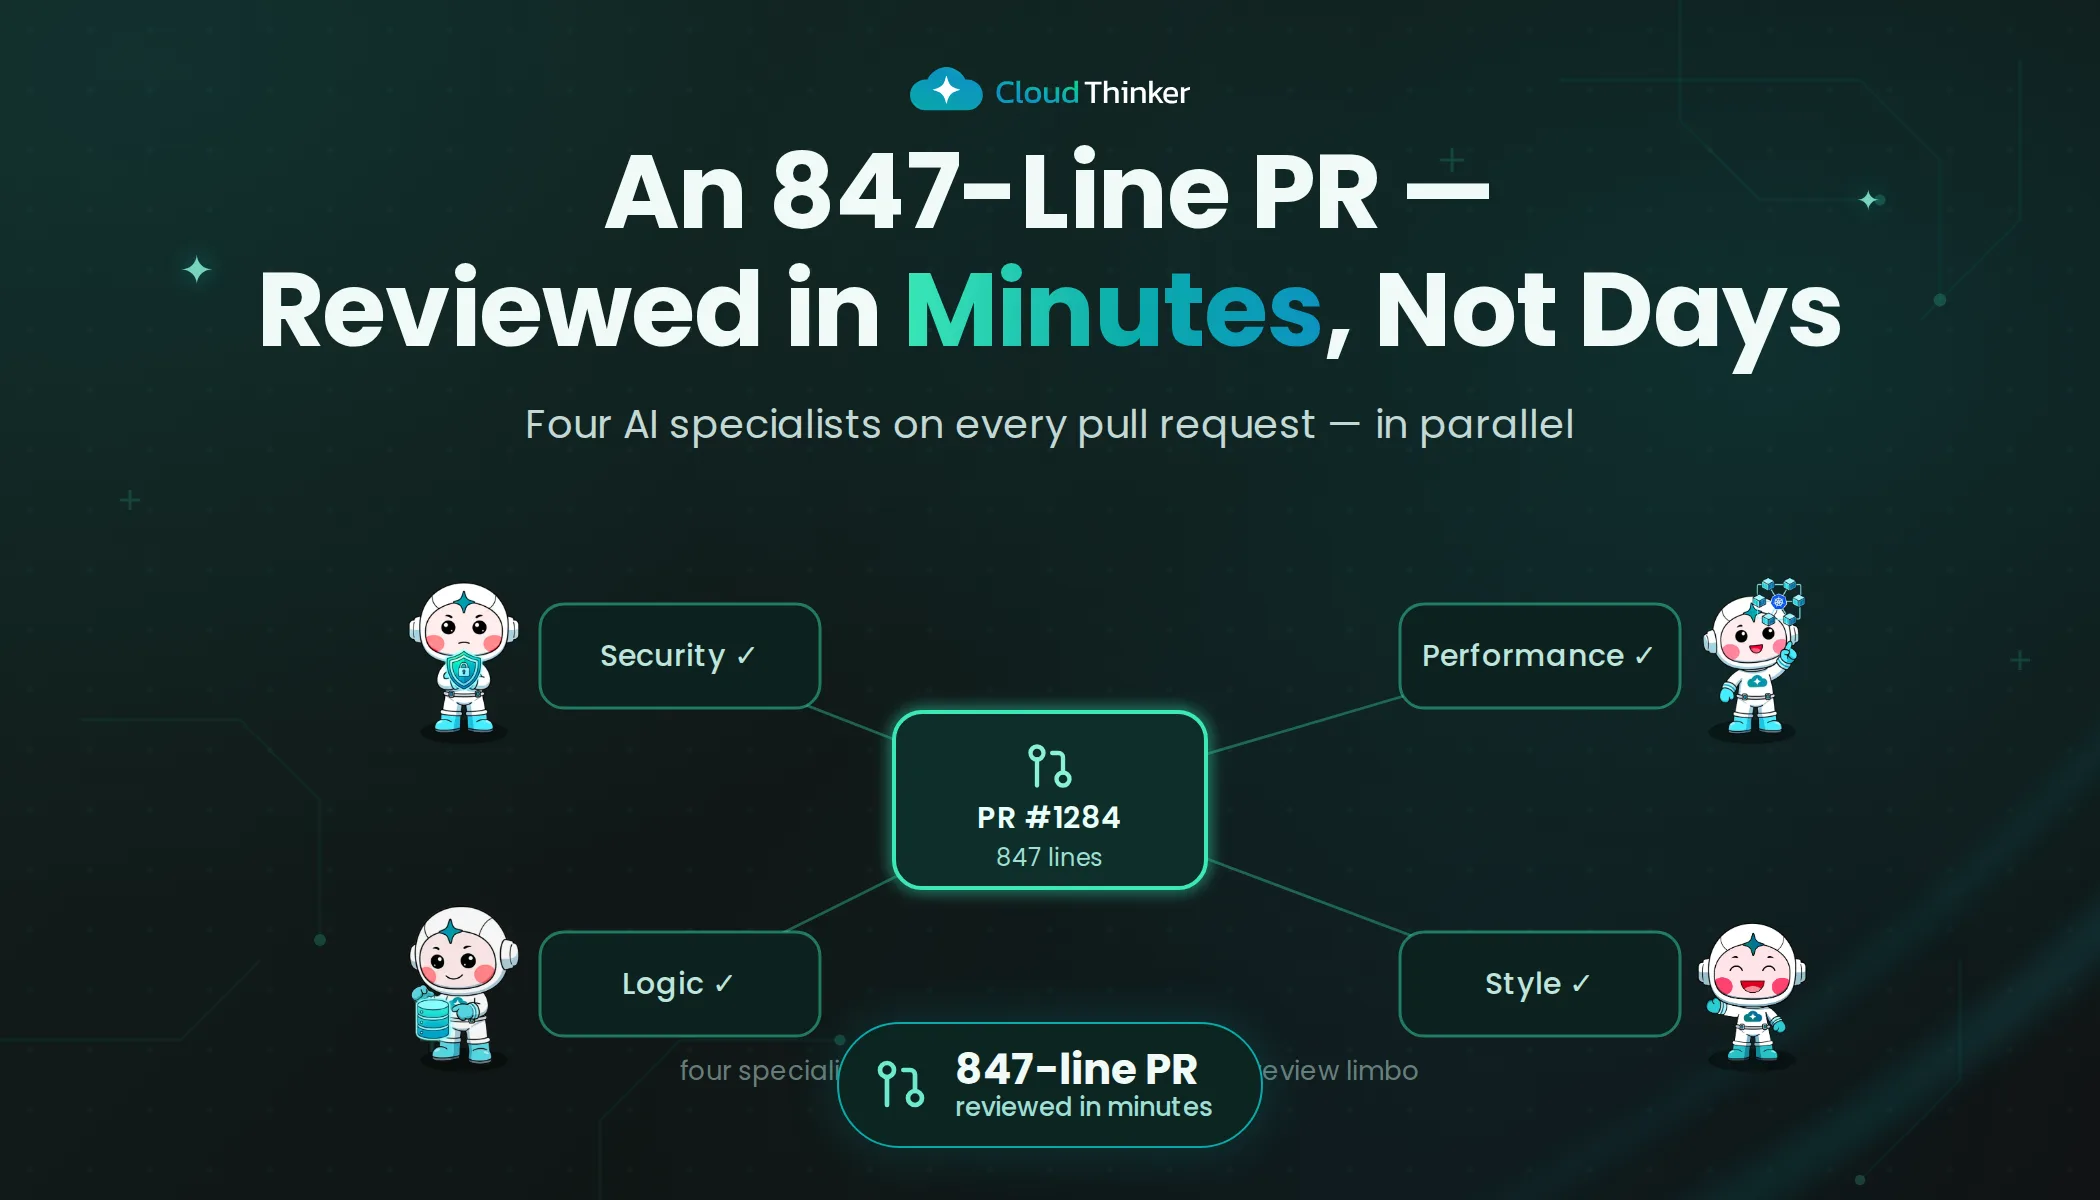
What Takes Your Team Days, AI Does in Minutes
Comprehensive code review stalls on calendars, not skill. The story of an 847-line auth PR that waited three days and shipped a race condition, and a benchmark on 37 real production bugs where CloudThinker caught 30 (81%), ahead of Greptile, Cursor, Copilot, CodeRabbit and Graphite.
Product
From Weeks to Hours: Building an AI-Powered Cloud Assessment Engine
A Well-Architected Review is sequential, a snapshot, and delivered as prose. This post explains how CloudThinker splits the review into independent pillar-by-resource conversations run in parallel, walks one right-sizing cell end to end, and shows why a weekly ten-minute assessment beats a yearly consulting report.
Product
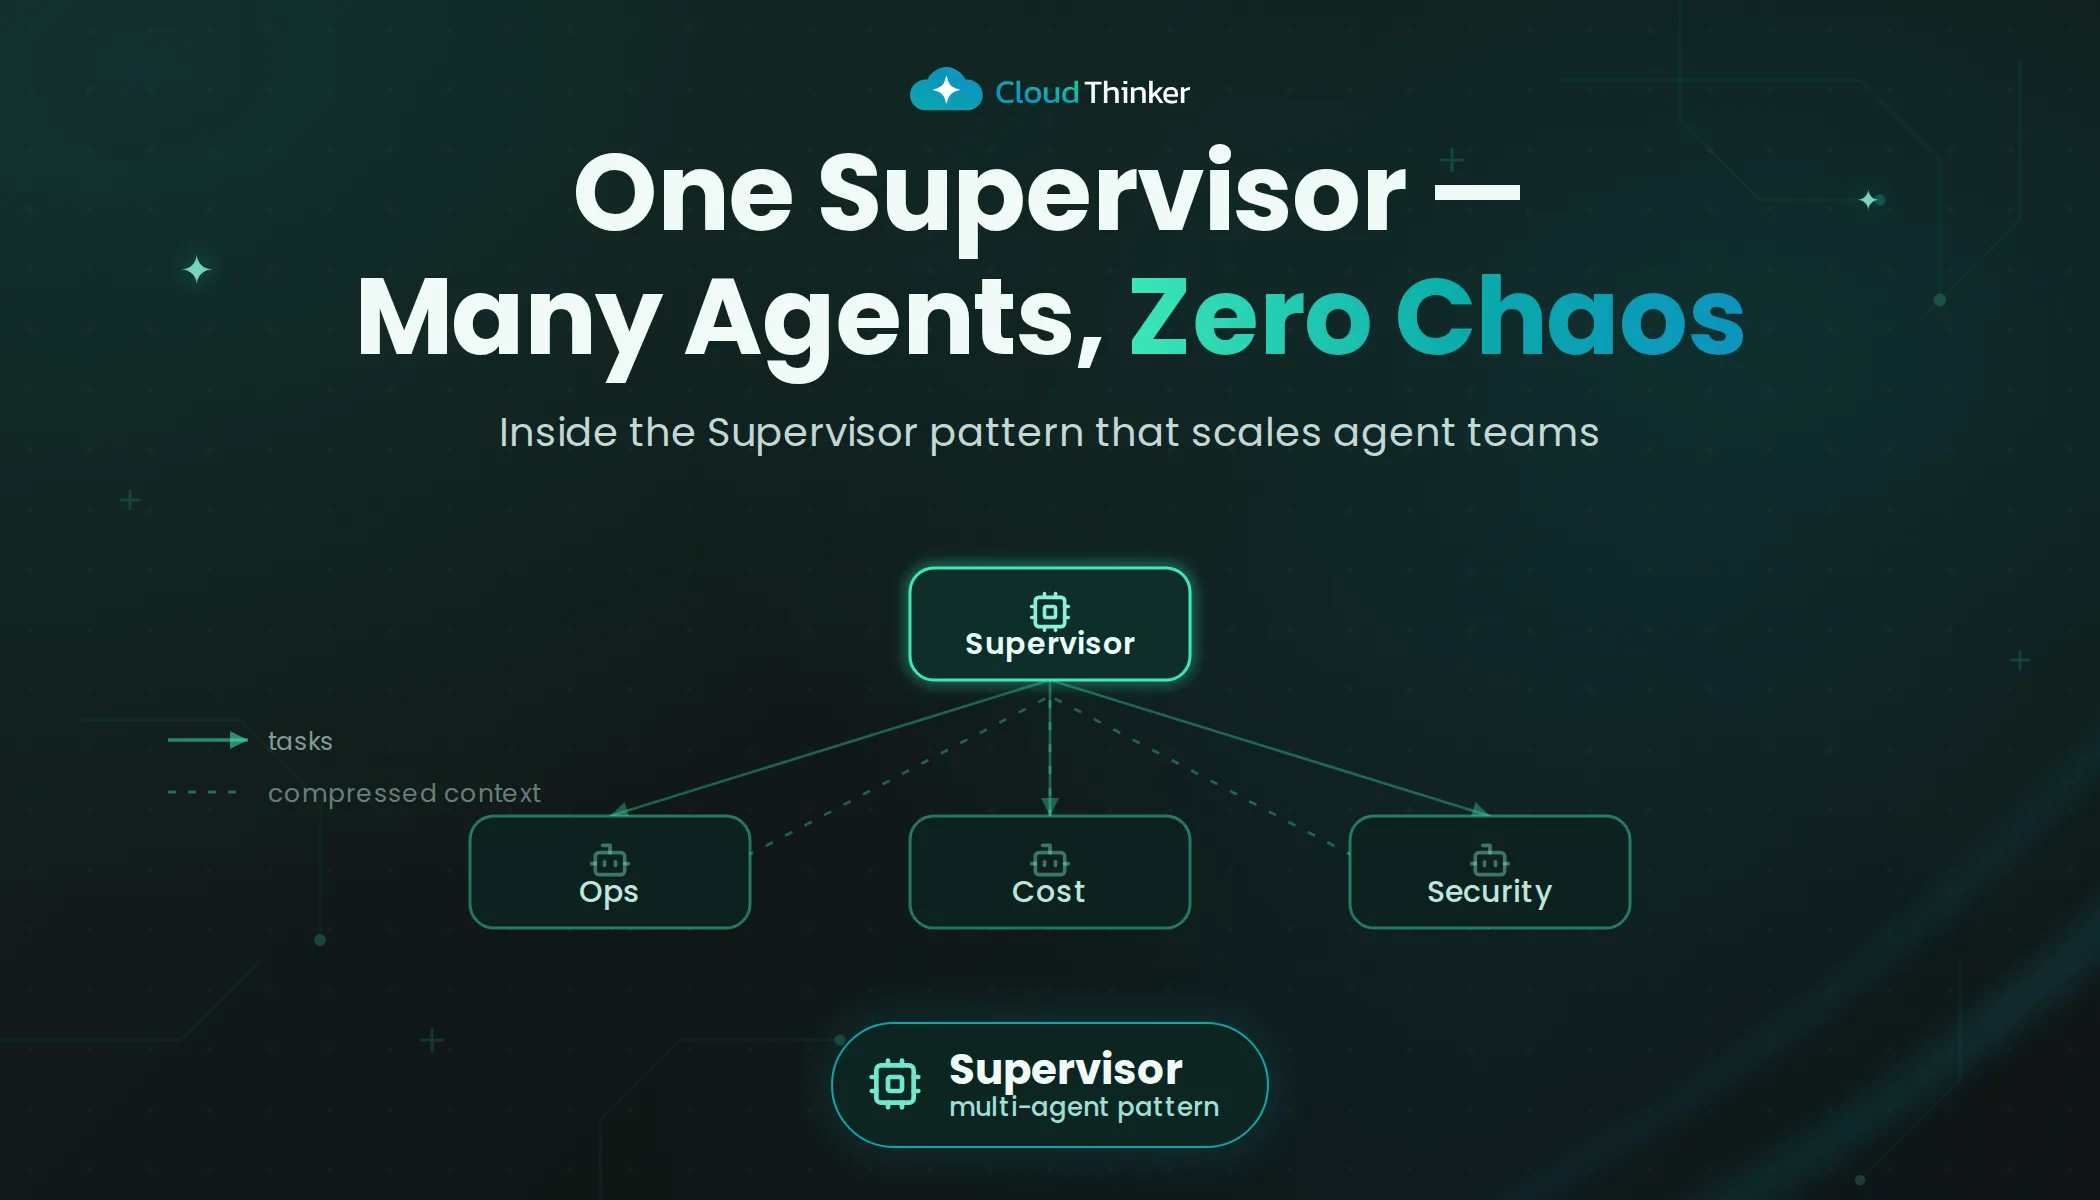
CloudThinker Agentic Orchestration and Context Optimization
One agent with every tool and one growing history hits a wall on long-running cloud work. This engineering deep dive covers the supervisor pattern, delegation versus transfer, three-tier prompt caching, asynchronous self-summarization, consolidated tools and parallel tool calls, with the token math behind each.
Case Study
How Diaflow Achieved Active-Active Architecture and SOC 2 Compliance in 28 Days
Diaflow needed active-active AWS infrastructure and SOC 2, HIPAA and GDPR readiness at once to unblock enterprise deals. CloudThinker ran migration, optimization, security and compliance in parallel against one architecture, compressing a 6-month roadmap into a 4-week sprint with 99.9% uptime and 80% less ops toil. The post walks through the CloudFront and S3 Content-Type incident resolved in 15 minutes.
Product
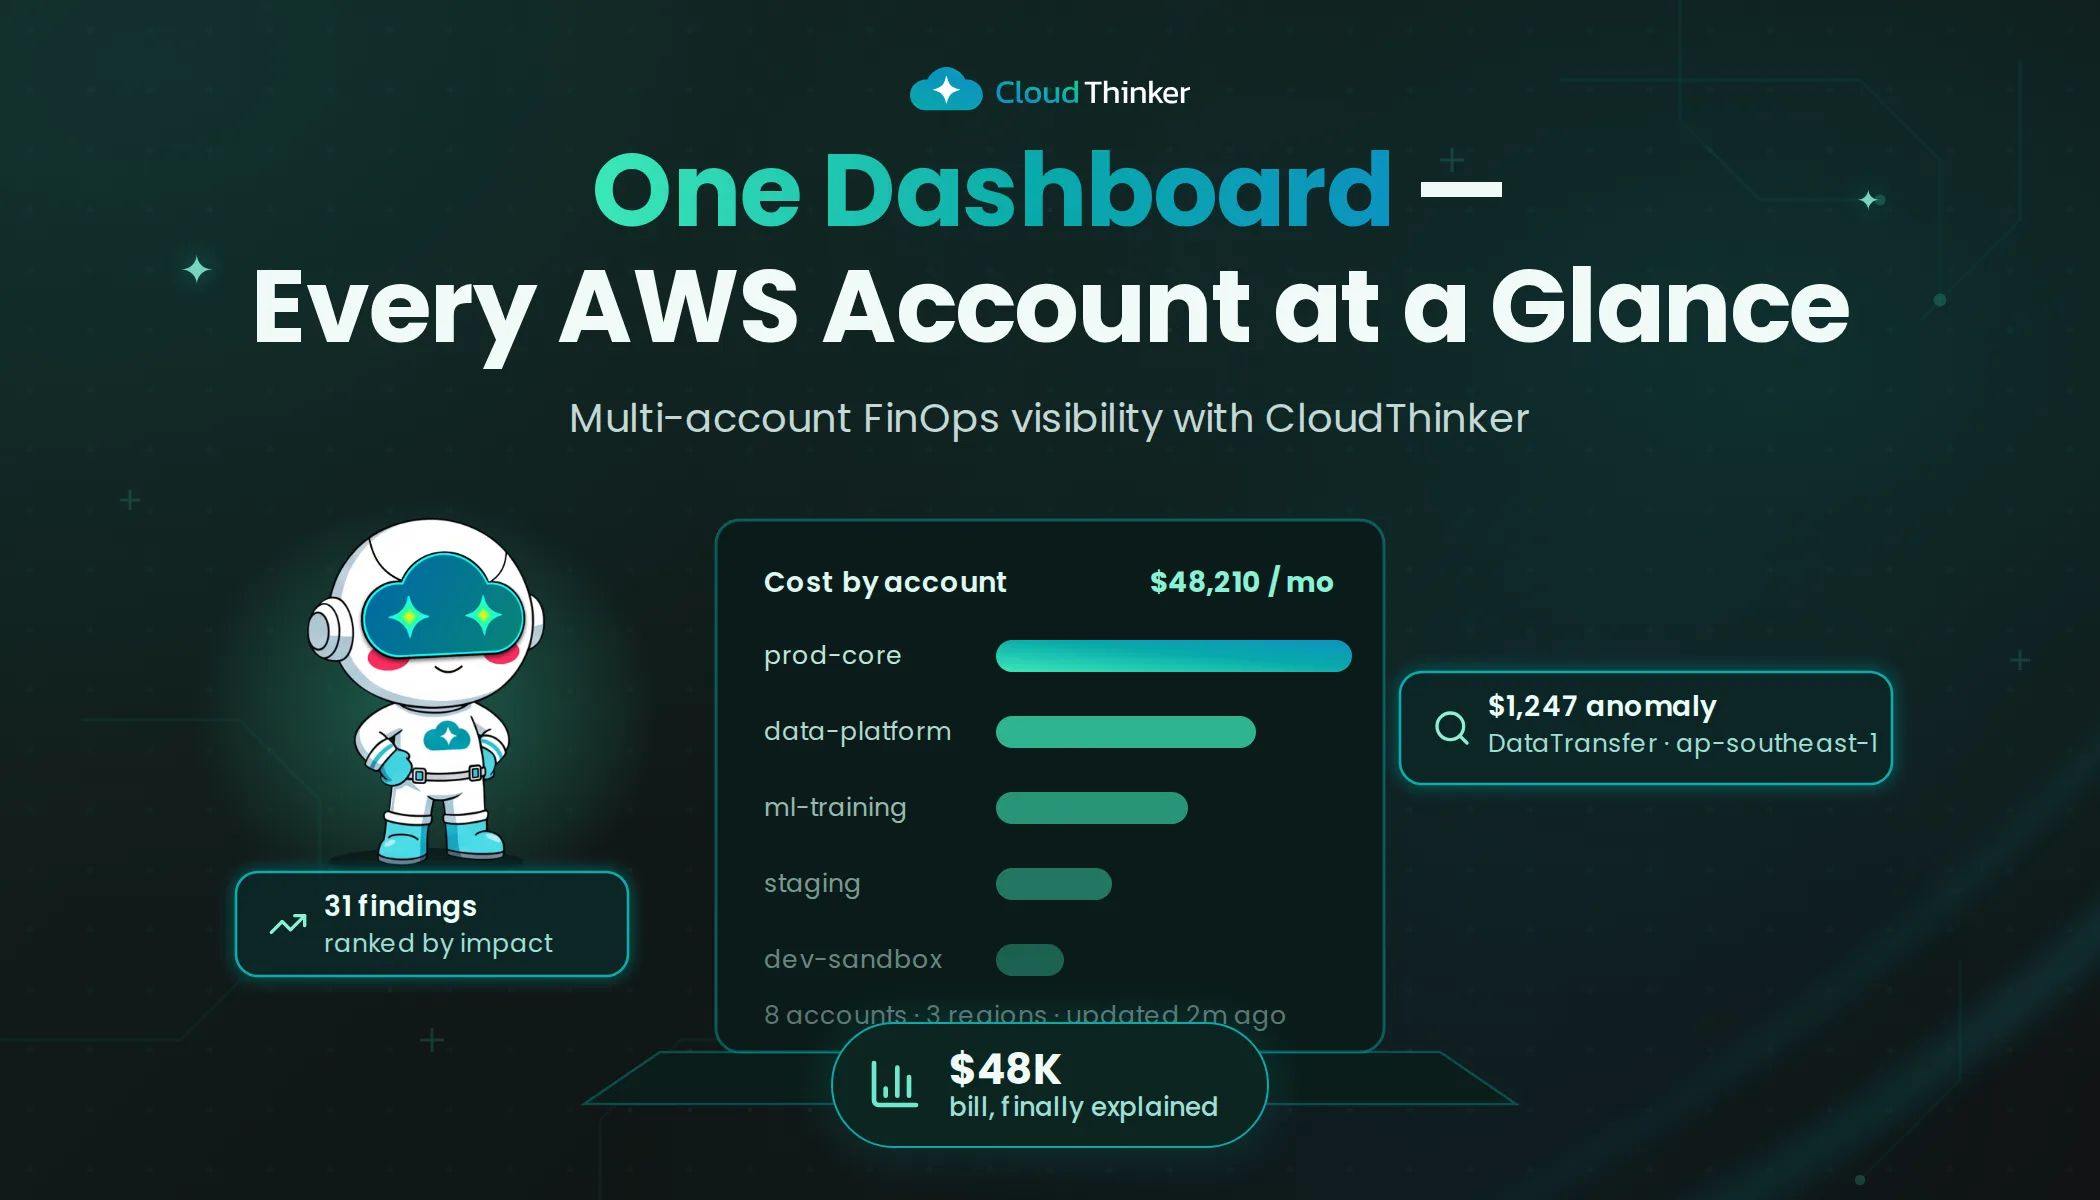
Building a Multi-Account FinOps Dashboard on AWS with CloudThinker
A CFO asks who owns a $48K AWS bill across eight accounts. This story follows how a unified FinOps dashboard traced a cross-region data-transfer loop by usage type, surfaced $8,450 a month in savings, and gave the VP of Engineering a line-by-line answer by Friday.
Product
CloudThinker Use Case: Global AWS FinOps & Cost Optimization
A $4,350 AWS bill was hiding 31 findings across 21 regions, including an m5.xlarge that sat at 0.2% CPU for nine months. This post shows how CloudThinker checks each finding before anyone acts on it (peaks over averages, owner and dependency checks, a snapshot before a stop), then follows the phased plan to $13,068 in annual savings.
How To
CloudThinker Tutorial 2025: How to set up credentials for AWS
Set up a dedicated, read-only IAM user for CloudThinker in a few minutes: least-privilege policy, access keys, connection, and a troubleshooting path with the exact AWS CLI checks. Includes when to move to a cross-account role.
Product
Mastering Multi-Cloud CostOps: Why Multi-Cloud CostOps Matters
Three clouds, three billing schemas, and a homegrown dashboard that lasted six weeks. Why multi-cloud cost tracking keeps breaking, and how an agent that investigates anomalies and acts within your policy changes the monthly cost review.
Product
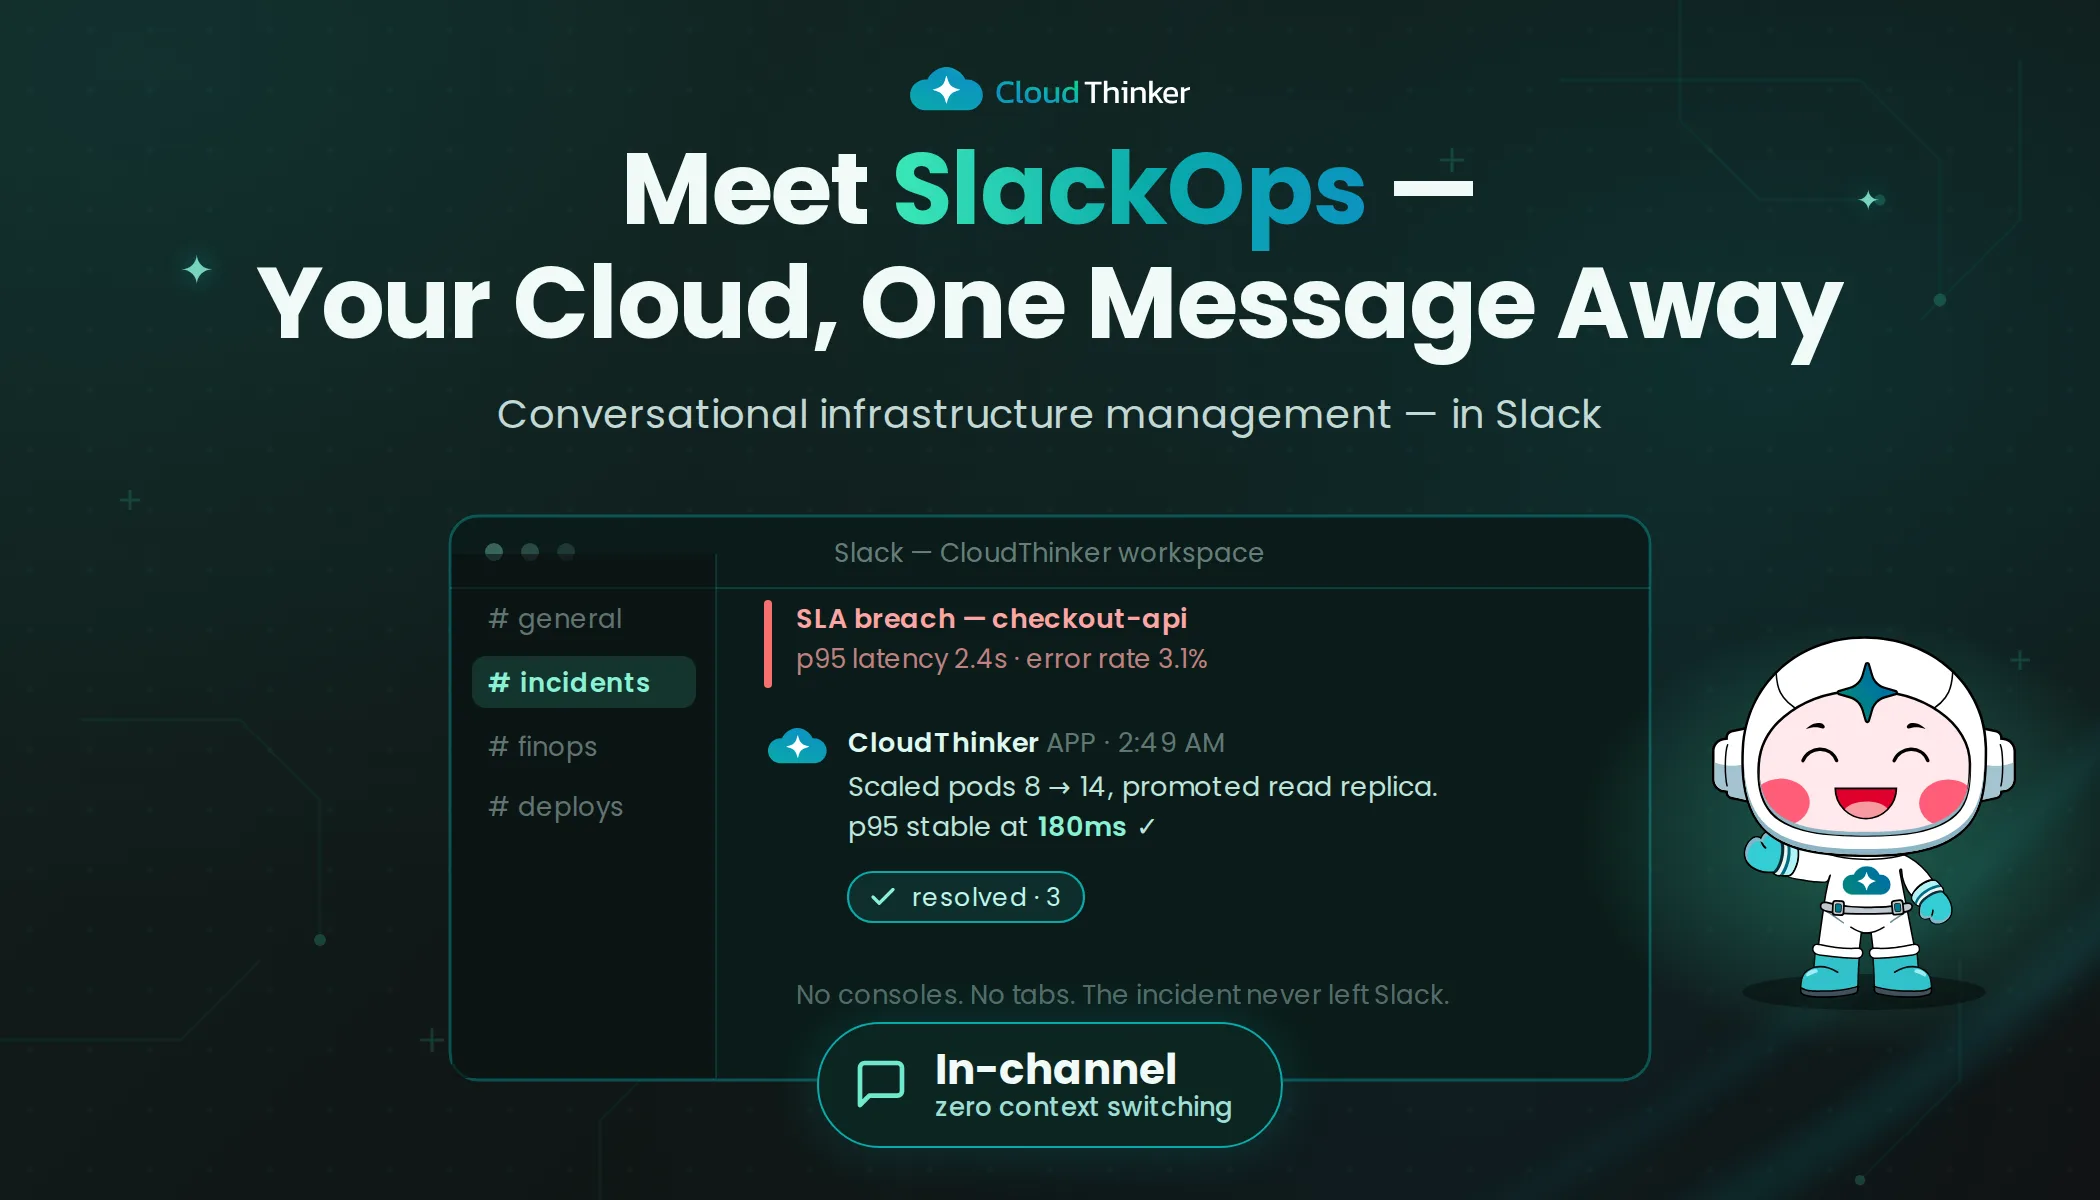
Introducing CloudThinker SlackOps: The Future of Conversational Infrastructure Management
ChatOps bots run the command you name, but at 2:47 AM the hard part is knowing which one. CloudThinker SlackOps investigates in the thread: it tests each hypothesis against metrics, logs and the database, posts a finding with a proposed fix, and acts through Auto Mode.
Product
The Kubernetes Agentic Operations Revolution: From Manual Management to Autonomous Intelligence with CloudThinker
One platform engineer, twelve clusters and a bad week: an OOMKilled loop, a CIS audit due Friday and a flash-sale traffic surge. This post shows why self-healing Kubernetes still needs a person, how CloudThinker investigates each case from hypothesis to a verified diff, and where Auto Mode draws the line.
Product
The Database Analytics Revolution: From Manual Queries to Intelligent Insights with CloudThinker
A data team with a 47-ticket backlog and two analysts hands the translation step from business question to SQL to CloudThinker. The CEO's churn analysis is walked end to end, including the cohort SQL and the data-quality checks that caught missing plan tiers and a logging gap, followed by how the backlog split between routine, draft and human-led work.
How To
Root Cause Analysis in Cloud Systems: The Complete Guide
Root cause analysis in distributed cloud systems: the seven-step RCA process, why diagnosis eats 60 to 80 percent of incident time, and the timeline, dependency-tracing and change-correlation techniques with real kubectl, journalctl, PromQL, git and CloudTrail commands.
How To
How to Reduce MTTR: What Actually Moves the Number
MTTR is the sum of five stages: detect, acknowledge, diagnose, fix and verify. This guide shows what eats the time in each, with one tactic per stage and a hypothesis-first diagnosis walkthrough with real kubectl and PromQL queries, and explains why diagnosis is the stage to compress first.
How To
Alert Fatigue: A Triage System That Lets On-Call Sleep
Alert fatigue is a triage problem, not a discipline problem. This guide builds a three-layer Alertmanager system (severity routing, grouping and inhibition, auto-triage) and works one 40-alert database failover down to a single page, with configs you can lint in CI.
How To
Runbook Automation: From Documents to Executable Operations
Runbook maturity is a ladder: documents, scripts, triggered automation, then agent-executed runbooks gated by Auto Mode. What each rung looks like, what breaks there, and the safety rules that keep automation from running a bad procedure at machine speed.
How To
Debugging Production Incidents: A Systematic Framework
A fixed sequence for debugging production issues while the pager is still going: stabilize, check what changed, form hypotheses with USE and RED, bisect the request path by layer, then roll back or fix forward with a rubric. Every step has a working command, and one incident is walked through the whole framework.
How To
Service Dependency Mapping: Why Topology Is the Missing Layer in RCA
Every RCA is a graph traversal: upstream, downstream, then the earliest anomaly in time. This post shows why topology beats log grep, assesses four DIY dependency maps (mesh, tracing, IaC graph, wiki) with working snippets, and explains why joining the graph to the change stream is the part that turns a map into an RCA engine.
How To
SonarQube Automation: 6 Quality-Gate Failure Patterns Draining Your Pipeline
Six SonarQube failure patterns that turn the quality gate into theater, from reflex overrides and stale new-code periods to unowned debt and rotting hotspots. Each comes with a UI path or Web API call you can run in an hour.
How To
SonarQube Automation with Native Tools: Quality Gates, Webhooks, and the Web API
Build SonarQube quality governance with only native features: a gate scoped to new code, the right new-code period, pipelines that wait for the gate, Web API trends, portfolios and PR decoration. Ends on where the native stack stops: it detects and enforces, but nobody triages.
Product
SonarQube Automation with AI Agents: From a Debt Number Nobody Owns to a Ranked List of What to Fix
CloudThinker reads SonarQube with a Browse-only token and does the triage the gate skips: real bugs vs style noise vs false-positive candidates, debt ranked by slope, and the commit behind every red gate. Every change goes through Auto Mode.
How To
CircleCI Automation: 7 Ways Your Pipeline Burns Credits
Part one of the CircleCI series names the seven patterns that quietly burn credits, from flaky-test reruns and oversized resource classes to cache misses and unattributed spend, each with a detection command. It also shows how to trace a doubled bill one hypothesis at a time, and why a monthly invoice review always finds waste 30 days late.
How To
CircleCI Automation: Build Triage with Native Tools (Insights, Config, and the v2 API)
Part two of the CircleCI series covers build triage with only what CircleCI ships: Insights and its API, test splitting, cache keys, approval jobs, rerun with SSH and v2 API reporting. It triages one red workflow by hand as infrastructure, flake or regression, and shows the ceiling: Insights names the flaky test but never decides what to do with it.
Product
CircleCI Automation with AI Agents: Build Triage That Ends the Rerun Reflex
Part three of the CircleCI series shows CloudThinker reading failed workflows over a read-only token, classifying each one as infrastructure, flake or regression, and tracing failures to the commit or the config.yml change behind them. Fixes like quarantine PRs and right-sized resource classes go through Auto Mode, and approval jobs always stay human.
How To
Secrets Detection Automation: Why Leaked Credentials Keep Winning
Deleting a leaked secret doesn't kill it. Part one maps why credentials keep landing in repos, why the backlog grows faster than anyone clears it, and how validity checks and honeytokens cut it to the few keys that matter.
How To
How to Run Secrets Detection Automation with GitGuardian's Native Tools
A hands-on build of secrets detection on GitGuardian's own tooling: ggshield in pre-commit and CI, validity-first triage over the API, and honeytokens. Then one valid AWS key worked by hand, which shows exactly where native automation stops.
Product
Secrets Detection Automation: From Valid-Key Alert to Revoked and Rotated
GitGuardian finds the valid key in minutes; revoking and rotating it takes days. Part three shows CloudThinker reading both GitGuardian and the cloud account the key opens, measuring blast radius, and running rotate, redeploy, revoke and verify with approval on every step.
How To
PagerDuty Automation: Where On-Call Toil Hides Even When Paging Works
PagerDuty gets the right person paged fast, but the minutes between the ack and understanding what broke are where MTTR really lives. This guide measures five kinds of on-call toil that survive a clean paging setup, each with a REST API query you can run today.
How To
PagerDuty Automation with Native Tools: Event Orchestration, Incident Workflows, and Webhooks v3
A hands-on guide to PagerDuty's native automation: Event Orchestration rules, alert grouping, service dependencies, response plays, status updates, Webhooks v3 and the Analytics API. It walks one grouped incident through three hypotheses to show that orchestration decides who gets paged, not what is wrong.
Product
PagerDuty Automation with AI Agents: From Page to Root Cause
How CloudThinker turns a triggered PagerDuty incident into a diagnosis: it reads the alert, tests the likely readings against your monitoring, cloud and deploy history, and writes the cause and proposed fix where the responder already looks. Escalation policies stay untouched, and every write goes through Auto Mode.
How To
ArgoCD Automation: 7 GitOps Drift and App-Health Failures That Go Unwatched
Eleven yellow apps on the ArgoCD dashboard and nobody is alarmed. This guide walks the seven GitOps drift and app-health patterns that go unwatched, each with the argocd or kubectl command that detects it, and works one OutOfSync app end to end to show what deciding keep or revert actually takes.
How To
ArgoCD Automation With Native Tools: Sync Policies, Health Checks, and Safe Reconciliation
Everything ArgoCD can do natively against drift: sync policies, sync windows, Lua health checks, hooks, notifications and ignoreDifferences, with exact configs and a CLI triage of one drifted app. It ends where the native tools stop: they can revert every drift or keep every drift, but they can't judge which one was right.
Product
Automating ArgoCD GitOps with an AI Agent: From OutOfSync Noise to Safe Reconciliation
selfHeal reverted a 2 a.m. hotfix and reopened the incident. Here's how CloudThinker connects to ArgoCD read-only, classifies each OutOfSync as a manual hotfix, controller mutation or chart bug from the diff and field ownership, and proposes the safe action. Writes go through Auto Mode, and a hotfix is never silently reverted.
How To
Ansible AWX Integration: 7 Failure and Waste Patterns in Job and Inventory Ops
Part one of the AWX series maps the seven patterns that quietly rot AWX operations, from failed jobs nobody reads to inventories drifting from the cloud, credential sprawl and stale project syncs. Each comes with a detection step through the UI, the awx CLI or the REST API, plus a worked read of one red job.
How To
Ansible AWX Integration: Automation Ops with AWX's Native Tools
Part two builds AWX ops automation with native features only: dynamic inventories with update on launch, surveys and check mode, convergence and approval nodes, failure notifications, a triage script over job_host_summaries, and schedule hygiene. It ends on where that structure stops: it routes decisions but never reads a red job.
Product
Ansible AWX Integration with AI Agents: From Failed-Job Archaeology to Automation Ops
Part three puts CloudThinker on top of AWX with a read-only token, so every failed job arrives classified as unreachable hosts, a broken credential or a task regression, with the evidence attached. It walks one nightly patch failure end to end, covers inventory reconciliation and approval-gated template launches, and how Auto Mode gates every write.
Product
The Connection Value Ladder: What to Expect in the First Five Minutes, the First Week, and Every Month After
Part one of the Connection Value series: a four-rung test for any tool you connect to an operations platform (first minute, first week, continuous, compounding). It explains why integrations become data sinks, how to verify a read-only role with IAM's policy simulator, and how Auto Mode gates the moment an agent earns write access.
Product
Connect a Cloud Account, See Dollar Findings in Five Minutes
Part two of the Connection Value series: what a read-only AWS, Azure or GCP connection should hand you in five minutes, a week and a month, with the CLI sweep it replaces and exactly what read-only access will not do.
Product
Connect a Repo, Get Your First PR Review in Minutes
Part three of the Connection Value series: connect GitHub or GitLab and CloudThinker reviews your latest open PR in minutes, read and comment only. The bigger payoff is operational memory: cost predictions on IaC PRs, deploy markers that turn 'what changed?' into a lookup, repo-to-service ownership and a weekly AppSec scan in the same queue as cloud posture.
Product
Connect Jira, Get a Toil Analysis Within the Hour
Part four of the Connection Value series: connect Jira or ServiceNow read-only and get a toil analysis of your own ticket history within the hour, then climb from auto-triage to auto-resolution one category at a time, through Auto Mode.
Product
Connect PagerDuty, Get an Alert Noise Audit, Then Watch MTTR Fall
Part five of the Connection Value series: connect PagerDuty, Better Stack or Opsgenie with a read-only key and get an Alert Hygiene report on 30 days of pages in the first hour. Includes the PagerDuty REST API calls to build the audit by hand, one noisy source traced end to end, investigation-on-page with a target alert-to-hypothesis time under five minutes, and an Auto Mode policy by severity.
Product
From Runbooks to Hours Saved: Automations That Prove Their Own Value
Automation programs stall on two questions: what to automate first, and whether it paid off. CloudThinker ranks candidates from your own Jira toil and alert history, turns prose runbooks into SKILL.md files with a sandbox dry-run, and records an auditable hours-saved ledger for every run.
Product
The Compounding Effect: Why Every New Connection Makes the Others Smarter
Part seven of the Connection Value series: why integrations that each answer their own question never compound, four connection pairs that answer questions neither can alone, and the traceable QBR ledger you should demand from any platform.
How To
Prometheus Alerting: 6 Failure Modes That Bury Real Incidents
Six Prometheus alerting failure modes, three noisy, two blind and one plain wrong, each with the PromQL or config that detects or fixes it.
How To
DIY Prometheus Alerting: Rules Files, Alertmanager, and promtool
Build Prometheus alerting end to end with native tools: tested rules files, recording rules, Alertmanager routing and inhibition, amtool silences and webhooks. Then see why all of it manages delivery and none of it explains why an alert fired.
Product
Automate Prometheus Alerting with AI Agents: From Page to Root Cause
Every Prometheus page starts the same ten-query ritual. This post follows one latency alert through scrape health, per-instance p95, a dependency check and a rollout correlation to a named cause, with remediation held for approval.
How To
New Relic Automation: The APM Signals Actually Worth Alerting On
Most New Relic accounts alert on the wrong signals. This guide measures condition sprawl and static-threshold noise with NRQL, then lays out the four APM signals worth paging on and the entity graph nobody uses during triage.
How To
New Relic Alert Automation with NRQL, Workflows, and NerdGraph
A hands-on build of New Relic's native alerting stack: NRQL conditions with the right aggregation and loss-of-signal settings, policies, workflows with enrichments, muting rules, correlation and NerdGraph. It ends by walking one p95 alert through three hypotheses to show where routing stops and investigation starts.
Product
New Relic Automation with AI Agents: From Alert to Root Cause
How CloudThinker picks up a New Relic issue and runs the NRQL chain an SRE would: errors by transaction and class, percentiles and throughput, then deployment markers across related entities, ending in a finding with a proposed fix. Fixes go through Auto Mode.
How To
Dynatrace Integration Guide: From Davis Problems to Faster Action
Davis detects a problem in ninety seconds; the fix can still wait four hours. Part one maps what Dynatrace already solves, why integrations should consume Davis problems rather than raw metric events, and how to validate a root-cause candidate with the Problems API and DQL before acting.
How To
Dynatrace Automation with Native Tools: The DIY Integration Guide
The usual Dynatrace integration ends at a Slack webhook. Part two builds the rest natively (custom problem notifications, Problems API v2, DQL and the Grail query API, Workflows, alerting profiles and maintenance windows), walks one problem through it, and shows the judgment that stays manual.
Product
Dynatrace Integration with AI Agents: Automating Problem Remediation
Part three puts CloudThinker on the Davis Problems feed as the action layer. A read-only token, DQL enrichment, a check of changes Dynatrace can't see, and validation of the root-cause candidate produce a proposed fix that goes through Auto Mode, then closes the problem with an evidence comment.
How To
RabbitMQ Monitoring: 6 Signals That Predict an Outage
RabbitMQ outages build for days in metrics nobody watches. The six signals that predict them (depth vs drain, stuck unacks, undrained DLQs, resource alarms, quorum health, churn), a detection command for each, and a worked example for reading a backlog.
How To
RabbitMQ Monitoring with Native Tools: rabbitmqctl, API, Prometheus
A hands-on RabbitMQ monitoring setup using only what ships in the box: rabbitmqctl triage, management API sweeps, Prometheus alert rules and guardrail policies. Plus an honest map of what each tool can and can't tell you.
Product
Automating RabbitMQ Monitoring and Operations with AI Agents
Thresholds tell you a queue is backing up. CloudThinker works out which consumer stopped, why, and what the DLQ shows, then proposes a fix that goes through Auto Mode. Read-only management API user, about five minutes to connect.
How To
Fleet Telemetry Analysis on flespi: What Breaks at Scale
Forty trackers went dark last week and nobody knows which forty. This guide maps the five ways flespi fleets degrade quietly (silent devices, parsing errors, stream backlogs, drift, retention) with a panel path or REST call to detect each.
How To
Fleet Telemetry Analysis with Flespi's Native Tools: Panel, API, MQTT
A hands-on flespi monitoring workflow with only native tools: panel, REST sweeps, MQTT, streams and calculators. It includes one silent device investigated by hand, and is honest about where scripts stop and investigation starts.
Product
Automating flespi Fleet Telemetry Analysis with AI Agents
Turning '40 devices offline' into causes: CloudThinker connects to flespi with a read-only token, judges each tracker against its own reporting rhythm, and rules out parked, cellular, protocol and hardware before anyone looks. Fixes go through Auto Mode.
How To
Coralogix Integration Guide: From Alert to Investigated Answer
Most Coralogix triage time goes to assembling evidence, not thinking. Part one shows the three settings that decide how long it takes (alert type, TCO tier routing, saved queries) and walks a checkout error-ratio alert hypothesis by hypothesis with real DataPrime, Lucene and PromQL queries.
How To
DIY Coralogix Integration: Alert Automation with Native Tools
A hands-on build of Coralogix alert automation using only native features: ratio and flow alerts, generic webhooks with deep links and sample logs, alert definitions as code, scripted DataPrime triage and TCO policies. It ends where native automation stops: it gathers context, it doesn't investigate.
Product
Coralogix Integration with AI Agents: From Page to Root Cause
Coralogix alerts arrive fast and still uninvestigated. Part three puts CloudThinker on the receiving end: a read-only API key, an investigation that picks each next query from the last result, a check of cloud-side changes Coralogix never sees, and fixes that go through Auto Mode.
How To
AppDynamics Health Rules: Separating Real Violations From Noise
Part one of the AppDynamics series covers the six patterns that bury real health rule violations in noise: untuned defaults, the wrong baseline, deploy storms, node-versus-tier scope, flattened violation lifecycles and email-only policies. Each comes with a way to spot it in your Controller, plus a worked check of one recurring violation.
How To
Automating AppDynamics Health Rule Responses with Native Tools
Part two tunes AppDynamics health rules and automates violation response with native features only: seasonal baselines, evaluation windows and load floors, suppression and deploy markers from CI, policies with diagnostic sessions and remediation scripts, HTTP request templates, and the REST APIs. It ends at the ceiling: native actions run predefined steps, and nobody reads the snapshots.
Product
Automating AppDynamics Health Rule Response with AI Agents
Part three puts CloudThinker on top of AppDynamics with a read-only API client. Health rule violations then arrive investigated: per-node metrics and slow snapshots are read, the slow call is matched to the release that introduced it, and a rollback is proposed for approval. It keeps the 'AppDynamics alternative' framing: add an action layer instead of migrating.
How To
Zabbix Automation Starts With a Problem Queue You Can Trust
Zabbix automation fails on an untrusted problem queue. Five patterns that bury it (sprawl, flapping, missing dependencies, endless maintenance, unsupported items), the trigger shapes that carry real signal, and one 41-day High problem read three ways.
How To
Zabbix Automation with Native Tools: Triggers, Actions, and the API
Fixing a Zabbix problem queue with native features: recovery expressions, time windows, dependencies, escalations, remote commands, expiring maintenance and API audits. Then a 38-host agent storm traced through three readings, and the ceiling: actions execute what triggers decided.
Product
Zabbix Automation with AI Agents: From Problem Queue to Resolution
CloudThinker reads the Zabbix problem queue over a read-only API token, sorts each problem into outage, flap, capacity or noise, and checks its history before proposing a fix. The worked example: a remote command quietly restarting a leaking worker nine times a week.
How To
SigNoz Integration: The Observability Signals That Actually Matter
An OpenTelemetry-native SigNoz setup puts every trace three clicks away, yet incidents still wait forty minutes for a person to look. This guide covers the six signals worth watching, a hypothesis-first p99 investigation, alert rules across all five signal types, and why the gap remains.
How To
Automating SigNoz Alerts with Native Tools: Rules, Channels, Audits
A hands-on SigNoz alerting cleanup: audit existing rules into stale, noisy, overlapping and keepers, rebuild the keepers with the right query type, wire Alertmanager-style webhooks, and see where native automation stops: channels deliver alerts, they don't read traces.
Product
SigNoz Integration with AI Agents: From Firing Alert to Named Cause
What happens after a SigNoz rule fires: CloudThinker tests three readings (deploy regression, shared saturation, slow upstream) with spans split by service version, PromQL and rollout history, then posts a named cause and a rollback proposal for approval.
How To
Rollbar Automation Starts With Triage: 5 Signals Worth a Human
Most Rollbar projects end up as a graveyard of thousands of Active items. This guide covers the five triage failure modes behind that (one-channel routing, lying fingerprints, missing deploy tracking, mute culture) and gives an RQL or UI check for each one.
How To
Rollbar Automation with Native Tools: Deploys, RQL, Webhooks
The native Rollbar error-response setup, built in order: deploy tracking first, then severity routing, RQL investigation queries, resolve-in-version and webhooks. It ends at the honest ceiling: rules route items, but nobody reads the stack trace for you.
Product
Rollbar Automation with AI Agents: From Stack Trace to Named Commit
Rollbar delivers a stack trace; CloudThinker delivers the investigation. One TypeError followed end to end: three readings, RQL by version and cohort, the deploy diff and an infra check, then a named commit and a rollback proposal waiting for approval.
How To
Better Stack Integration Guide: Where Incident Toil Still Lives
Part one of the Better Stack series: detection and paging are solved, but five gaps still eat on-call time after the acknowledgment: the context hunt, unwired heartbeats, logs in another tab, timelines rebuilt by hand, and silent status pages. Each comes with an Uptime API call or console check to find it in your own account.
How To
How to Automate Incident Response with Better Stack's Native Tools
Part two of the Better Stack series: tune monitors, heartbeats, escalation policies, the incidents API and webhooks, Telemetry logs and status pages, with exact settings and curl calls. It ends on the ceiling: native tooling cuts time to human, but time to cause is still manual.
Product
Better Stack Integration: AI Agents From Alert to Root Cause
Part three of the Better Stack series: CloudThinker connects over OAuth (read-only by default) and starts investigating as soon as an incident opens, while the page is still going out. In the worked example it reads the failure type, the logs and the cluster behind the endpoint, then names the cause (an OOM after a deploy) and proposes a rollback for approval. Escalation is untouched, and every write goes through Auto Mode.
How To
Langfuse LLM Observability: 6 Failure Modes Your Logs Won't Catch
LLM features fail with HTTP 200: a worse answer, a slower chain, a bigger token bill. Six drift patterns your APM stack can't see, why they happen, and a Langfuse check for each one you can run today.
How To
Langfuse LLM Observability with Native Tools: Traces, Prompts, Evals
The full native build in Langfuse: sessions and nested spans, prompt labels, scores and LLM-as-a-judge, dashboards and the Metrics API. Then one score regression worked by hand, and where the DIY ceiling sits.
Product
Automate Langfuse LLM Observability with CloudThinker AI Agents
When an LLM feature gets worse instead of down, nobody gets paged. CloudThinker reads your Langfuse traces, scores and prompt versions read-only, works the regression end to end, and proposes the fix for a named person to approve.
How To
Jenkins Build Failure Analysis: 6 Patterns Wasting Your CI Hours
Most red Jenkins builds aren't the commit's fault. Six recurring patterns, from retry-until-green flakes to unmeasured queues, each with its log signature and a Script Console or grep check you can run today.
How To
Jenkins Build Failure Analysis Using Only Native Tools
A hands-on Jenkins triage kit using only native tools: Script Console Groovy, stage logs, JUnit trends, discarders, the REST API and retry/timeout wrappers. Includes one red build triaged end to end, and the point where native tooling stops.
Product
Automated Jenkins Build Failure Analysis with CloudThinker Agents
CloudThinker reads Jenkins over a read-only API token and classifies every red build as infrastructure, known flake or real regression, with the log excerpt, test history, changeset and node state attached. Fixes go through Auto Mode.
How To
Firebase Security Rules Audit: The Misconfigurations That Expose Your App
Seven Firebase misconfigurations across rules, perimeter and credentials, from test-mode rules that became 'if true' to App Check left in monitoring. Each comes with a console path or command to detect it, and a walk-through of judging one ambiguous rules hit.
How To
How to Audit Firebase Security Rules with Native Tools
A one-hour Firebase security rules audit using only the Firebase CLI, the Rules management API, the Rules Playground, the Emulator Suite and the App Check and Auth consoles. It shows how to judge a grep hit with evidence, and why a point-in-time audit can't catch Thursday's release.
Product
Automating Firebase Security Rules Audits with an AI Agent
How CloudThinker watches every Firebase rules release with viewer-only access, diffs it against the last ruleset, and judges a widening change against the data model and sign-in providers. Covers Auto Mode, an illustrative first scan and prompts to try.
How To
Cloudflare Automation Starts Here: 6 Zone Config Messes to Find First
Part one of the Cloudflare series maps the six places zone configuration rots: legacy page rules, unowned DNS records, permanent WAF exceptions, settings drift, unread security events and unwatched edge signals, each with a read-only API check. It also walks one stale page rule through three hypotheses and explains why one-time cleanups don't last.
How To
DIY Cloudflare Automation: API Tokens, Notifications, Health Checks
Part two of the Cloudflare series builds DIY automation with scoped API tokens, the API for DNS, WAF and cache purges, Notifications, health checks and the audit log. It investigates one WAF spike by hand with GraphQL and the audit log, then shows the ceiling: the API executes decisions you already made, and nothing native connects a symptom to the change behind it.
Product
Cloudflare Automation with AI Agents: From Alerts to Safe Action
Part three of the Cloudflare series shows CloudThinker connected through a read-only scoped token: it keeps a live inventory of every zone, groups security events, and checks each symptom against the audit log. One 2 a.m. WAF spike plays out two ways, credential stuffing filed for the morning or a deleted exception escalated with the diff, with every write gated by Auto Mode.
How To
Neon Postgres Performance: What Slows Serverless Postgres Down
Neon's serverless design changes what slow means: cold starts, autoscaling ranges, pooled vs direct connections, and CU-hour billing sit on top of the classic Postgres missing-index problem. The guide gives a detection step for each and walks a misleading 8:58 a.m. latency alert through to its real cause.
How To
Neon Postgres Tuning with Native Tools: Branches, Stats, and Sizing
A hands-on Neon tuning pass with only native tools: Monitoring and LFC hit rate, autoscaling sizing, pooled vs direct endpoints, pg_stat_statements and EXPLAIN (ANALYZE, BUFFERS). Every fix is proven on a copy-on-write branch before it touches main. It also covers how to keep query stats when every suspend wipes them.
Product
Automating Neon Postgres Tuning with an AI Database Agent
On Neon, an index proposal can arrive already proven. CloudThinker watches query stats, autoscaling headroom and connections, then rehearses each fix on a branch of production and measures it before asking for approval. Nothing runs DDL on main without a named approver.
How To
Elasticsearch Index Management: 6 Problems Hiding in Your Cluster
Six Elasticsearch problems that hide behind a cluster that still answers queries: yellow forever, oversharding, stuck ILM, missing slow logs, disk watermarks and mapping explosions. Each comes with one API call to detect it, and a walk-through of how four of them chain into one amber tile.
How To
Hands-On Elasticsearch Index Management with Native Tools
A hands-on tour of Elasticsearch index management with only what ships in the cluster: _cat APIs, allocation explain, ILM with data streams, slow logs and SLM. It walks one 'search is slow' report through three readings and ends on why the DIY loop observes but never investigates.
Product
Automating Elasticsearch Index Management with AI Agents
How CloudThinker connects to Elasticsearch with a monitor-only API key and walks a yellow cluster back to its cause: a disk watermark, one 1.4 TB index and an ILM step stuck on a repointed alias. Covers Auto Mode, an illustrative first scan and prompts to try.
How To
Server Automation Agents: Taming the SSH Toil on Your Linux Fleet
Five categories of SSH toil on a Linux fleet, with the commands you keep typing, and the risk ladder that decides which commands are safe to automate. Read-only inspection is most of the toil and none of the risk.
How To
Linux Server Automation with Native Tools: cron, systemd, SSH
A DIY build of Linux server automation with systemd timers, hardened SSH, restricted keys, fleet loops, logrotate and unattended-upgrades, with copy-paste configs. Then the honest ceiling: scripts execute, they don't observe, decide or explain.
Product
A Safe Server Automation Agent Over SSH: From Inspection to Action
CloudThinker works over SSH with a dedicated key, enrolled hosts only and an unprivileged user, and investigates before it proposes: one full disk alert traced to the file, the process and the deploy that caused it. Anything that changes a host goes through Auto Mode.
How To
Vault Monitoring: The 7 Security Signals That Actually Matter
Vault rarely goes down; it drifts. Seven signals (seal and HA, root and long-lived tokens, wildcard policies, audit devices, KV read patterns, lease TTLs) with a detection command for each, and a worked example of reading one never-expiring token three ways.
How To
How to Audit and Monitor HashiCorp Vault with Native Tools Only
A five-pass Vault audit with only the CLI, the sys API and jq: health, tokens, policies, audit log, telemetry. Then one KV read spike worked through three readings, and an honest look at what the native stack leaves to a person.
Product
Automating Vault Monitoring and Audit with an AI Security Agent
CloudThinker audits Vault continuously through a read-only policy you can read in full: tokens, policies, audit devices, seal health and KV read baselines. A suspicious read spike is investigated end to end, and nothing is revoked without approval.
How To
Vercel Monitoring: 6 Failure Modes Behind a Green Deploy
A green Vercel deploy only proves the build passed. Six failure modes that hide behind it, where each signal lives, one inspection step per mode, and a 500 spike worked through three readings with three CLI commands.
How To
How to Monitor Vercel with Native Tools (CLI, Log Drains, Rollbacks)
Native Vercel monitoring tool by tool: the CLI, rollback and promote, log drains, webhooks and Spend Management, with copy-paste commands. One failed build is traced through three readings, and the post is clear about where notification stops and investigation begins.
Product
Automate Vercel Monitoring with AI Agents: From 500 Spike to Rollback
CloudThinker reads Vercel through a Viewer-role token, ties a 500 spike to the promotion and commit behind it, separates regressions from env drift and upstream failures, and stages the rollback for approval.
How To
Keycloak Audit: 7 Misconfigurations That Quietly Expose Your SSO
Seven Keycloak misconfigurations that quietly expose SSO, from wildcard redirect URIs to admin service accounts and missing events, each with a kcadm.sh check. Shows how the findings chain into an identity-provider takeover and why a yearly access review can't keep up with realm drift.
How To
Keycloak Audit with Native Tools: kcadm.sh, Events, and the Admin API
A hands-on Keycloak audit in five sweeps with kcadm.sh, admin events and the Admin REST API, plus a twenty-line weekly diff script. Ends on what native tools answer and where they stop: they find drift but can't judge it.
Product
Automating Your Keycloak Audit with an AI Security Agent
How CloudThinker keeps a Keycloak audit running continuously over a read-only service account, and investigates each access-widening change (who, from where, is it used) before proposing a fix. Realm changes go through Auto Mode.
How To
Kafka Consumer Lag Explained: 6 Signals That Actually Matter
Raw consumer lag is the most-watched and most-misread Kafka metric. Six relational signals (lag shape, rebalance storms, partition skew, URPs, lag age against retention) tell you whether consumers will catch up or lose data.
How To
How to Triage Kafka Consumer Lag with Kafka's Native Tools
Triage Kafka consumer lag with tools that ship in every distribution: kafka-consumer-groups.sh, kafka-topics.sh, kafka-log-dirs.sh, consumer JMX metrics and the rebalancing timeout triangle, plus Confluent Cloud equivalents and one incident worked end to end.
Product
Automating Kafka Consumer Lag Response with AI Agents
CloudThinker connects to Kafka or Confluent Cloud read-only, watches lag shape, rebalances, skew and URPs continuously, and when a trend breaks it correlates with deploys and broker health and proposes the fix. Fixes go through Auto Mode; offset resets always need approval.
How To
Why Root Cause Analysis Takes Hours: The 3AM Dashboard Correlation Problem
In a typical 3 AM incident the fix takes four minutes and finding it takes two hours. This post follows one checkout latency spike phase by phase, shows why aggregated dashboards hide causal paths and non-deploy changes, and names the four gaps only continuous correlation closes.
How To
Building an Incident Response Workflow with Runbooks and Native Tools
Part 2 of the RCA series: build an incident response runbook system with tools you already run. A copyable runbook template, runbook_url wiring through Alertmanager, PagerDuty and Grafana OnCall, Grafana deploy annotations for 'what changed?', a CI gate for runbook coverage, and an honest look at where paper runbooks stop.
Product
Automated Root Cause Analysis with an AI SRE Agent: From Alert to Resolution
Runbooks need a human to start them and only cover incidents you've already had. Part 3 of the debugging trilogy walks one payment-api latency incident through CloudThinker Resolve: baseline detection, blast-radius triage, four hypotheses checked against the data, an approved rollback, and verified recovery in 18 minutes.
How To
AWS Cost Optimization: 7 Places Your Bill Is Leaking (and How to Find Them)
Your AWS bill grew 18% while traffic grew 6%. This guide shows how to split an unexplained increase into growth, waste and pricing drift in Cost Explorer, then covers the seven places AWS bills leak, each with a real CLI or console check and its typical cost.
How To
How to Audit Your AWS Costs with Native Tools (Cost Explorer, Trusted Advisor, Compute Optimizer)
A full AWS cost audit of all seven leaks using only Cost Explorer, Trusted Advisor, Compute Optimizer, CloudWatch and the CLI, with how to read each result. It includes one rightsizing recommendation verified end to end, and the four reasons a one-off audit can't be your strategy.
Product
Automating AWS Cost Optimization with an AI Agent: From Monthly Audits to Daily Savings
Monthly audits find NAT gateway waste three weeks late. This part shows how CloudThinker Optimize runs the seven AWS cost checks daily through a read-only role, verifies each finding before proposing a fix, and sends every delete, resize and purchase through Auto Mode.
How To
Kubernetes Cost Optimization: 6 Ways Your Cluster Leaks Money
Six places Kubernetes clusters leak money, from padded requests to orphaned volumes and static capacity, each with a detection command for EKS, GKE and AKS. Explains why the cloud bill can't show any of it: Kubernetes spends in requests, not usage.
How To
A DIY Kubernetes Cost Optimization Audit with Native Tools
A one-afternoon Kubernetes cost audit with kubectl top, kube-state-metrics, VPA in recommendation mode, autoscaler logs and the EKS, GKE and AKS cost views. Includes peak-utilization and wasted-core PromQL, and ends on the honest ceiling: every tool measures, none of them decides.
Product
Automating Kubernetes Cost Optimization with an AI Agent
How CloudThinker Optimize runs the Kubernetes cost audit daily over read-only RBAC, verifies each finding against peak demand and blockers, and proposes changes as PRs for approval. Walks one stale HPA floor from node-count jump to a proposed fix.
How To
GCP Cost Optimization: 7 Places Your Google Cloud Bill Is Leaking
Google Cloud already knows where you're wasting money. Nobody reads the findings. Seven places GCP bills leak, each with a gcloud command or console path, plus a worked example of tracing an unexplained Compute Engine increase in the BigQuery billing export.
How To
How to Audit Your GCP Costs with Native Tools (Billing Reports, Recommender, BigQuery Export)
A five-pass GCP cost audit with only Google's tools: Billing reports and CUD analysis, Recommender, Cloud Monitoring, the BigQuery billing export and gcloud sweeps. It includes one machine-type recommendation verified end to end before anyone resizes.
Product
Automating GCP Cost Optimization with an AI Agent
GCP waste scatters across forty projects nobody opens. CloudThinker Optimize reads every project daily through a read-only service account, verifies each finding before proposing a fix, and sends every change through Auto Mode.
How To
Azure Cost Optimization: 7 Places Your Bill Is Leaking (and How to Find Them)
Part one of the Azure cost series: the seven places Azure bills leak, grouped into three mechanisms (outlived resources, launch-day sizing, unmanaged meters), each with an az CLI command or portal path to find it and a typical recovery range. Ends on why monthly reviews can't keep up with waste that's generated every day.
How To
How to Audit Your Azure Costs with Native Tools (Cost Management, Advisor, Azure Monitor)
Part two of the Azure cost series: a full cost audit using only Cost Management, Azure Advisor, Azure Monitor and az CLI sweeps, run one tool at a time and covering all seven leaks. It's honest about where it stops: the audit goes stale on the day you finish it and fixes nothing by itself.
Product
Automating Azure Cost Optimization with an AI Agent
Part three of the Azure cost series: CloudThinker connects through a read-only service principal, scans all seven Azure leaks continuously, and works each finding from the evidence. For example, it can trace an overnight cost jump to an expired reservation with one Cost Management query. Every delete, resize or purchase goes through Auto Mode.
How To
PostgreSQL Performance Tuning: The 6 Metrics That Matter
Most PostgreSQL instance upgrades pay for a query that needed an index. Six metrics, one read-only detection query each, and the thresholds that turn a number into a finding.
How To
Hands-On PostgreSQL Performance Tuning with Native Tools Only
A half-day PostgreSQL audit using only what ships with Postgres: the slow query log, pg_stat_statements, EXPLAIN (ANALYZE, BUFFERS), index usage stats and auto_explain, plus a worked plan reading and where the DIY approach stops.
Product
Automating PostgreSQL Performance Tuning with an AI Database Agent
A month-end query slows 38x and the instinct is a bigger instance. This post walks through how CloudThinker tests four hypotheses against plans and statistics, finds stale stats instead, and proposes a fix that waits for your approval.
How To
MySQL Slow Query Guide: 5 Root Causes and How to Catch Each One
Almost every MySQL slow query traces back to one of five causes: missing indexes, full scans, bad joins, disk temp tables or lock contention. Each leaves a different fingerprint, with a detection query for each and a worked example of telling them apart from one slow log line.
How To
How to Triage MySQL Slow Queries with Native Tools Only
A complete MySQL slow query triage using only what ships with the server: a slow log that actually catches something, mysqldumpslow, performance_schema, the sys schema and EXPLAIN ANALYZE. It includes one suspect traced through all five tools and an honest look at where DIY triage stops.
Product
Automating MySQL Slow Query Triage with an AI Database Agent
CloudThinker connects to MySQL with a one-line read-only grant, baselines every query digest, and investigates regressions the day they ship. The worked example traces a deploy-day slowdown to an implicit cast via FIRST_SEEN in the digest table. Every index or query proposal comes with its evidence and waits for approval.
How To
MongoDB Performance: 5 Ways Fast Queries Turn Slow at Scale
MongoDB forgives bad decisions at 1 GB and charges for them at 100 GB. Five patterns behind most slow clusters, a symptom-to-cause triage table, and a native check for each one.
How To
MongoDB Performance Audit: The Profiler, explain, and $indexStats
A half-day MongoDB performance audit with tools you already have: the profiler, explain('executionStats'), $indexStats with hidden indexes, mongotop and mongostat, and Atlas Performance Advisor. Includes one slow query worked end to end.
Product
Automating MongoDB Performance Tuning with an AI Database Agent
Index advice expires as the workload moves. CloudThinker runs the profiler, explain and $indexStats audit continuously with read-only roles, works each regression end to end, and stages every index change for a named person to approve.
How To
Redis Monitoring: 6 Metrics That Decide If Your Cache Is Helping
Redis fails gradually and then suddenly. The six metrics that decide whether your cache is helping, what bad looks like for each, the redis-cli check that finds it, and how to read a latency spike by ruling out causes in order.
How To
Redis Monitoring with Native Tools: A Hands-On Performance Audit
A complete Redis performance audit with nothing but redis-cli: INFO, SLOWLOG, LATENCY, MEMORY and the keyspace scanners, in the order you'd run them, plus how to pick a maxmemory-policy that matches the workload.
Product
Automating Redis Monitoring with an AI Agent: From Graphs to Fixes
Dashboards showed the evictions climbing for three weeks and nobody acted. CloudThinker keeps a Redis baseline, connects drifting metrics to the deploy or key pattern behind them, and proposes TTL, policy and big-key fixes that wait for your approval.
How To
Datadog Automation: Fix Alert Fatigue and Monitor Sprawl First
Most Datadog automation projects fail before they start: 200-monitor estates where dozens of monitors sit muted or in No Data, flappy thresholds nobody trusts, and multi-alerts that turn one incident into forty pages. Part one of our Datadog observability series maps the anatomy of alert fatigue (monitor sprawl, flapping, fan-out) plus the over-ingestion costs (custom metric cardinality, log indexing) that prove unmanaged observability grows its own bill. Each pattern comes with a real API command or console path you can run today, and a picture of what good monitor hygiene looks like before you automate anything.
How To
Datadog Alert Automation with Native Tools (Monitors to Workflows)
Part two of the Datadog series builds everything native features allow: tuned and composite monitors, scheduled downtimes, event correlation, webhooks and Workflow Automation, with configs you can paste. Then it walks one composite alert through three hypotheses to show where workflows stop: they execute the branches you drew, they don't investigate.
Product
Datadog Automation with AI Agents: From Firing Monitor to Applied Fix
Part three of our Datadog automation series: the action layer on top of your alerts. Connect CloudThinker read-only with scoped API and application keys in about five minutes, then agents pick up firing monitors, investigate across metrics, logs, and APM, correlate with recent deploys, and propose or apply fixes under graduated autonomy (Notify, Suggest, Approve, Autonomous) with escalation and a full audit trail intact. Includes a realistic first-findings table covering flapping monitors, custom-metric cardinality, and indexed-but-unqueried logs, plus prompts to run during your next real incident.
How To
Grafana Alerting Automation: Closing the Dashboards-to-Action Gap
Dashboards only detect when someone is looking. Part one maps the five patterns that keep Grafana stuck at pretty graphs (inverted dashboard-to-rule ratio, sprawl, flapping, a catch-all policy, unlabeled rules), each with an API call to find it.
How To
Grafana Alerting Automation with Native Tools: A Hands-On Guide
Rules as code, a label-driven policy tree, webhooks, mute timings, silences and OnCall escalation, with provisioning files you can commit today. Then a 3 a.m. queue alert worked by hand shows why routing is not investigation.
Product
Grafana Alerting Automation: AI Agents That Investigate Firing Alerts
Grafana routed the Kafka disk alert in ninety seconds; diagnosis still took forty minutes. Part three shows CloudThinker querying through a Viewer service account, ruling readings in and out, and proposing the fix for approval.