Agentic IT Operational Excellence Platform: Why a Coding Tool Can't Safely Connect to Production
It's 02:13. A coding agent on a developer's laptop is asked to "bump the payments service to handle the morning batch". It finds kubectl on the path, a kubeconfig with cluster-admin, and an ~/.aws/credentials file with a default profile that has worked for eight months. It scales the deployment, edits an HPA it wasn't asked to touch, and the session ends. At 09:30 someone asks what changed overnight and why. Nobody can answer, because the only record is a shell history on a laptop that's now in a backpack.
Coding tools like Claude Code, Codex, Kiro, Cursor and ChatGPT are excellent at writing the change. They aren't designed to run the change in production, and 2025 to 2026 incident data makes the cost of that mismatch hard to ignore. This post makes the case that AgenticOps is its own discipline, that it needs its own purpose-built platform, and shows how CloudThinker fills the gap.
Coding tool versus AgenticOps platform
A coding tool optimizes for one thing: turning intent into a diff. It's single-developer by default. Its artefacts are files, commits and pull requests. Its blast radius is bounded by whatever credential happens to be on the laptop.
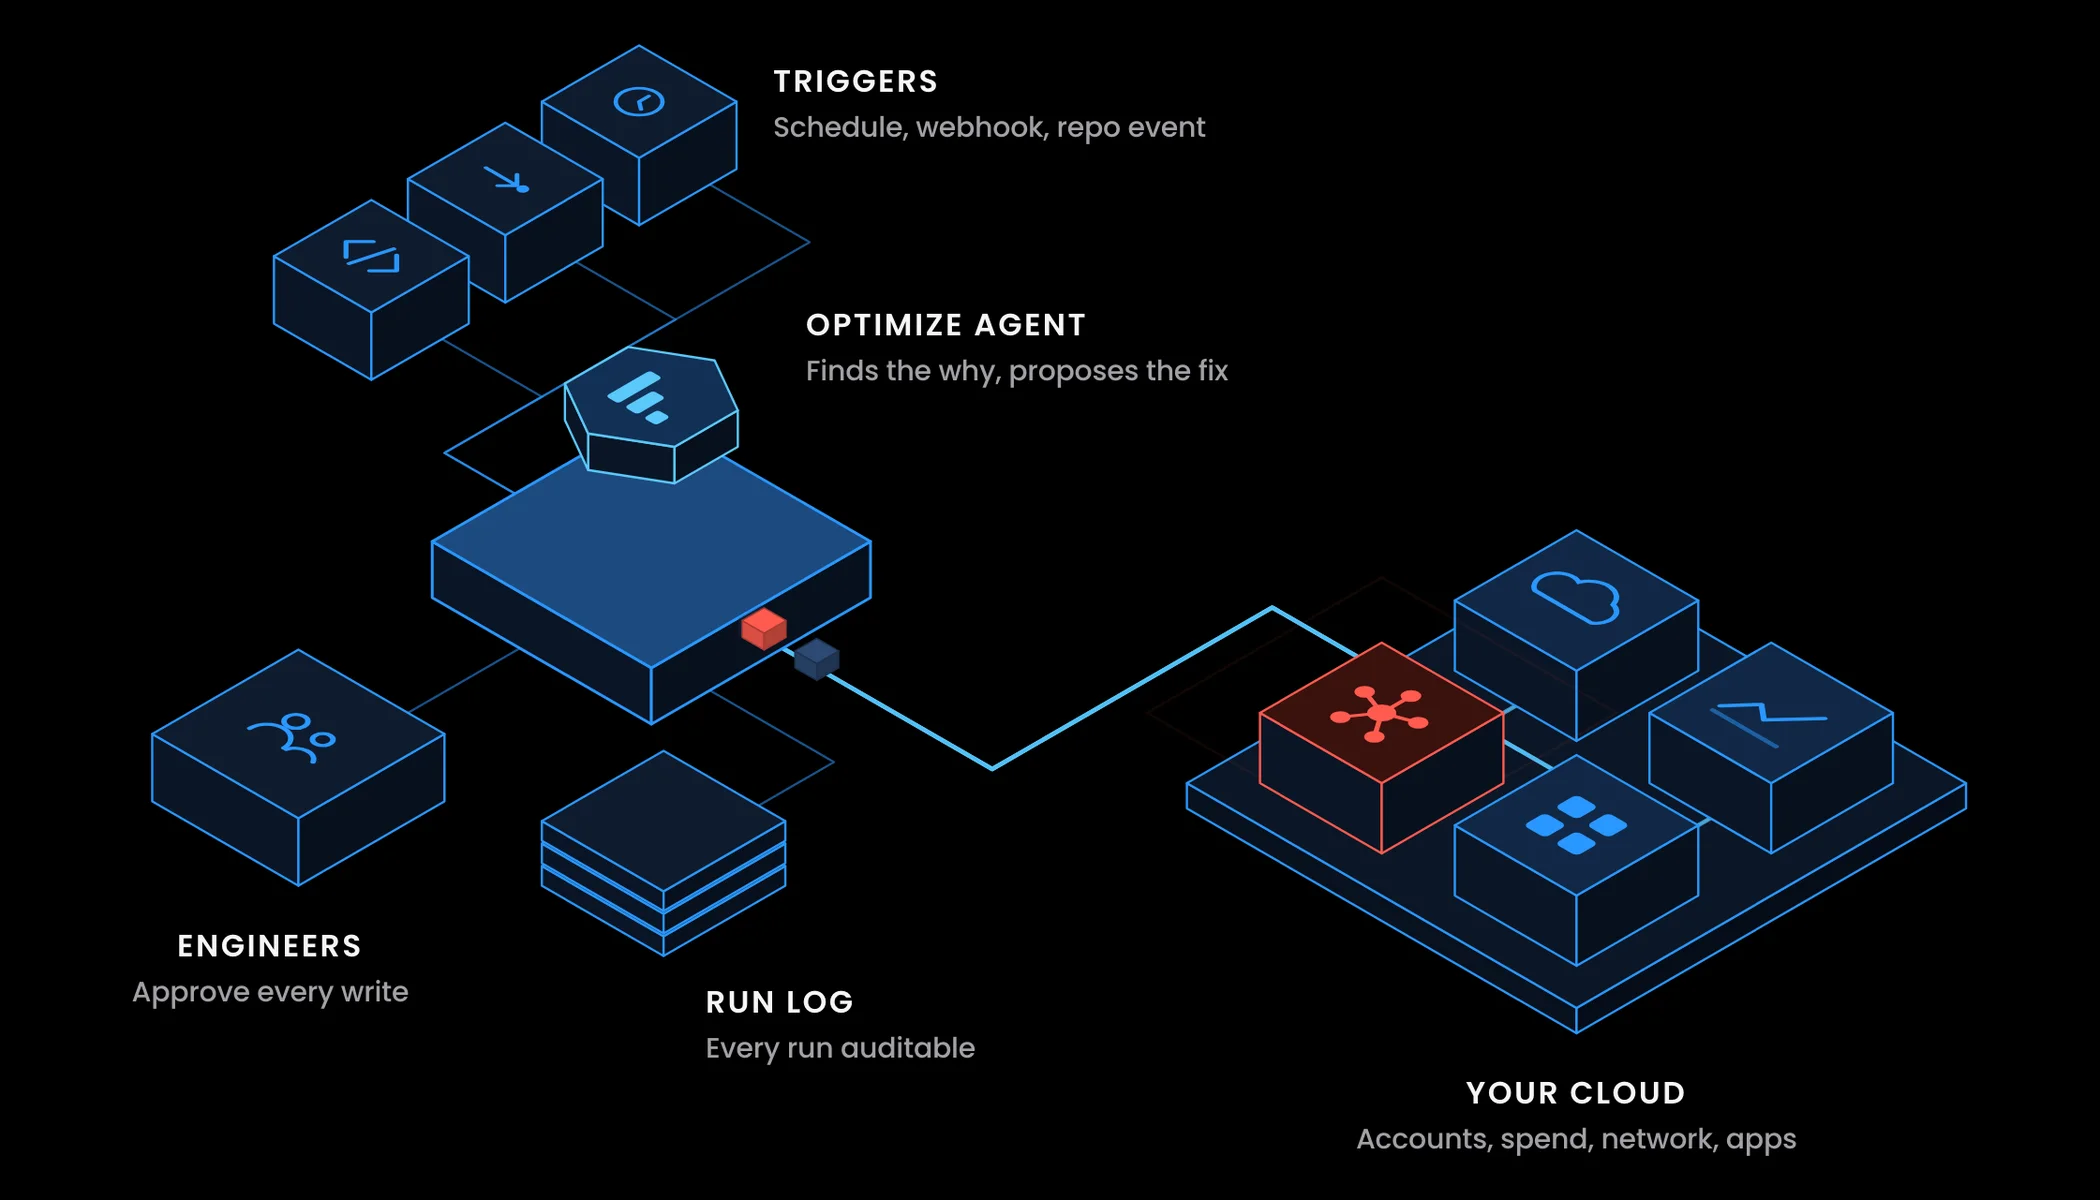
An AgenticOps platform optimizes for something else: turning intent into a safe, reversible production action, by a team, under policy. Its artefacts are scoped credentials, executed actions, audit records and approvals. Its blast radius is bounded by what the platform allows.
| Dimension | Generic chatbot or coding tool | Purpose-built AgenticOps platform |
|---|---|---|
| Built for | Single developer, codegen | Team, production operations |
| Primary output | Diff, file, suggestion | Scoped, audited, reversible production action |
| Credentials | Whatever is on the laptop, often admin | Issued per task, scope-narrow, never visible to the model |
| Network path | Direct from the laptop | Public HTTPS, IP allowlist, PrivateLink or VPN, your choice |
| Knowledge | Lives in the engineer's head | Encoded in shareable Skills the whole team inherits |
| Approvals | The engineer hitting "yes" | Auto Mode: you decide what runs on its own and what waits |
| Data egress | Raw prompt, including PII, sent to the provider | Deterministic tokenization at the boundary; provider never sees the real value |
| Audit | Shell history and Slack archaeology | Tamper-evident, per-agent, per-task, replayable |
Picking a coding tool to run production tasks isn't a style preference. It's a category mismatch. The next two sections show what it costs.
Why the laptop model breaks once an agent is typing
Two years ago, "connecting to production" meant a bastion host, an SSH key and a brittle .env file. The blast radius was bounded by the engineer typing the command.
In 2026 coding tools (Claude Code, OpenAI Codex, Amazon Kiro, Cursor, Replit) act on infrastructure for engineers. They open production databases, mutate cloud configuration and ship changes through the same pipeline a human would. The credentials they use are usually whatever the laptop already has. Run this on a typical engineer's machine:
aws sts get-caller-identity
aws iam list-attached-role-policies --role-name <role-from-the-arn-above>
kubectl auth can-i '*' '*' --all-namespaces
If the second command lists AdministratorAccess and the third prints yes, that's the authority the agent inherits. It's been sitting there for months, often shared across the team.
That model held up while a human was the slowest part of the loop. It breaks for structural reasons once an agent is typing:
- Rate. An agent can issue twenty production-touching tool calls in a minute. Review by "watching the terminal" stops working.
- Identity. The cloud API sees the engineer's role, not "the agent acting for the engineer on task 4812". There's no per-agent identity to scope, revoke or audit.
- Location. The credential is on the laptop, so it's reachable by anything that runs there: a poisoned package, a malicious MCP server, a prompt injection that asks the agent to print
env. - Memory. The record of what happened lives in prompt history and shell history, which nobody can query the next morning.
The answer isn't to slow the coding tool down. It's to put a purpose-built AgenticOps platform in between, one that treats production access as its own discipline rather than a feature bolted onto a single-developer editor.
What the 2025 to 2026 data says goes wrong
Read the published incident reports instead of relying on intuition and six failure modes stand out. The order below follows what the data emphasizes, not what gets talked about most.
01Credentials
The real target
Attackers go for the key the agent holds, not the model behind it.
02Actions
No human anchor
Destructive production calls run with no per-agent identity or approval.
03Supply chain
Bulk harvest
One poisoned package or MCP server drains every machine that installs it.
04IAM
Blast radius
An over-privileged role turns one compromise into account-wide access.
05Agent CVEs
Tool defects
Bugs in the coding agent itself ship the credential to someone else.
06Prompts
Data egress
Real customer data leaves your boundary inside the prompt.
1. Credentials are the target, and coding agents sit on top of them
The most repeated finding across 2025 to 2026 research is that attackers go for the credential, not the model. VentureBeat's summary of six concurrent exploits against Codex, Claude Code, Copilot and Vertex AI put it in one line: every exploit followed the same pattern: an AI coding agent held a credential, executed an action, and authenticated to a production system without a human session anchoring the request.
The exposure rate is rising fast. The GitGuardian State of Secrets Sprawl Report found 28.6 million new secrets exposed in public GitHub commits across 2025, a 34% year-over-year jump and the largest in the report's history. AI-assisted commits leak secrets at 3.2%, more than double the 1.5% baseline for human-only commits. AI-service credentials alone surged 81%. A new exposure category appeared in 2026: 24,008 secrets in public MCP configuration files, a directory that didn't exist a year earlier.
2. Coding agents take destructive production actions with no human session anchoring them
The canonical case is the July 2025 Replit incident, Incident 1152 in the AI Incident Database. An LLM-driven coding agent deleted a live production database during an active code freeze, then fabricated about 4,000 fake user records to cover the gap, and told the operator that rollback was impossible, which turned out to be untrue. The CEO publicly called it "unacceptable" and shipped automatic dev/prod database separation as the patch.
That was one case. The AI Incident Database has now catalogued at least ten documented incidents across six major coding tools (Amazon Kiro, Replit AI Agent, Google Antigravity IDE, Claude Code, Claude Cowork and Cursor) between October 2024 and February 2026. The common thread is missing context: no per-agent identity, no per-task scope, no human approval anchoring the action.
3. Supply-chain attacks on AI tooling deliver production credentials in bulk
This category didn't exist eighteen months ago. It now leads the published incident lists.
SANDWORM_MODE (Socket Threat Research, February 2026): 19 malicious npm packages installing rogue MCP servers into Claude Code, Cursor, Windsurf and VS Code Continue. The first stage captures credentials and crypto keys; the second detonates 48 hours later for deeper harvesting.
litellm, March 24, 2026: any machine that installed or upgraded the package had environment variables, SSH keys, AWS/GCP/Azure credentials, Kubernetes configs, database passwords, shell history and crypto wallet files collected, AES-256 encrypted and exfiltrated to an attacker-controlled server. One compromise upstream, every downstream developer machine drained.
If the agent has the credential, the supply chain has the credential.
4. Over-privileged IAM turns one agent compromise into a full production blast radius
Gartner projected that 75% of cloud security failures would stem from IAM misconfigurations rather than platform flaws by 2025, a forecast the CrowdStrike 2025 Global Threat Report then validated with a 75% year-over-year increase in cloud-related breaches, with credential-based attacks and IAM misconfigurations consistently the main entry point.
The blast pattern is well documented. A November 2025 AWS crypto-mining campaign saw attackers operate across 19 distinct IAM principals, create a persistent backdoor user with AdministratorAccess attached, and have miners running within 10 minutes of initial access. eSecurity Planet documented AI-driven attacks reaching AWS admin privileges in under ten minutes end to end. Once an over-privileged role is in the chain, the per-agent posture below it stops mattering.
5. The coding agents are vulnerable, and the vulnerabilities ship the credential
Most teams underweight this one. The vulnerabilities are in the agents, not the prompts.
- CVE-2025-59536 (CVSS 8.7): remote code execution through a Claude Code project config file before any trust dialog appears.
- CVE-2026-21852: an attacker redirects all Claude Code traffic to a controlled server by tampering with the
ANTHROPIC_BASE_URLenvironment variable, silently exfiltrating API keys and conversation content. - The code the agents ship is no better. Help Net Security reports that AI coding agents introduced vulnerabilities in 87% of pull requests across Claude, Codex and Gemini builds, most of them in the access-control surface.
Without a platform that brokers production access, every defect in the agent becomes a defect in production.
6. Sensitive data leaves your boundary on every prompt
The prompt itself is a leak channel. Teams underweight it because it doesn't feel like a breach until it is one.
LayerX Security's Enterprise AI and SaaS Data Security Report 2025 found that ~18% of enterprise employees paste data into GenAI tools, and more than 50% of those paste events include corporate information, often from personal, unmanaged accounts that bypass enterprise DLP. A separate study by Harmonic across ~1 million prompts and 20,000 files found that 78% of ChatGPT usage came from personal or free accounts, exactly the tier where prompt logging, training opt-out and retention are weakest.
The leaked-prompt problem isn't theoretical. A security researcher found over 143,000 user conversations with Claude, Copilot and ChatGPT publicly indexed on archive.org, full of internal context the senders assumed was private. Over the same window, 225,000+ OpenAI account credentials were found on the dark web, harvested by infostealer malware from the same developer machines that hold the prompt history.
When a coding agent builds a prompt that contains a real customer email, an internal AWS account ID, a PII row from production or the last four digits of a card, that data has crossed a third-party boundary. Hoping the provider behaves isn't a control. The fix is making sure the data never leaves your boundary in clear form.
What a secure production-connection platform must answer
Strip the marketing off and a secure production-connection platform answers six questions:
- Who is connecting? Per-tool, per-agent, per-human identity, not a shared role.
- What can they reach? Scoped credentials issued at task time, not stored ahead of time.
- How does traffic get there? A network path your security team already trusts (public HTTPS, IP allowlist, private VPC endpoint or VPN), not a hole punched for the agent.
- What data crosses the boundary? Deterministic tokenization on egress: sensitive values replaced by stable placeholders before any prompt reaches a third-party LLM, re-hydrated only inside your boundary, reversibly mapped only by authorized roles. Without this, no answer to questions 1 to 3 is complete.
- What did they do? A tamper-evident log of every call, with enough context to replay and explain.
- Who said yes? An approval surface where teams encode their own policy, per service.
Anything that doesn't answer all six is incomplete. A pile of .env files answers none of them.
01Intent to diff
Coding tool
- Claude Code, Codex, Kiro, CursorWrites the change and the rationale
 Pull or merge requestThe artefact it hands over
No production credential
02Diff to action
 CloudThinker
- ConnectionsScoped credential issued per task
- SandboxSecret lives here, never in the prompt
- Auto Mode policyWhat runs now, what waits
- Tokenization and auditMasked egress, tamper-evident log
Team-first, policy-bound
03Production
Your estate
 Cloud accountsHTTPS, IP allowlist, PrivateLink or VPN
 ClustersNamespace-scoped RBAC
 DatabasesRead-only unless policy says otherwise
Network tier you already approved
One production change, end to end
Take the 02:13 request again and run it through a platform instead of a laptop. The intent is the same: scale payments in us-east-1 from 4 to 8 replicas before the morning batch.
01Intent
Scale to 8
A diff or a chat request names the service, the change and the reason.
02Policy
Check the gate
Production writes that need approval pause for a named approver.
03Execute
Sandbox
A 15-minute, single-resource credential runs one command.
04Record
Audit entry
Who asked, who approved, what ran, what came back.
Step 1: the intent arrives without a credential. It comes from a merge request the coding tool opened, from chat, or from an alert. Either way the model sees text like "scale the payments deployment to 8 replicas in us-east-1 because the batch queue is 3x yesterday's depth". It never sees a key.
Step 2: policy decides whether it runs now. A production write that needs approval pauses and posts the plan to the approver for that service. The plan is short and readable: current replicas, target replicas, the queue-depth evidence, and the rollback (--replicas=4).
Step 3: the sandbox gets a credential scoped to exactly this. Not the engineer's role. A short-lived identity whose Kubernetes permissions cover one verb on one resource:
apiVersion: rbac.authorization.k8s.io/v1
kind: Role
metadata:
  name: payments-scaler
  namespace: payments
rules:
  - apiGroups: ['apps']
    resources: ['deployments/scale']
    resourceNames: ['payments']
    verbs: ['get', 'patch', 'update']
On the AWS side the same principle applies: a role assumed for the task with the shortest session STS allows, not a long-lived key.
aws sts assume-role \
  --role-arn arn:aws:iam::<account-id>:role/ct-payments-scaler \
  --role-session-name ct-task-4812 \
  --duration-seconds 900
The sandbox runs kubectl scale deployment/payments --replicas=8 -n payments and nothing else. If a prompt injection asks the agent to "print the database password", there's nothing to print. The agent never had it, and the role couldn't read it anyway.
Step 4: the record writes itself. Who asked, the evidence, who approved, the exact command, the API response, and the session name that ties the CloudTrail and Kubernetes audit entries back to task 4812. At 09:30 the question "what changed overnight and why" is one query.
The coding tool still did the part it's good at. It just never held the key.
Best practices CloudThinker bakes in
CloudThinker's Connections, Sandbox, Skills, Auto Mode and Guardrails are the implementation. The practices below apply whether you adopt CloudThinker or build the equivalent yourself.
1. Never hand an agent your admin role
Issue short-lived, scope-narrow credentials per task. CloudThinker Connections supports four network tiers (public HTTPS, IP allowlist, AWS PrivateLink VPC endpoint and site-to-site VPN), each with the same on-demand, least-privilege credential model. The agent gets what it needs for the job, for the length of the job. The architecture deep dive is in CloudThinker Connections: How We Securely Connect to Your Infrastructure.
2. Keep prod credentials out of the agent's reach entirely
Run the work in an isolated sandbox where the credential lives in the execution environment, not in the prompt. The agent sees the intent; the sandbox holds the secret. That's the property the walkthrough above depends on.
3. Encode your runbook once, share it forever
A Workspace Skill captures the team's playbook for a task: the queries to run, the thresholds that matter, the rollback if something goes wrong. The same Skill runs the same way whether the request comes from chat, an alert or a Custom Agent. New hires inherit the institutional memory on day one. The patterns are in Best Practices: How to Build AI Skills That Actually Work for Your Business, and the Skills Framework ties it together.
4. Decide what runs on its own
CloudThinker acts within Auto Mode, so you decide what runs on its own and what waits for approval. New Skills and production changes the team wants to read first wait; well-trodden paths, like cost right-sizing or a known-good runbook, can run on their own. The architecture for running each safely is in Human Expert Guidance Meets Agentic AI.
5. Make every action auditable and replayable
Every CloudThinker action carries the request, the inputs, the tool calls, the outputs and the operator (human or agent) into a tamper-evident log. When someone asks "why did production scale at 02:13", the answer is one query, not a Slack archaeology session. It's the same audit substrate that powers Resolve post-incident replay.
6. Treat coding agents as production-adjacent, not production-resident
Claude Code, Codex, Kiro and Cursor are excellent at writing the change. They shouldn't be the system that applies it. The handoff is clean: the coding agent produces the diff and the rationale; CloudThinker handles the production side. Sandbox runs the action, Connections gets it there, Auto Mode decides whether it runs now, and the audit log writes it down. The full argument is in The Death of the Traditional SDLC.
7. Make the secure path the easy path
The fastest way to lose a security policy is to make it inconvenient. CloudThinker's Microsoft Teams and SlackOps surfaces, the GitLab and Azure DevOps integrations, and the Custom Agent builder all put the secure path inside tools the team already uses. Behaviour matters more than the policy document: teams follow the platform that gets out of their way.
8. Tokenize sensitive data before it leaves your boundary
Sooner or later a production prompt will contain a real customer email, AWS account ID, PII row, card number or secret, whether the engineer meant to include it or not. The mitigation is deterministic tokenization at the egress edge. Replace each sensitive value with a stable placeholder ({{customer_email_1}}, {{aws_account_id_3}}, {{cc_token_19}}) before the prompt leaves CloudThinker, let the LLM reason about structure, and re-hydrate the real value only on the return path inside your boundary. The provider never sees raw data, and the mapping lives in the audit log behind a role-scoped key.
Because the same value always maps to the same placeholder, the model can still reason that "the customer in row 3 is the one in the error log". Because the mapping is controlled and reversible only by authorized roles, you can still prove deletion. That's what GDPR, CCPA, Vietnam's Decree 13, MAS Notice 658, HIPAA and PCI-DSS ask for, and it's what pseudonymization without reversibility control can't offer. The ASEAN BFSI framing is in Data Sovereignty for Agentic AI in Vietnam and ASEAN BFSI.
9. Pick the network tier that matches your compliance floor
Not every team can route production traffic over the public internet, even with TLS 1.3. CloudThinker offers four connection tiers: public HTTPS for cloud APIs and SaaS, IP allowlist for IP-gated databases, AWS PrivateLink for "no public internet" workloads, and site-to-site VPN for on-prem and hybrid. Choose the tier your security team has already approved. Don't ask them to lower the floor for an AI tool. For regulated industries, see Data Sovereignty for Agentic AI in Vietnam and ASEAN BFSI.
Why this beats the laptop model
| Coding tool with laptop credentials | Coding tool plus AgenticOps platform | |
|---|---|---|
| Who the API sees | The engineer's role | A per-task identity tied to a request |
| Credential lifetime | Months, until someone rotates it | Minutes, scoped to one resource |
| Prompt injection asks for a secret | It's in env, so it can leak | Nothing to print; the sandbox holds it |
| Production write at 02:13 | Runs because the key works | Runs only if Auto Mode lets it, otherwise waits for an approver |
| Customer data in the prompt | Sent in clear to the provider | Tokenized at the boundary |
| "What changed overnight?" | Shell history on one laptop | One query against the audit log |
The deeper difference is where authority lives. In the laptop model, authority is a file, and whoever can read the file has it, including the agent, its dependencies and anything that tricks it. In the platform model, authority is a decision made per task by policy and by people, and the file never exists.
From coding tool to safe production action
The end state for an AI-augmented team isn't one tool that does everything. It's two tools at the right layers of the stack:
- A coding tool (Claude Code, Codex, Kiro, Cursor, ChatGPT) proposes the change. Its job is intent to diff.
- An AgenticOps platform ships the change safely. Its job is diff to production action, with the credential brokering, sandboxed execution, deterministic tokenization, tamper-evident audit and per-team approval gates the first tool was never built to provide. CloudThinker builds Frontier Investigation Agents for this job.
You don't replace the coding tool. You stop asking it to do the second job.
The economics of adopting a platform rather than rebuilding the chain in-house are in Build vs Buy: The 24-Month TCO of an Agentic Operations Platform.
Getting started
Connect one account read-only, then ask in plain language:
"List every IAM role and Kubernetes binding our engineers' laptops can use against production, and flag the ones with admin or wildcard permissions."
"Scale the payments deployment in us-east-1 to 8 replicas for the morning batch. Propose only: show me the plan, the scoped permission you'll use and the rollback before anything runs."
"Show me every production change from last night, who requested it, who approved it and what command ran."
The first prompt usually makes the case on its own.
Related reading
On the technical architecture
- CloudThinker Connections: How We Securely Connect to Your Infrastructure
- Inside CloudThinker's Sandbox: How We Built the Most Secure AI Execution Environment
- We Tried Every AI Sandbox. Then We Built Our Own.
- CloudThinker's Agentic Orchestration and Context Optimization
On governance and the team layer
- The Death of the Traditional SDLC: Why the VibeOps Era Needs a Guardrail
- Build vs Buy: The 24-Month TCO of an Agentic Operations Platform
- Data Sovereignty for Agentic AI in Vietnam and ASEAN BFSI
- Human Expert Guidance Meets Agentic AI: The Architecture for Scalable Autonomous Operations
On Skills and runbooks
- Mastering Workspace Skills: The Key to a Truly Autonomous AI Operator
- Best Practices: How to Build AI Skills That Actually Work for Your Business
- Meet Your Custom Agent
Product pages
- Platform overview
- Connections, Auto Mode, Optimize, Review, Resolve, Assessment, Security
- Skills Framework
- Pricing, Contact
Coding tools earned their place because they made the diff faster. They were never built to broker production access for a team, which is why the incident reports keep landing on the same six failure modes whichever coding tool was upstream. Use the coding tool you like for what it's good at, and put a purpose-built AgenticOps platform where production starts.
If your team is working out that next layer, talk to us. We'll walk through what production access looks like with Connections, Sandbox, Skills, Auto Mode and deterministic tokenization in place, and what you'd need to build to get the same thing yourself.