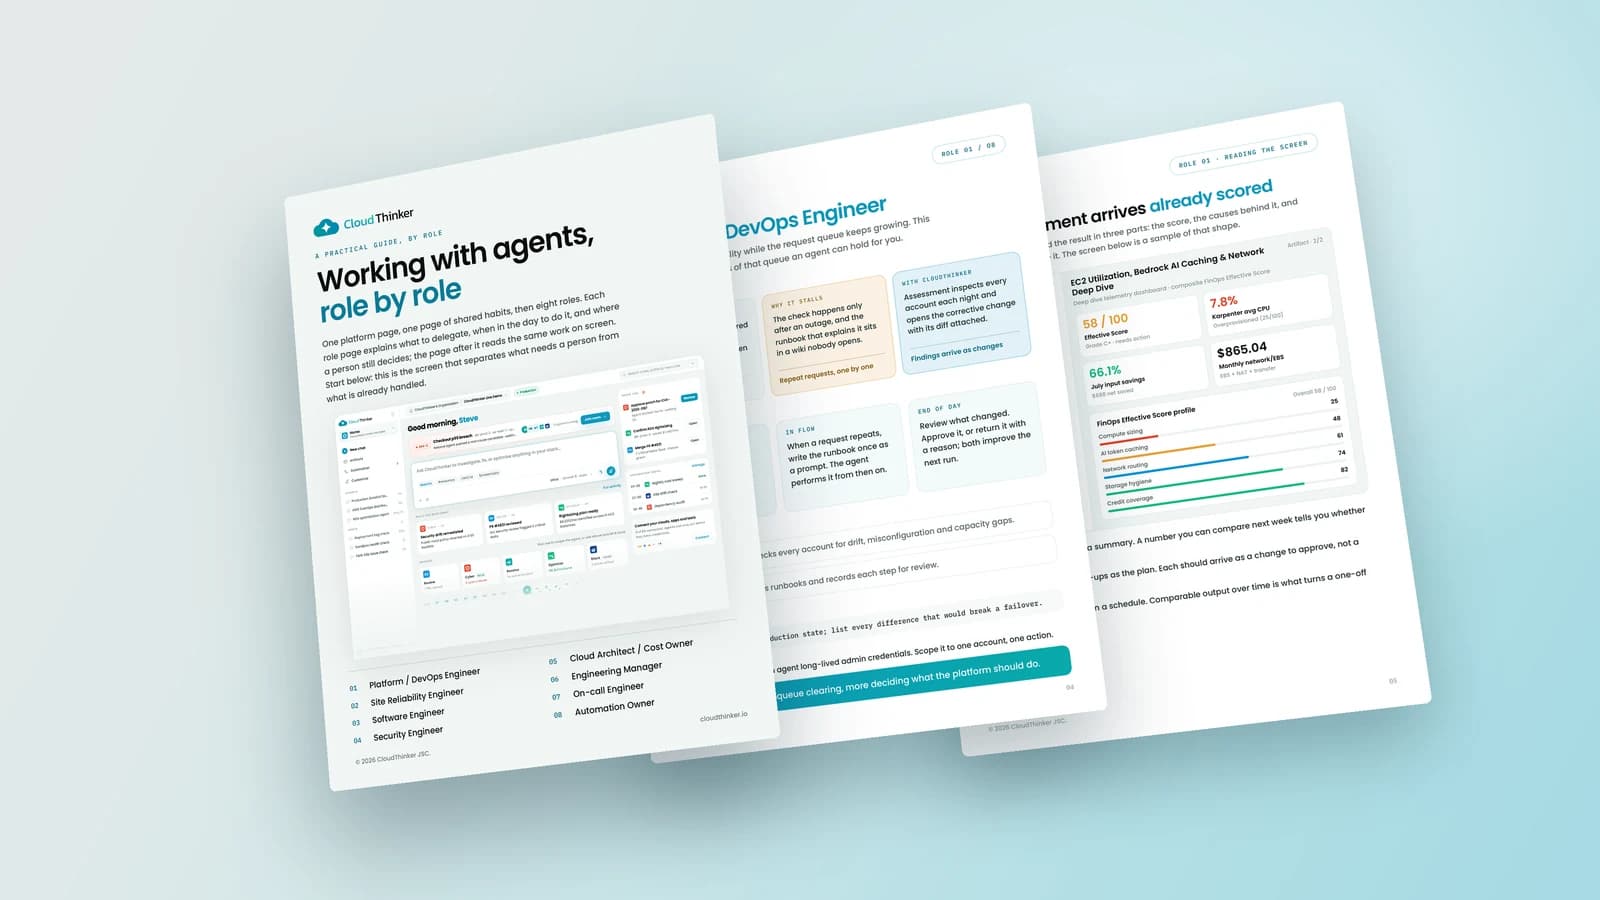
Working with agents, role by role: a new practical guide
It's the Monday after an agent rollout. The connections are live, leadership has signed off, and the agents are producing findings. An SRE opens the console and sees forty proposed alert-rule changes. A security engineer sees a backlog that shrank overnight and can't tell whether exposure shrank with it. An engineering manager sees a dashboard of agent activity and has no idea whether it means the team is faster. Each of them closes the tab and goes back to the queue they know.
Most material about AI agents in operations is written for the person deciding whether to buy one. Very little is written for the person who has to open the console on Monday morning and get through their queue.
That gap shows up in every rollout we run. Eight people doing eight different jobs each have to work out for themselves what "using agents" means for their day. The SRE's answer looks nothing like the security engineer's. The engineering manager's looks nothing like either.
So we wrote the guide for them. Working with agents, role by role is a 19-page practical guide: one chapter on the platform, one chapter of shared habits, then eight roles. It's free, readable in full on the web, and downloadable as a PDF in English and Vietnamese.
Why generic agent advice stalls rollouts
Rollouts rarely fail on the technology. They stall in the first few weeks, for reasons that are structural rather than personal:
- The unit of advice is wrong. "Delegate toil to agents" means something different to a person whose toil is alert triage and a person whose toil is cost reports. Advice pitched at "the team" lands on nobody's actual queue.
- Approval habits aren't taught. People are handed an approve button without being shown what a good plan looks like. They either approve things they can't read or refuse everything.
- The wrong thing gets measured. Agent volume is easy to count, so it becomes the metric, and it says almost nothing about whether work moves faster.
- Autonomy arrives as a setting. An admin turns it up, something surprising happens, and trust resets to zero.
The guide is built to fix those four things, one role at a time.
What's in it
The guide is deliberately narrow. It doesn't argue that you should adopt agentic operations; we've written that argument elsewhere. It assumes you already have agents connected and answers a much more concrete question: which part of your specific queue can an agent hold, and which part stays yours?
Each of the eight role chapters follows the same four-part shape:
01Change
How work shifts
How the task is done today, why it stalls, what an agent changes.
02Day
Where it happens
Morning, in flow, end of day: the moments delegation fits.
03Delegate
What to hand over
The two most relevant agents and the exact sentence to start with.
04Mistake
What goes wrong
The failure mode we see most in that role, named plainly.
- How this work changes: how the task is done today, why it stalls, and what changes with an agent in the loop.
- What the day looks like: morning, in flow, end of day. Where delegation actually happens in a working day.
- What to delegate: the two agents most relevant to that role, and the exact sentence to type to get started.
- The common mistake: the failure mode we see most often in that role, named plainly.
Every role chapter ends with a real product screen and three notes on how to read it, because a habit only sticks if it survives contact with the console.
The eight roles
| Role | The question it answers |
|---|---|
| Platform / DevOps Engineer | Which part of a growing request queue can an agent hold? |
| Site Reliability Engineer | How do you keep availability without answering every alert at 2am? |
| Software Engineer | What should be checked before a human reads your diff? |
| Security Engineer | How do you tell less real exposure from a smaller backlog? |
| Cloud Architect / Cost Owner | How do you see architecture and cost at the same time? |
| Engineering Manager | Where do you read system state without asking people to write status? |
| On-call Engineer | How do you spend a pager week on real failures? |
| Automation Owner | What work qualifies for automation, and who has to own it? |
The opening sentences in the chapters are plain language, not commands. A few in the spirit of the guide:
"Before I read this merge request, check it against the incidents and cost changes for the services it touches, and list anything I should look at first."
"Group last night's alerts by likely cause, show the evidence for each, and tell me which ones were noise. Propose only, change nothing."
"Which findings closed this week reduced real exposure, and which only closed because the resource was deleted or the rule was suppressed?"
Three habits that run through all of them
Before the role chapters there's a short chapter on habits. These three showed up in enough engagements that we stopped treating them as advice and started treating them as prerequisites.
01Choose
Delegate repetition
The second time you write the same query or comment, hand it over.
02Review
Read the decision
Ask for the plan and the evidence before you approve an action.
03Correct
Send it back
Write down why it was wrong, so the next attempt is narrower.
Delegate repetition, keep judgement. Repetition is the signal to look for. The second time you write the same runbook, review comment or query, that task is a candidate for an agent. Not the hardest task. The most repeated one.
Review the decision, not the keystrokes. Ask for the plan and the evidence before approving an action. Reading a plan takes a minute and teaches you how the agent reasons. Teams that skip this either approve things they can't read or refuse to approve anything; both stall the rollout.
Send it back with a reason. When output is wrong, write down why. The reason narrows the next attempt. A silent rejection guarantees the same work comes back next week, unchanged.
The measure that actually matters
The guide makes one argument more than once, so here it is again:
Time is saved where work stops waiting on a person, not where prompts get longer.
That's why the Engineering Manager chapter tells managers to stop counting agent volume. Volume is easy to report and tells you almost nothing. The number that shows whether any of this is working is waiting time (how long a change sat idle because it needed a person to look at it) and its companion, repeat work: anything a person did twice that an agent could have owned.
| Counting agent activity | Counting waiting time and repeat work | |
|---|---|---|
| What it rewards | More prompts, more output | Fewer handoffs that sit idle |
| A busy week of agents | Looks like progress | Only counts if approvals got faster |
| A four-day approval queue | Invisible | The first thing on the report |
| What managers ask people for | Status updates | Nothing; the state is readable |
A rollout where agents did ten thousand things and people still wait four days for an approval hasn't moved. A rollout where agents did far less but nothing waits has.
How much autonomy, and when
The guide is opinionated about pace, and it's slower than most vendor material:
01Week one
Read-only
Agents observe and report. You compare their conclusions with yours.
02Then
Propose
Agents draft the change and stop. A named person approves every write.
03Steady state
Act
Agents act on their own where you allow it. Anything else waits for approval.
- Week one: read-only. Agents observe and report. Compare their conclusions with yours to learn where they're reliable.
- Then: propose and wait. Agents draft the change and stop. A named person approves before anything lands, so mistakes stay cheap.
- Steady state: act in a boundary. Agents act within Auto Mode, so you decide what runs on its own and what waits for approval, and every action leaves a trail you can read afterwards.
This maps onto graduated autonomy in the product, but the guide frames it as something a team earns rather than something an admin configures. The sample screens in the book reflect that honestly. The Engineering Manager roll-up shows zero incidents closed with no human touch, because at that stage of the rollout every change still waits for approval by choice.
Read it or download it
The whole guide is readable on the web, chapter by chapter, with no download and no gate on the reading. If you want the designed PDF to circulate internally or hand out at a workshop, it's available in English and Tiếng Việt from the same page.
If you're setting strategy rather than doing the work, the Leadership Edition covers the executive case, and the Engineer Edition goes deep on the harness: context engineering, safety, policy as code and evaluation. All three live together in the eBooks library.